Computer Vision MT25, Ethics and privacy
Flashcards
Why is it not sufficient to omit sensitive features (e.g. race) from an ML model used to make decisions?
Other features may correlate with the sensitive features.
Suppose:
- $Y$ is a target variable (e.g. recidivism)
- $R$ is the output of a classifier
- $A$ is a sensitive attribute
@Define the fairness-related “independence” condition in this context.
The classifier response is independent from the sensitive attribute, i.e.
\[\mathbb P(R \mid A) = \mathbb P(R)\]Suppose:
- $Y$ is a target variable (e.g. recidivism)
- $R$ is the output of a classifier
- $A$ is a sensitive attribute
@Define the fairness-related “separation” condition in this context.
The classifier response is conditionally independent from the sensitive attribute given the target, i.e.
\[\mathbb P(R, A \mid Y) = \mathbb P(R \mid Y) \mathbb P(A \mid Y)\]Suppose:
- $Y$ is a target variable (e.g. recidivism)
- $R$ is the output of a classifier
- $A$ is a sensitive attribute
Then the fairness-related “separation” condition in this context is that the classifier response is conditionally independent from the sensitive attribute given the target, i.e.
\[\mathbb P(R, A \mid Y) = \mathbb P(R \mid Y) \mathbb P(A \mid Y)\]
What does this entail in terms of the error rates of the classifier?
All groups (delineated by $A$) experience the same false negative and false positive rate.
Proof: Separation says $R$ is conditionally independent of $A$ given $Y$. Combining the stated factorisation with the chain rule $\mathbb P(R, A \mid Y) = \mathbb P(R \mid Y, A)\,\mathbb P(A \mid Y)$ and cancelling $\mathbb P(A \mid Y) > 0$ gives
\[\mathbb P(R \mid Y, A) = \mathbb P(R \mid Y),\]so the prediction depends on the target alone, not the group. Reading off the two error rates for any group $A = a$ (binary $Y, R$):
- FPR: $\mathbb P(R = 1 \mid Y = 0, A = a) = \mathbb P(R = 1 \mid Y = 0)$,
- FNR: $\mathbb P(R = 0 \mid Y = 1, A = a) = \mathbb P(R = 0 \mid Y = 1)$.
Both right-hand sides are independent of $a$, so every group shares the same FPR and the same FNR. $\square$
Suppose:
- $Y$ is a target variable (e.g. recidivism)
- $R$ is the output of a classifier
- $A$ is a sensitive attribute
Then we have the fairness conditions:
- Independence: $\mathbb P(R, A) = \mathbb P(R) \mathbb P(A)$
- Separation: $\mathbb P(R, A \mid Y) = \mathbb P(R \mid Y) \mathbb P(A \mid Y)$
@State an unfortunate theorem in this context.
Suppose further:
- $Y$ is binary
- $A$ is not independent of $Y$
- $R$ is not independent of $Y$
Then:
- Both independence and separation cannot hold simultaneously.
With $Y$ binary, $R$ the classifier output and $A$ a sensitive attribute, suppose $A \not\perp Y$ and $R \not\perp Y$. @Prove the impossibility result (∆independence-separation-incompatibility): independence ($R \perp A$) and separation ($R \perp A \mid Y$) cannot both hold.
Proof: Suppose both hold. Write $r _ y := \mathbb P(R = 1 \mid Y = y)$ and $q _ a := \mathbb P(Y = 1 \mid A = a)$. Condition $R = 1$ on group $a$ and expand over the binary $Y$:
\[\mathbb P(R = 1 \mid A = a) = \sum _ y \mathbb P(R = 1 \mid Y = y, A = a)\, \mathbb P(Y = y \mid A = a) = r _ 0 + (r _ 1 - r _ 0)\, q _ a,\]where separation let us replace $\mathbb P(R = 1 \mid Y = y, A = a)$ by $r _ y$ (free of $a$), and $Y$ binary gave $\mathbb P(Y = 0 \mid A = a) = 1 - q _ a$.
By independence the left side is constant in $a$, so $(r _ 1 - r _ 0)\, q _ a$ is constant in $a$. But $A \not\perp Y$ with $Y$ binary means $q _ a$ is not constant in $a$, forcing $r _ 1 = r _ 0$, i.e.
\[\mathbb P(R = 1 \mid Y = 1) = \mathbb P(R = 1 \mid Y = 0) \iff R \perp Y,\]contradicting $R \not\perp Y$. (Running the same argument for each value of $R$ removes the binary-$R$ assumption.) $\square$
@Define allocative harms in the context of ML-decision making.
Harms caused by a system allocating resources unfairly.
@Define representational harms in the context of ML-decision making, and give 5 distinct types of such harms.
Where a system reinforces harmful stereotypes.
- Recognition: A group is erased or made invisible.
- Under-representation: A group is under-represented.
- Denigration: Use of culturally disparaging terms.
- Ex-nomination: Representing ideology as common sense.
- Stereotype: Reinforces negative stereotypes.
(Mnemonic: RUDES).
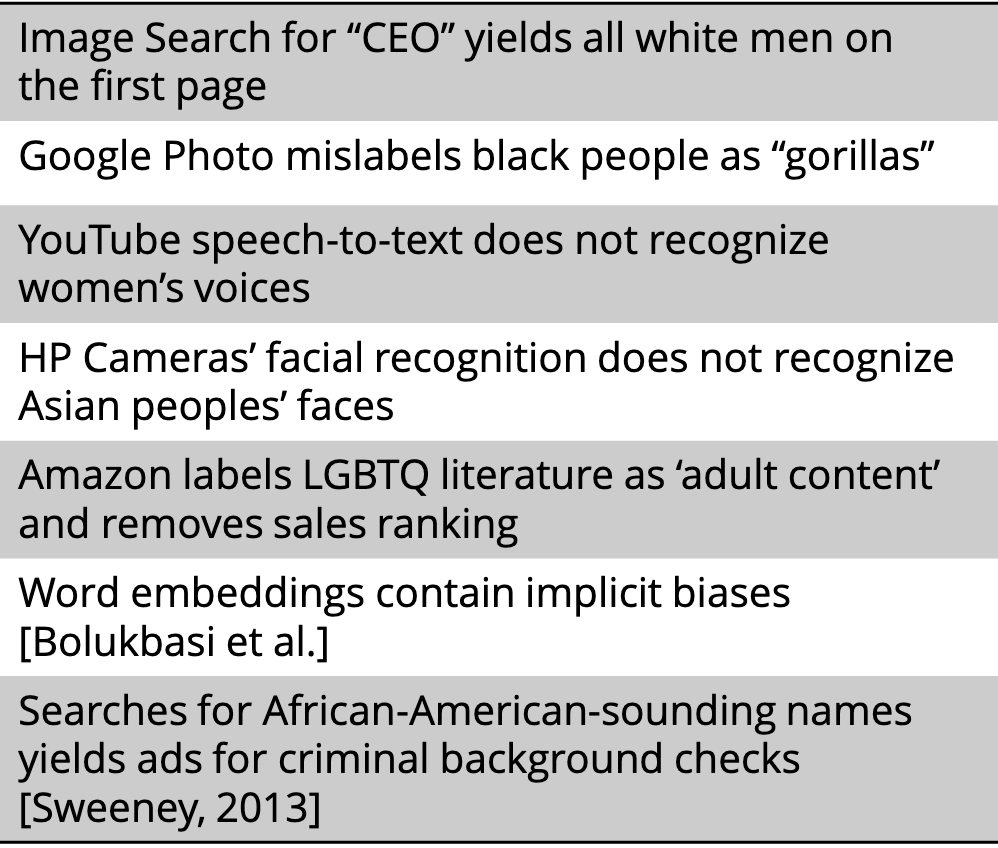
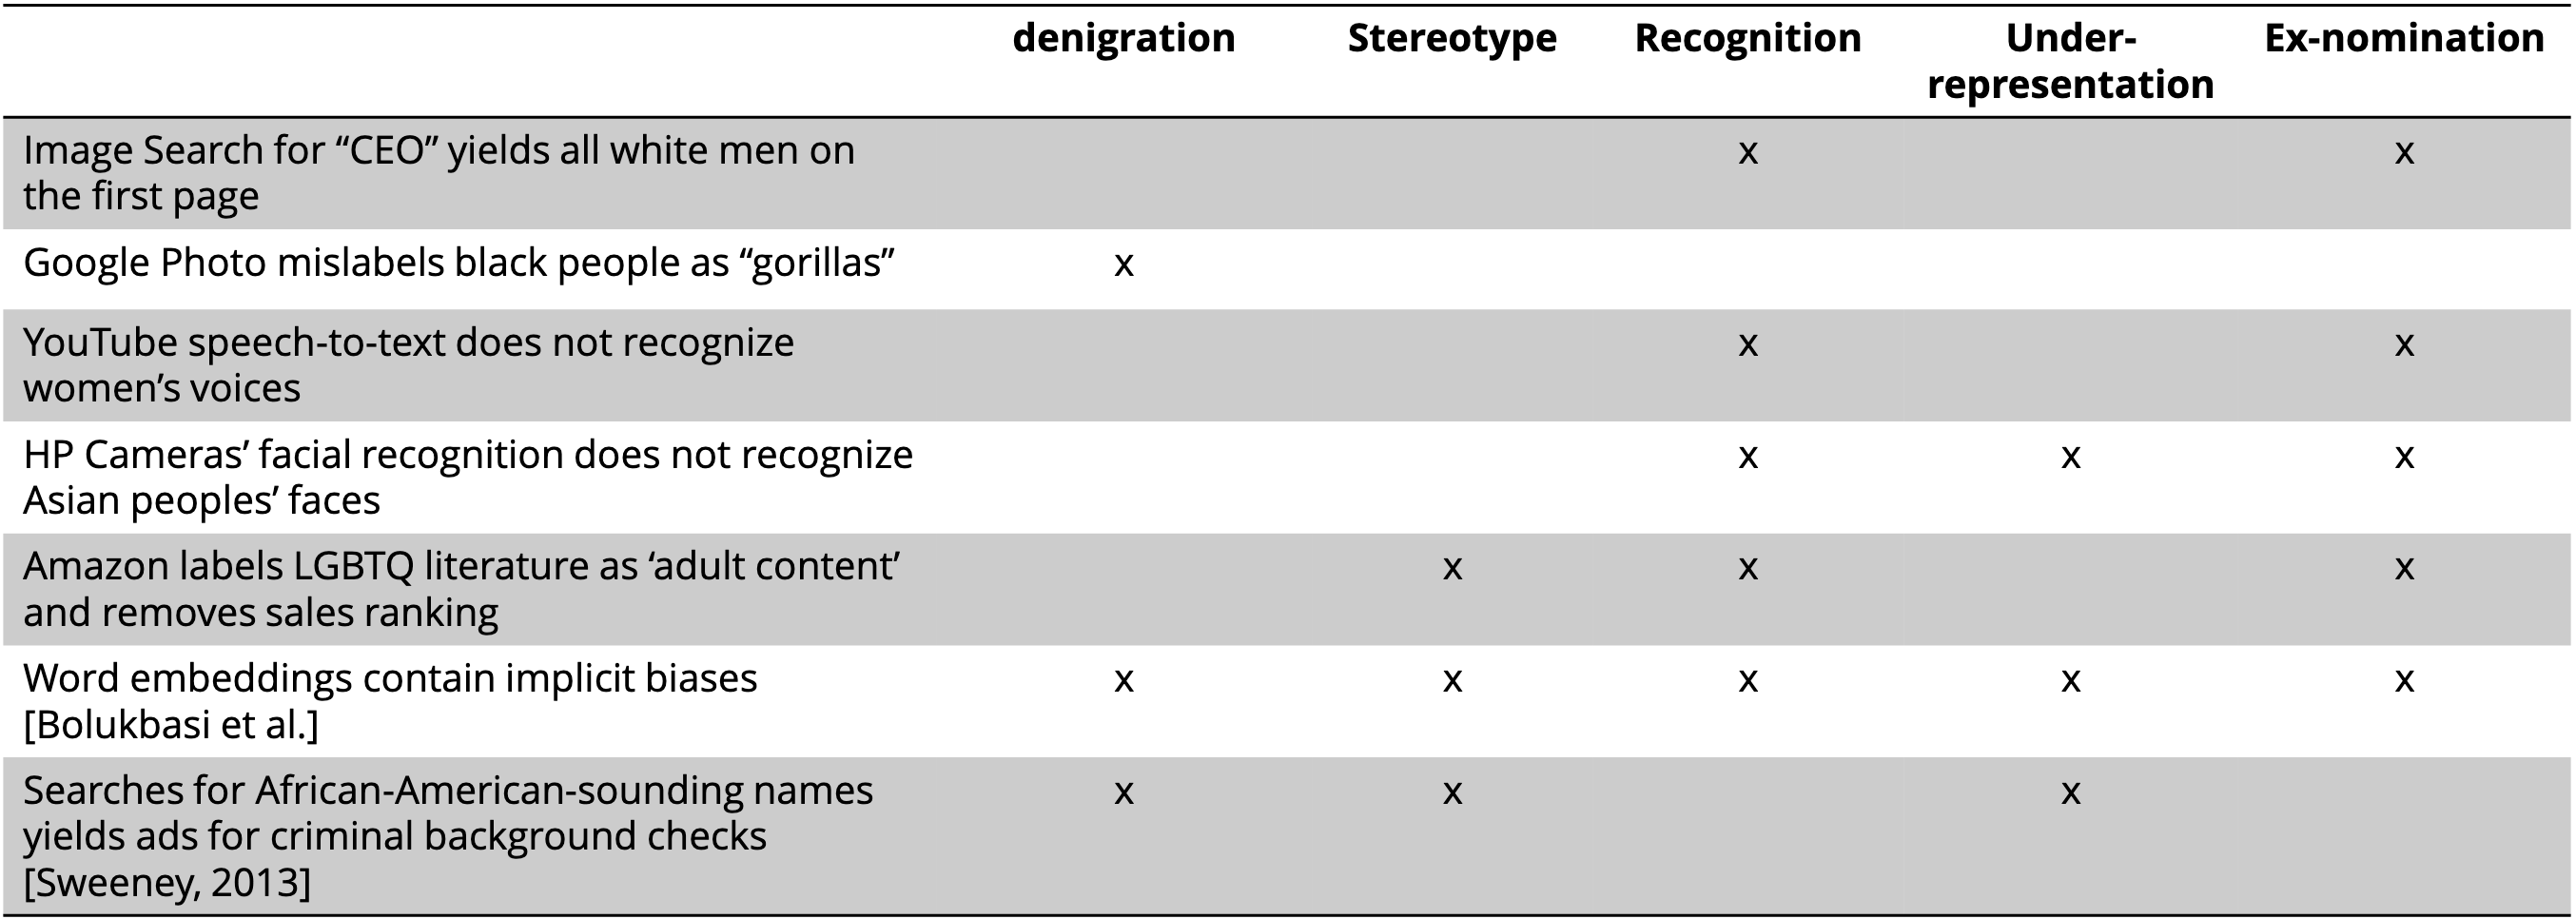
Can you classify these representational harms into the (potentially simultaneous) categories of:
- denigration
- stereotype
- recognition
- under-representation
- ex-nomination
@Define the gender bias of a category $C$.
@Define the bias amplification problem in classification.
Recall the gender bias of a category $C$:
\[\frac{\text{total number of perceived male instances of }C}{\text{total number of instances of }C}\]Bias amplification is the observation that the predicted gender ratio on the test data can actually exceed the true training gender ratio (perhaps because accuracy-maximisation on imbalanced data optimally predicts the majority, or the model picks up shortcut features).
Bite-sized
For a binary classifier with confusion-matrix counts $\mathrm{TP}, \mathrm{FP}, \mathrm{FN}, \mathrm{TN}$:
- Error rate $= <span class="cloze" tabindex="0">\dfrac{\mathrm{FP} + \mathrm{FN</span>{\mathrm{TP} + \mathrm{TN} + \mathrm{FP} + \mathrm{FN}} }}$
- False Positive Rate $= <span class="cloze" tabindex="0">\dfrac{\mathrm{FP</span>{\mathrm{FP} + \mathrm{TN}} }}$
- False Negative Rate $= <span class="cloze" tabindex="0">\dfrac{\mathrm{FN</span>{\mathrm{FN} + \mathrm{TP}} }}$
@Justify which stakeholders in the COMPAS recidivism setting are most concerned about FPR vs FNR.
- Defendants care about False Positive Rate $= \mathrm{FP} / (\mathrm{FP} + \mathrm{TN})$, the rate at which non-offenders are wrongly predicted to reoffend. A high FPR means innocent-of-reoffence defendants get long sentences.
- Judges (and the legal system more broadly) care about False Negative Rate $= \mathrm{FN} / (\mathrm{FN} + \mathrm{TP})$, the rate at which true reoffenders are wrongly predicted to be low-risk. A high FNR means released defendants commit more crimes.
These two stakeholder concerns are in tension — driving FPR down (favouring defendants) typically raises FNR (worsening for judges), and vice versa.
ProPublica’s 2016 analysis of COMPAS scores in Broward County, Florida (sample size $> 7000$) found that the overall error rate ($\approx 34.6\%$) and FPR/FNR were similar across white and black defendants, but disaggregated:
- Black defendants: FPR $\approx <span class="cloze" tabindex="0">44.9\%</span>$, FNR $\approx 28.0\%$.
- White defendants: FPR $\approx <span class="cloze" tabindex="0">23.5\%</span>$, FNR $\approx 47.7\%$.
So black defendants had ~$1.9\times$ higher FPR while white defendants had ~$1.7\times$ higher FNR — and this happens even though COMPAS does not take race as an input.
Buolamwini & Gebru’s Gender Shades study (FAT* 2018) showed an intersectional accuracy disparity in commercial gender-classification systems (MSFT, Face++, IBM): error rates ranged from $\sim 0\text{--}1\%$ for light male faces to $\sim 20\text{--}35\%$ for dark female faces. Notably the intersectional category “dark female” was much worse than any single-axis category (female, male, light, or dark) alone — showing that single-axis fairness audits miss intersectional disparities.
Zhao et al. (EMNLP 2017, “Men Also Like Shopping”) empirically showed bias amplification: a CNN trained on COCO multi-label classification produces predictions whose gender ratios are more skewed than those of the training data. Their headline example: snowboards are $\sim 90\%$ male in the training data, but the trained classifier predicts them as male even more often. Implication: simply debiasing the training data is not enough; the model itself amplifies bias.
@Define Datasheets for Datasets and Model Cards, and name their motivating papers.
- Datasheets for Datasets (Gebru et al., FAccT 2018): a standard list of questions to answer when releasing a dataset — who created it, why, what is in it, who labelled the images and how, etc. Aim is to give downstream users enough context to assess fit-for-purpose.
- Model Cards (Mitchell et al., FAccT 2019): a standard list of questions to answer when releasing a trained model — intended use, factors, metrics, evaluation/training data, quantitative analyses, ethical considerations, caveats. Importantly, Model Cards include explicit out-of-scope use cases (e.g. the CLIP model card states “any deployed use case is currently out of scope”).
Both have been adopted in practice by Google and (sometimes) OpenAI.
@Describe the CelebA attribute critique as a worked example of subjective labelling.
CelebA (Liu et al., ICCV 2015) tags each of 202k face images with 40 binary attributes. Many of these attributes are deeply subjective: Attractive, Big _ Lips, Big _ Nose, Chubby, Heavy _ Makeup, High _ Cheekbones, Narrow _ Eyes, Oval _ Face, Pointy _ Nose, Wavy _ Hair, Young — and, notably, Male (treated as binary).
The critique asks: who chose these attributes? Why these and not others? How are they operationally defined? Who actually labelled the images? The paper’s answers are very thin: “annotated by a professional labeling company”. No annotator guidelines, no inter-annotator agreement, no demographic breakdown of labellers. Yet thousands of downstream papers train and evaluate face models against these labels as if they were objective.
This is the standard exam-relevant example of subjective labelling masquerading as ground truth.
The CLIP Model Card explicitly states that any deployed use case (whether commercial or not) is currently out of scope, and that surveillance / facial recognition use cases are always out of scope regardless of model performance. This is the canonical example of a Model Card distinguishing research-only release from production deployment.
The non-examinable LAION-5B episode demonstrates a Model-Card breakdown: the CLIP Model Card says don’t deploy CLIP in production, yet the LAION-5B dataset was filtered using CLIP. A subsequent investigation (Stanford, Dec 2023) found hundreds of CSAM (child sexual abuse material) images in LAION-5B that the CLIP filter had failed to remove.
Lecture 20 cites Arvind Narayanan’s tutorial “21 fairness definitions and their politics” to make the point that there is no single mathematical definition of fairness — different definitions reflect different political and ethical commitments, and it is generally impossible to satisfy all of them simultaneously (cf. the two-criterion impossibility of independence + separation).
@Describe how visual prompt engineering (specifically the “red circle” trick) can dramatically change a VLM’s zero-shot classification.
Drawing a coloured annotation (e.g. a red circle) on an image steers a VLM’s global descriptor toward the annotated region. The lecture’s worked example: an image of a camouflaged owl on a tree trunk.
- Without annotation: CLIP classifies the image as “tree” with confidence $\sim 0.443$ and assigns negligible mass to “owl”.
- With a red circle drawn around the owl: CLIP’s confidence for “owl” rises to $\sim 0.925$.
Caveat from the lecture: the same trick steers the model toward whatever the circle highlights, including stereotypes — the same setup that fixes the owl can also bias a model toward labelling a circled face as “missing person” or “murderer”. So the technique is powerful but also reveals training-data biases.
The PASS dataset (Asano et al., NeurIPS Datasets&Benchmarks 2021) is a 1.4M-image dataset deliberately containing zero humans (and 1.4M associated license files). It was shown to give comparable performance to ImageNet for MoCo-v2 self-supervised pre-training on detection, segmentation and dense-pose tasks — demonstrating that strong representations can be learned without faces or persons in the training set, sidestepping consent issues.