Computer Vision MT25, Generative models
Flashcards
@State the general setup of a generative model.
We have some dataset $\mathcal D = \{ x _ i \mid 1 \le i \le N \}$ which is assumed to come from some underlying distribution $p _ \text{data}(x)$. We aim to learn a distribution $p _ \text{model}(x)$ we can sample from so that $p _ \text{data}$ and $p _ \text{model}$ are similar.
What is the difference between discriminative, generative and conditional generative models?
- Discriminative: $p(y \mid x)$
- Generative: $p(x)$
- Conditional generative: $p(x \mid y)$.
@Justify how Bayes’ rule lets you build generative $p(x)$ models from other components (a discriminative model, a prior and a conditional generative model).
Consider the following form of Bayes rule:
\[p(x \mid y) = \frac{p(y \mid x) p(x)}{p(y)}\]Here:
- $p(x \mid y)$ is a conditional generative model
- $p(y \mid x)$ is a discriminative model
- $p(y)$ is a prior over labels
- $p(x)$ is a generative model
In a generative model, we have some dataset $\mathcal D = \{ x _ i \mid 1 \le i \le N \}$ which is assumed to come from some underlying distribution $p _ \text{data}(x)$. We aim to learn a distribution $p _ \text{model}(x)$ we can sample from so that $p _ \text{data}$ and $p _ \text{model}$ are similar.
In this context, what is the difference between an explicit and an implicit generative model?
- Explicit: We obtain some representation of $p _ \text{model}(x)$ and can determine the density of samples
- Implicit: We may sample from $p _ \text{model}(x)$ but cannot determine the density of samples exactly
The setup of a generative model is to learn $p _ \text{model}(x)$ to match $p _ \text{data}(x)$ given samples (∆generative-model-setup). Models split along two axes: whether they let us compute $p(\pmb x)$ for a given sample (∆generative-explicit-vs-implicit), and how they generate samples.
@State a taxonomy of generative methods, naming the major families.
- Explicit models :
- Tractable density: Autoregressive models, factorise $p(\pmb x) = \prod _ i p(x _ i \mid x _ {< i})$ and evaluate exactly.
- Approximate density: VAEs, bound $p(\pmb x)$ via an evidence lower bound, optimised through an encoder-decoder pair.
- Implicit models:
- Direct sampling:
- GANs: a generator network and a discriminator network, trained adversarially
- Diffusion models: produce samples via iterative denoising from Gaussian noise
- Markov chain:
- GSNs (not covered explicitly in the course)
- Direct sampling:
What’s the main idea behind autoregressive distribution estimation for a generative image model?
- Convert the image into a sequence of pixels
- Predict the sequence of pixels by factorising the joint distribution into a series of one-dimensional distributions that only depends on the previous pixels
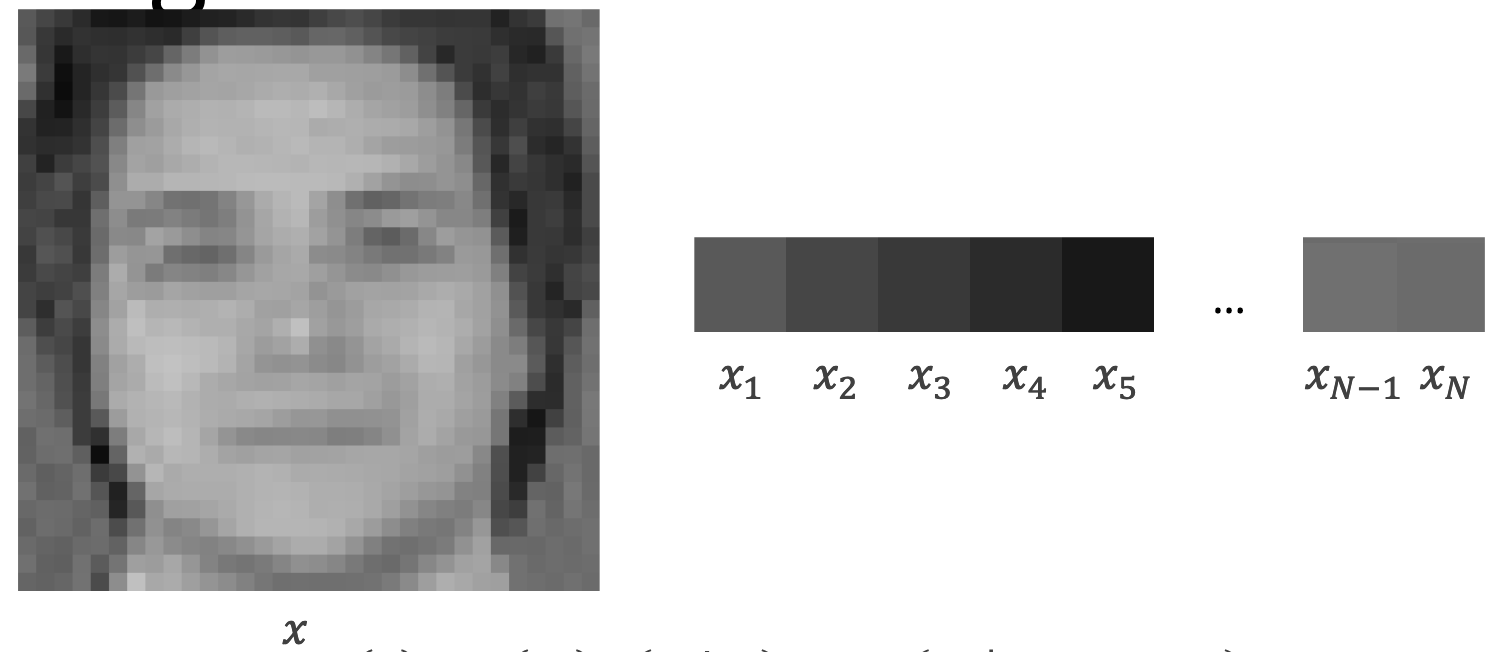
How would autoregressive distribution estimation for image generation factorise the joint distribution $p(x)$?
@Visualise the architecture for autoregressive distribution estimation.
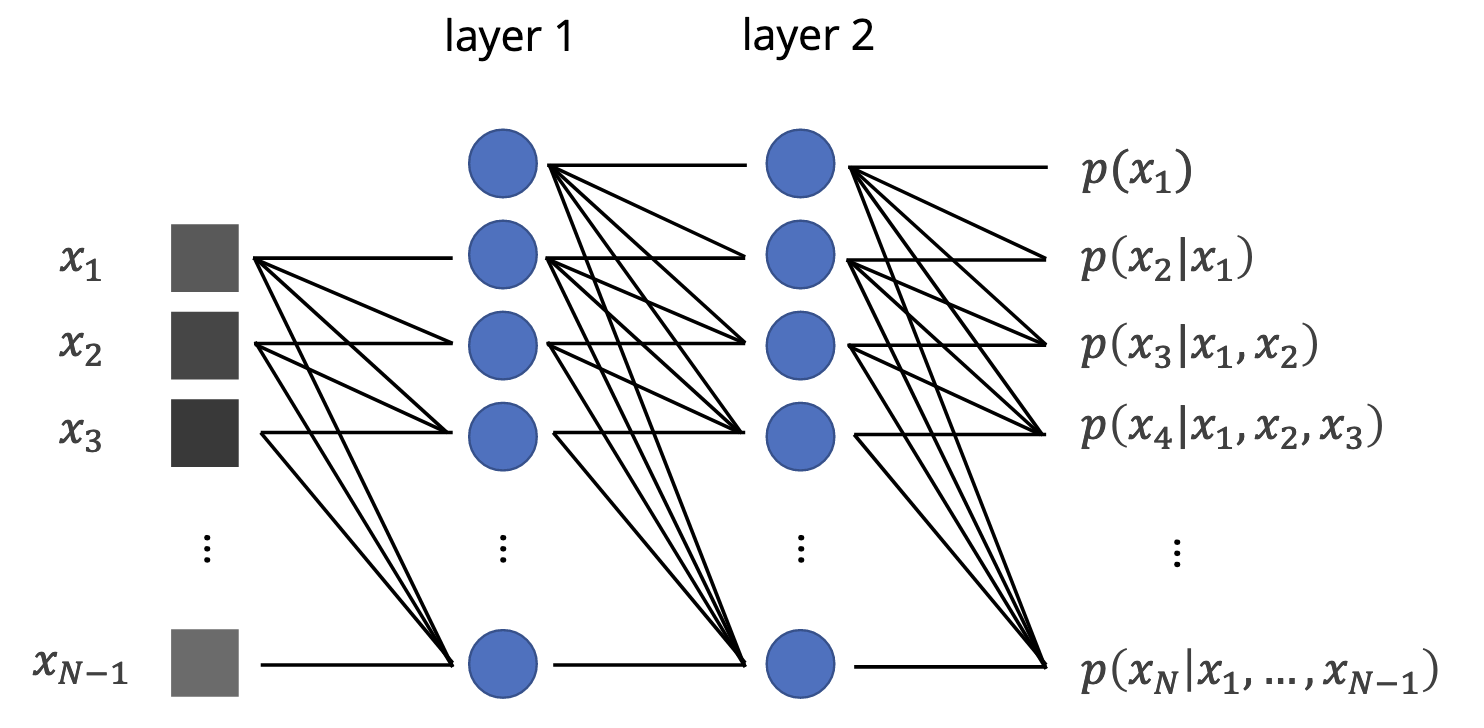
One approach to autoregressive distribution estimation for image generation might use an architecture like this:
Why do you have to take care about which neurons are connected to one another?
In order to preserve the autoregressive property, predictions are not allowed to depend on the future pixels, otherwise a model could cheat.
@Visualise the masks used in an autoregressive image generation CNN, and explain why this has to be done.
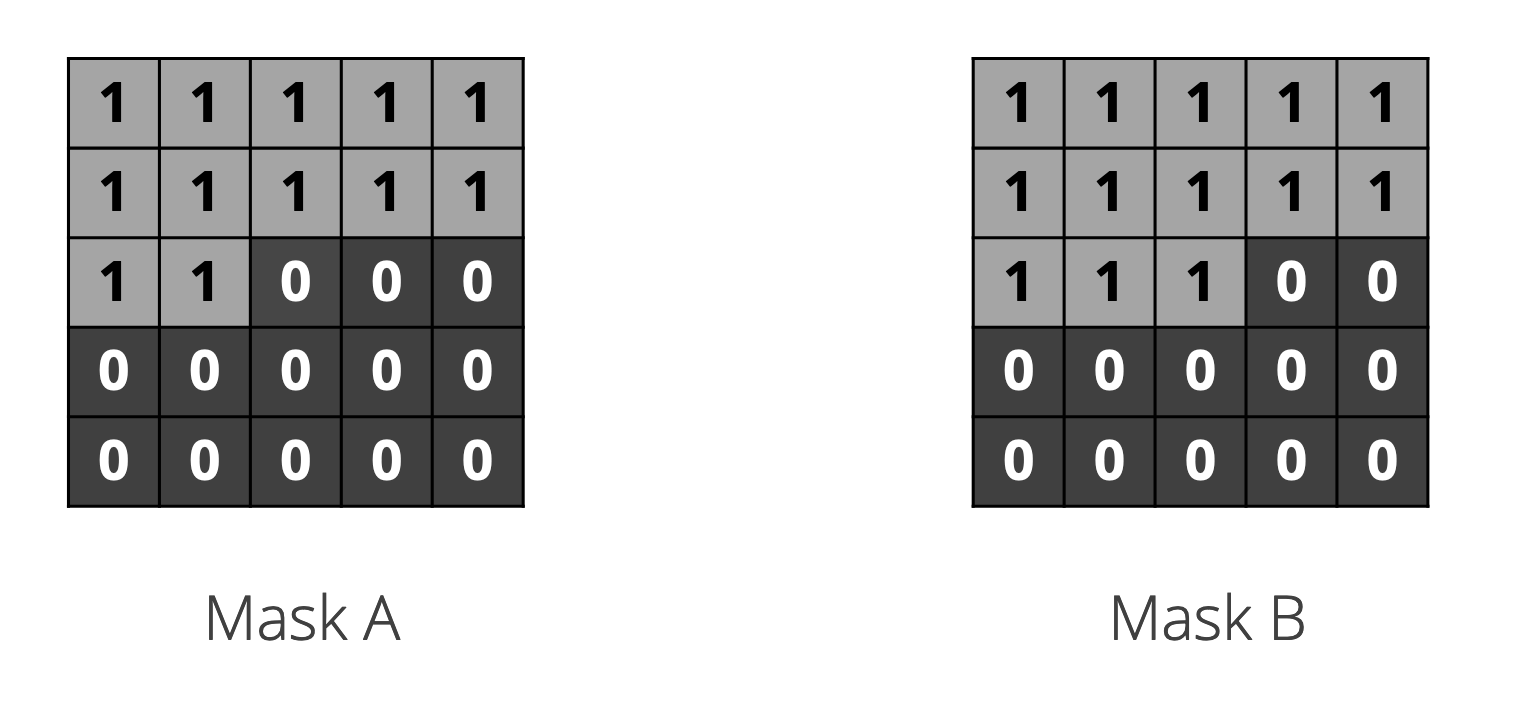
You need to preserve the autoregressive property that the prediction for a pixel is not allowed to depend on the values of the next pixels. Mask A is used for the first layer, and Mask B is used for all subsequent layers.
The difference between having a $0$ or $1$ in the middle of the mask is due to the centre of the computed features after the first layer now longer not conveying information about the next pixels.
How did DALL-E improve on the standard autoregressive image generation model?
It instead generated the images auto-regressively in “token-space”, using tokens learned by a VQ-VAE.
@Visualise the architecture of a VQ-VAE. How do they work in high-level terms?
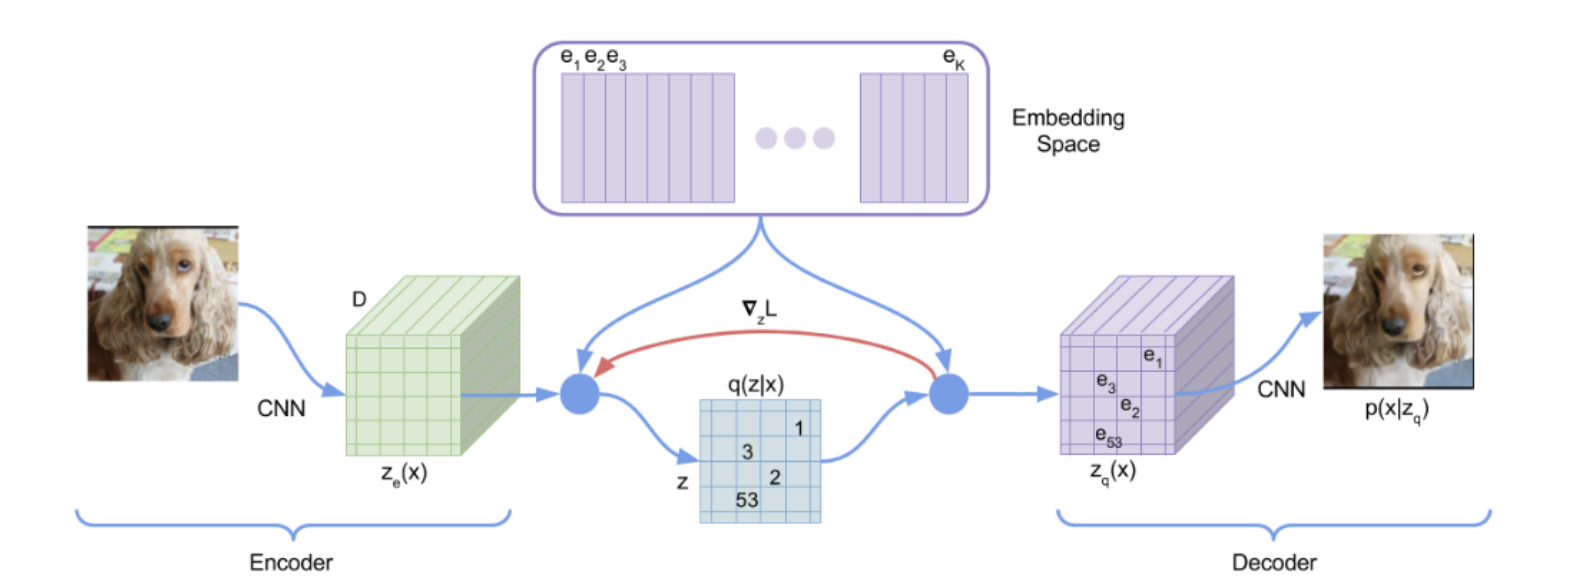
- Train a CNN encoder to generate continuous representations of images
- At training time, replace activations with the closest vector from a learned codebook
- Backpropagate as if nothing happened
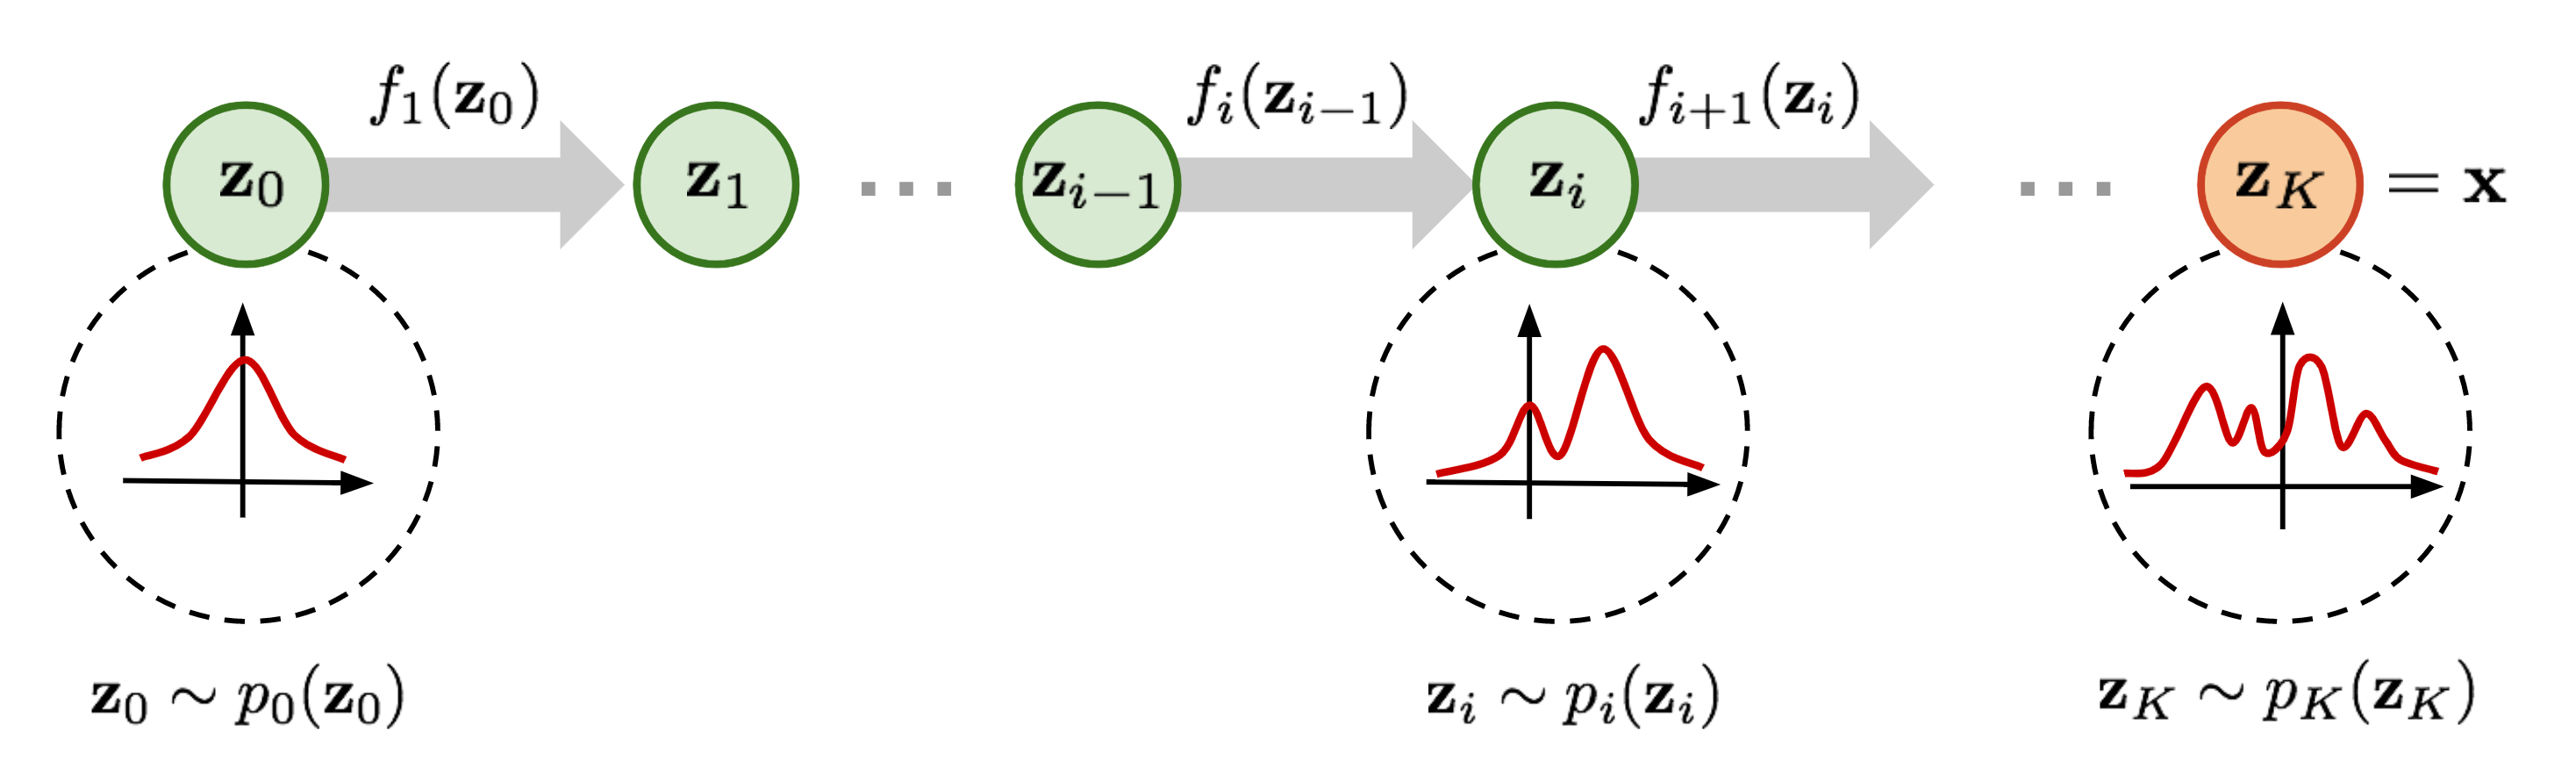
What is the main idea of a flow-based generative model?
Convert samples from a simple distribution (e.g. Gaussian noise) into samples from the data distribution by integrating along a learned velocity field.
Concretely: a neural field $f _ \theta : \mathbb R^d \to \mathbb R^d$ outputs, for every point in space, the velocity at which a sample at that location should move. Starting from $x _ 0 \sim p _ \text{init}$, take discrete Euler steps
\[z _ {t+1} = f _ \theta(z _ t) + x _ t\]until $x _ 0 \sim p _ \text{data}$
At a high level, how do diffusion models for image generation work?
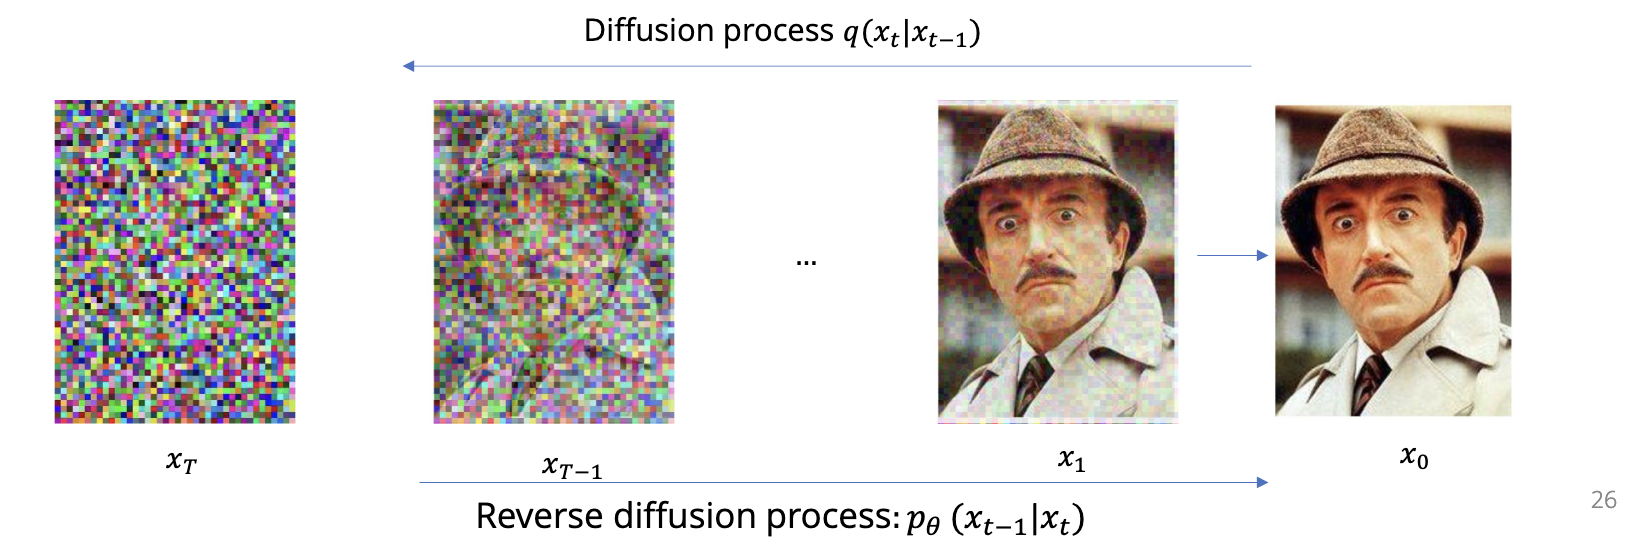
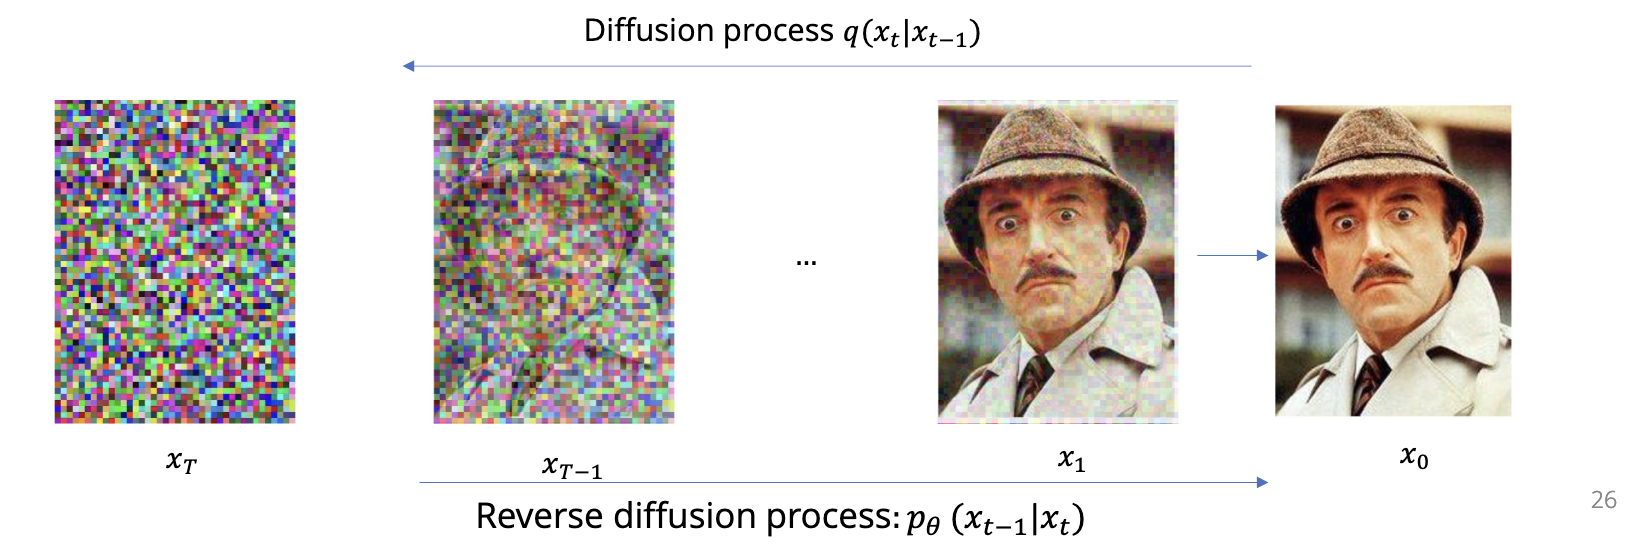
Generate an image in small stops from some noise $\epsilon$ by learning a denoising process.
@Visualise the diffusion vs reverse diffusion process in a diffusion model for image generation.
What is the aim of a diffusion model in this context?
Learn how to generate $p _ \theta (x _ {t-1} \mid x _ t)$.
What’s a typical form for $q$ in this context?
where $\beta _ t$ is a “variance schedule”, which is often fixed.
Typically, $q$ might look something like
\[q(x _ t \mid x _ {t-1}) = \mathcal N(x _ t \mid \sqrt{1 - \beta _ t} x _ {t-1}, \beta _ t I)\]
where $\beta _ t$ is a “variance schedule”, which is often fixed. Using the Markov property of the diffusion process, write the joint $q(x _ {1:T} \mid x _ 0)$ as a product.
Typically, $q$ might look something like
\[q(x _ t \mid x _ {t-1}) = \mathcal N(x _ t \mid \sqrt{1 - \beta _ t} x _ {t-1}, \beta _ t I)\]
where $\beta _ t$ is a “variance schedule”, which is often fixed. @State an expression for $x _ t$ in terms of $x _ 0$ and some noise parameter $\epsilon$.
We rewrite to give the update
\[x _ t = \sqrt{\alpha _ t} x _ {t-1} + \sqrt{1 - \alpha _ t} \epsilon _ {t-1}\]where $\alpha _ t = 1 - \beta _ t$ and $\bar \alpha _ t = \prod^t _ {i = 1} \alpha _ i$ (note: the lecture slide has $\sum$, but I think this is a typo). Applying this recursively yields
\[x _ t = \sqrt{\bar \alpha _ t} x _ 0 + \sqrt{1 - \bar \alpha _ t} \epsilon\]@State how independent Gaussians combine under (i) addition and (ii) affine scaling, and use this to find the mean and variance of $\sqrt\lambda\, X + \sqrt\omega\, Y$, where $X \sim \mathcal N(\mu _ x, \sigma _ x^2)$ and $Y \sim \mathcal N(\mu _ y, \sigma _ y^2)$ are independent and $\lambda, \omega \ge 0$.
Two closure rules:
- Independent sum: $X + Y \sim \mathcal N(\mu _ x + \mu _ y,\ \sigma _ x^2 + \sigma _ y^2)$ — means and variances add (variances, not standard deviations; the variance rule needs independence).
- Affine transform: $aX + b \sim \mathcal N(a\mu _ x + b,\ a^2\sigma _ x^2)$ — scaling by $a$ multiplies the mean by $a$ and the variance by $a^2$.
Apply both to $\sqrt\lambda\, X + \sqrt\omega\, Y$: each term is an affine scaling ($a = \sqrt\lambda$ or $\sqrt\omega$, $b = 0$), giving $\sqrt\lambda\, X \sim \mathcal N(\sqrt\lambda\,\mu _ x,\ \lambda\sigma _ x^2)$ and $\sqrt\omega\, Y \sim \mathcal N(\sqrt\omega\,\mu _ y,\ \omega\sigma _ y^2)$; then add means and variances:
\[\sqrt\lambda\, X + \sqrt\omega\, Y \sim \mathcal N\!\big(\sqrt\lambda\,\mu _ x + \sqrt\omega\,\mu _ y,\ \ \lambda\sigma _ x^2 + \omega\sigma _ y^2\big).\]Key point: a $\sqrt\lambda$ in amplitude contributes $\lambda$ (not $\sqrt\lambda$) to the variance. For standard Gaussians this is exactly $\sqrt a\,\epsilon + \sqrt b\,\epsilon' = \sqrt{a+b}\,\bar\epsilon$ with $\bar\epsilon \sim \mathcal N(\pmb 0, I)$ — the merge step that makes the diffusion noise terms telescope (∆diffusion-closed-form-derivation).
The diffusion forward process is the Markov recurrence
\[x _ t = \sqrt{\alpha _ t}\,x _ {t-1} + \sqrt{1 - \alpha _ t}\,\epsilon _ {t-1}, \qquad \alpha _ t = 1 - \beta _ t, \quad \epsilon _ {t-1} \sim \mathcal N(\pmb 0, I)\ \text{i.i.d.}\]
With $\bar\alpha _ t = \prod _ {j=1}^t \alpha _ j$, @Prove the one-shot noising identity ∆x-in-terms-of-noise
\[x _ t = \sqrt{\bar\alpha _ t}\,x _ 0 + \sqrt{1 - \bar\alpha _ t}\,\epsilon, \qquad \epsilon \sim \mathcal N(\pmb 0, I).\]
You may assume independent Gaussians add in variance (Problem Sheet III Q3.1): for independent $\tilde\epsilon, \epsilon' \sim \mathcal N(\pmb 0, I)$, $\sqrt a\,\tilde\epsilon + \sqrt b\,\epsilon' = \sqrt{a+b}\,\epsilon$ with $\epsilon \sim \mathcal N(\pmb 0, I)$.
By induction on $t$.
Base case ($t = 1$): $\bar\alpha _ 1 = \alpha _ 1$, so the recurrence $x _ 1 = \sqrt{\alpha _ 1}\,x _ 0 + \sqrt{1-\alpha _ 1}\,\epsilon _ 0$ is already the claim.
Inductive step: assume $x _ {t-1} = \sqrt{\bar\alpha _ {t-1}}\,x _ 0 + \sqrt{1-\bar\alpha _ {t-1}}\,\tilde\epsilon$ with $\tilde\epsilon \sim \mathcal N(\pmb 0, I)$ independent of $\epsilon _ {t-1}$. Then
\[\begin{aligned} x _ t &= \sqrt{\alpha _ t}\,x _ {t-1} + \sqrt{1-\alpha _ t}\,\epsilon _ {t-1} && (\star 1) \\ &= \sqrt{\alpha _ t \bar\alpha _ {t-1}}\,x _ 0 + \sqrt{\alpha _ t(1-\bar\alpha _ {t-1})}\,\tilde\epsilon + \sqrt{1-\alpha _ t}\,\epsilon _ {t-1} && (\star 2) \\ &= \sqrt{\bar\alpha _ t}\,x _ 0 + \sqrt{\alpha _ t(1-\bar\alpha _ {t-1}) + (1-\alpha _ t)}\;\epsilon && (\star 3) \\ &= \sqrt{\bar\alpha _ t}\,x _ 0 + \sqrt{1-\bar\alpha _ t}\,\epsilon. && (\star 4) \end{aligned}\]- $(\star 1)$: the forward recurrence.
- $(\star 2)$: substitute the inductive hypothesis for $x _ {t-1}$ and distribute $\sqrt{\alpha _ t}$.
- $(\star 3)$: on the signal term $\alpha _ t \bar\alpha _ {t-1} = \bar\alpha _ t$; the two independent noise terms merge into a single $\epsilon \sim \mathcal N(\pmb 0, I)$ scaled by the root of their summed variances (the Q3.1 lemma).
- $(\star 4)$: simplify, $\alpha _ t(1-\bar\alpha _ {t-1}) + (1-\alpha _ t) = 1 - \alpha _ t\bar\alpha _ {t-1} = 1 - \bar\alpha _ t$.
This closes the induction.
Why it works: the coefficients satisfy $(\sqrt{\bar\alpha _ t})^2 + (\sqrt{1-\bar\alpha _ t})^2 = 1$ at every $t$, so each merge preserves unit total variance — the noise scale is exactly what is left once the signal is attenuated by $\sqrt{\bar\alpha _ t}$.
What is the idea of latent diffusion?
Do diffusion in latent space rather than pixel space.
A trained diffusion model $f(x _ t, t)$ predicts the noise $\epsilon$ that was added at timestep $t$. Sampling generates an image from pure Gaussian noise by reversing the diffusion process step-by-step using this prediction.
@State the Denoising Diffusion Probabilistic Models (DDPM) sampling algorithm: how to generate an image $x _ 0$ from a trained noise predictor $f$.
Algorithm:
- Sample $x _ T \sim \mathcal N(0, I)$, starting from pure Gaussian noise.
- For $t = T, T-1, \ldots, 1$:
- Sample $z \sim \mathcal N(0, I)$ if $t > 1$, else $z = 0$ (so there is no noise on the last step).
- Update:
	- where $\beta _ t$ is a noise schedule, $\alpha _ t = 1 - \beta _ t$ is a signal retention factor, and $\overline \alpha _ t = \prod^t _ {i=1} \alpha _ i$ is the cumulative signal
3. Return $x _ 0$.
Explanation: Each step subtracts a scaled version of the predicted noise to denoise $x _ t$ a bit, then re-ads a smaller amount of fresh Gaussian noise $\sqrt{\beta _ t} z$. The fresh noise at each intermediate step keeps the trajectory stochastic.
A trained diffusion model $f(x _ t, t)$ predicts the noise $\epsilon$ that was added at timestep $t$. Sampling generates an image from pure Gaussian noise by reversing the diffusion process step-by-step using this prediction.
The standard diffusion training objective minimises $\|f(x _ t, t) - \epsilon\| _ 2^2$, to predict the noise added at step $t$. But the closed form ∆x-in-terms-of-noise
\[x _ t = \sqrt{\bar \alpha _ t} x _ 0 + \sqrt{1 - \bar \alpha _ t} \epsilon\]
makes $\epsilon$ and $x _ 0$ interconvertible at fixed $t$, so we could parameterise the model to predict the clean image $x _ 0$ directly.
@Describe the differences between the two diffusion training objectives, i.e. predicting the noise versus predicting $x _ 0$.
- Predict noise: minimise $\|f(x _ t, t) - \epsilon\| _ 2^2$.
- Predict clean image: minimise $\|f(x _ t, t) - x _ 0\|^2 _ 2$.
These two forms are equivalent. In practice, predicting noise tends to work slightly better, since:
- Target diversity: $\epsilon$ targets are different at every step, giving the model varied supervision throughout training.
- Memorisation risk: an $x _ 0$-prediction model has the same target $x _ 0$ for every $t$, which makes overfitting / memorisation of the specific training images more of an issue.
The Frechet Inception Distance (FID) measures how close a generated image distribution is to a reference (real) image distribution, computed via a distance between Gaussian fits to their Inception v3 features.
The Frechet distance between two probability distribution $P$ and $Q$ on $\mathbb R^d$ (also called the Wasserstein-2 distance) is:
\[d _ F(P, Q)^2 = \inf _ {\gamma \in \Gamma(P, Q)} \mathbb E _ {(x, y)\sim \gamma}\|x - y\|^2,\]
where $\Gamma(P, Q)$ is the set of couplings, i.e. joint distributions on $\mathbb R^d \times \mathbb R^d$ with marginals $P$ and $Q$. Intuitively, treat $P$ as a pile of dirt and $Q$ as a target shape, $d^2 _ F$ is the smallest total cost of reshaping $P$ into $Q$, with the cost equal to the squared distance each unit of mass is moved.
This has no closed form in general, but for two Gaussians it does. Given this, @state the FID formula given a feature extractor $f$ applied to real images $\mathcal I _ r$ and generated samples $\mathcal I _ g$.
Setup:
- Feature extractor $f : \text{Image} \to \mathbb R^d$, typically Inception v3.
- Compute features $\{f(I) \mid I \in \mathcal I _ r\}$ and $\{f(I) : I \in \mathcal I _ g\}$.
- Fit a Gaussian to each set: $\mathcal N(\mu _ r, \Sigma _ r)$ to real features, $\mathcal N(\mu _ g, \Sigma _ g)$ to generated features.
The FID is then
\[d _ F = \| \mu _ r - \mu _ g\|^2 _ 2 + \text{tr}(\Sigma _ r + \Sigma _ g - 2(\Sigma _ r \Sigma _ g)^{1/2}).\]The first term is the cost of moving between the mean of the real distribution and of the generated distribution. The second term is the cost of updating the covariance $\Sigma _ r$ to $\Sigma _ g$.
The DDPM sampling algorithm (∆ddpm-sampling-step) requires $T$ forward passes of the denoising network per image, typically $T \approx 1000$.
Running each pass on a $3 \times H \times W$ pixel tensor is expensive. Latent diffusion runs the diffusion on a compressed representation instead.
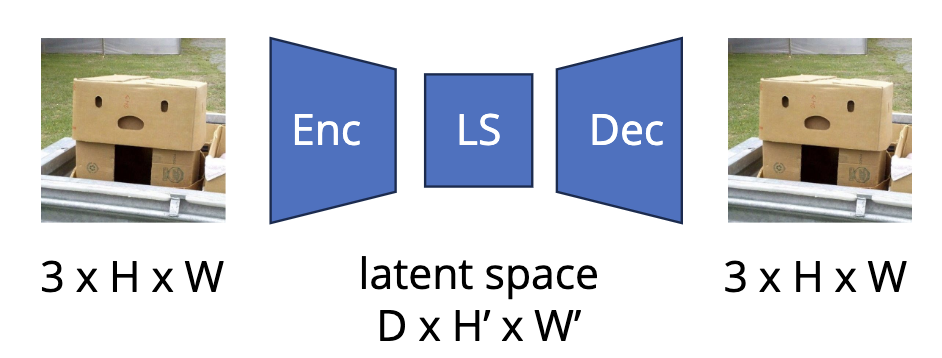
@Describe how latent diffusion compresses the image and what the diffusion process operates on.
Setup: train a VQ-VAE encoder-decoder pair $(\mathcal E, \mathcal D)$ on the image dataset.
- $\mathcal E : \text{image} \to \text{latent}$, mapping $3 \times H \times W$ to $D \times H' \times W'$.
- $\mathcal D : \text{latent} \to \text{image}$, mapping $D \times H' \times W'$ back to $3 \times H \times W$.
- $D \times H' \times W'$ are chosen so that the latent representation is smaller.
Diffusion: Diffusion runs on $z = \mathcal E(x)$, not on $x$:
- Forward process: $q(z _ t \mid z _ {t-1}) = \mathcal N(z _ t \mid \sqrt{1-\beta _ t} z _ {t-1}, \beta _ t I)$
- Reverse process: a denoising U-Net $\epsilon _ \theta (z _ t, t, c)$ predicts the noise added after a step $t$.
- After sampling completes, $z _ 0$ is decoded back to a pixel-space image via $\tilde x = \mathcal D(z _ 0)$.
Stable Diffusion is a text-conditional image generator that runs the diffusion process on a compressed latent representation of the image rather than raw pixels, and conditions every denoising step on the prompt via cross-attention.
@List the four key architectural ideas behind Stable Diffusion 1.
- Conditional diffusion model: Every denoising step takes a conditioning input $c$, so that the model can generate images guided by different prompts.
- Latent diffusion: The diffusion process runs on a low-dimensional latent $z = \mathcal E(x)$ from a VQ-VAE, not on raw pixels (∆stable-diffusion-latent-diffusion).
- U-Net architecture: The denoising network $\epsilon _ \theta (z _ t, t, c)$ is a CNN encoder-decoder with skip connections, taking noisy latent + timestep + conditioning as inputs.
- Cross-attention layers: inserted between U-Net conv blocks, attending to the encoded conditioning $\tau _ \theta(c)$ (∆stable-diffusion-cross-attention). The U-Net also receives the timestep via a Fourier-basis embedding (∆stable-diffusion-time-dependency).
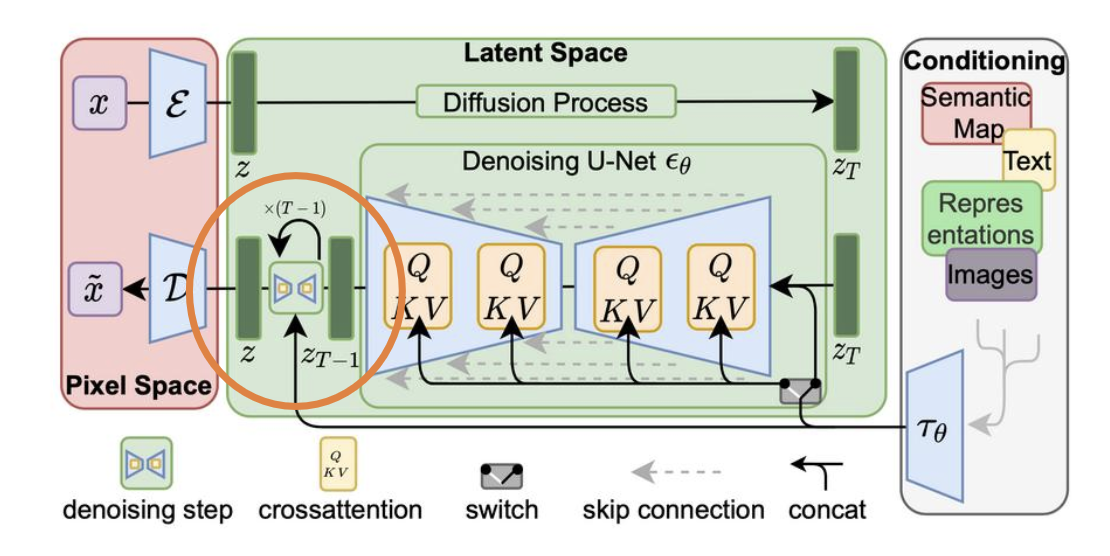
In Stable Diffusion (∆stable-diffusion-overview), the diffusion process is conditioned on a prompt $c$, which may be text, a semantic map, an image, etc. The conditioning is injected into the U-Net via cross-attention layers using standard scaled dot-product attention (∆scaled-dot-product-attention).
@Describe how Stable Diffusion conditions its denoising U-Net on an input prompt.
Conditioning encoder $\tau _ \theta$: a separate network that maps the raw prompt to a sequence of tokens:
- Text prompt: a text encoder
- Semantic map / layout: the corresponding encoder
- Image: an image encoder
The output is $\tau _ \theta(c) \in \mathbb R^{M \times d}$, an $M$-token representation in the U-Net’s hidden dimension.
Cross-attention layers: inserted between the U-Net’s conv blocks at each spatial resolution. As in any attention layer, $Q$, $K$, $V$ are learned linear projections of their sources (per head, matrices $W _ Q, W _ K, W _ V$):
- Queries $Q$: projected from the U-Net’s spatial features at that resolution, one query per spatial location.
- Keys and values $K$, $V$: projected from $\tau _ \theta(c)$, and only from $\tau _ \theta(c)$. The U-Net features go into $Q$ alone, never into $K$ or $V$.
- Output: $\text{softmax}(QK^\top / \sqrt d) V$, mixed back into the U-Net features via the residual stream.
Where does conditioning enter the U-Net? The prompt $c$ enters only via these cross-attention layers. The timestep $t$ is a separate conditioning signal injected differently: a Fourier embedding passed through an MLP and added per-channel into each ResBlock (∆stable-diffusion-time-dependency). Spatially-aligned conditioning (e.g. an inpainting mask) can additionally be concatenated channel-wise with the noisy latent at the U-Net input.
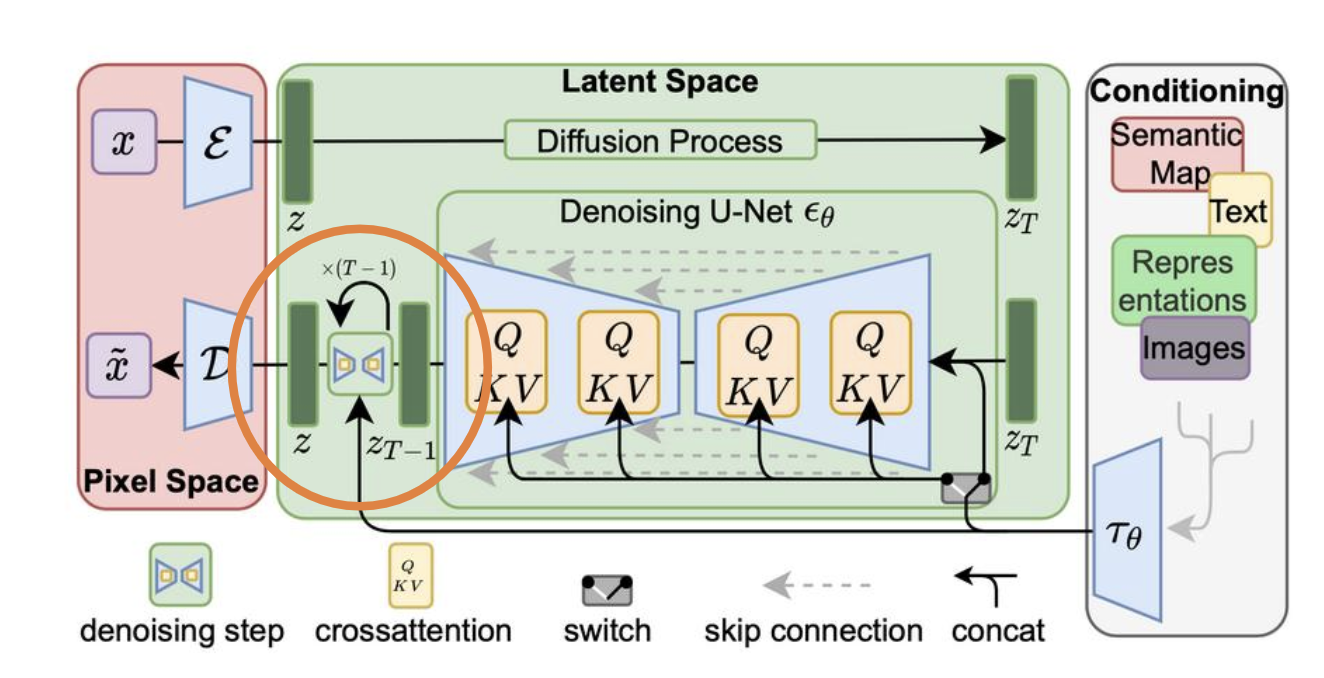
In Stable Diffusion (∆stable-diffusion-overview), the denoising score function $f(z _ t, t)$ depends on the timestep $t$, since different $t$ correspond to different noise levels, so the network needs to know which step its denoising.
Stable Diffusion adds time dependency to the U-Net via a Fourier basis embedding plus an MLP.
@Describe how Stable Diffusion injects the timestep $t$ into the denoising U-Net.
Fourier-basis time embedding: Convert the scalar $t$ into a vector
\[\text{emb}(t) = [\sin \omega _ 1 t, \cos \omega _ 1 t, \sin \omega _ 2 t, \ldots, \cos \omega _ K t]\]where $\omega _ 1, \ldots, \omega _ K$ are a fixed set of frequencies.
MLP: Pass the Fourier embedding through an MLP to produce $f(t) \in \mathbb R^C$, one value per channel.
Add to U-Net features: at each layer of the U-Net, broadcast $f(t)$ across the spatial dimensions and add per-channel:
\[\text{feat} _ {c,h,w} \leftarrow \text{feat} _ {c, h, w} + f(t) _ c\]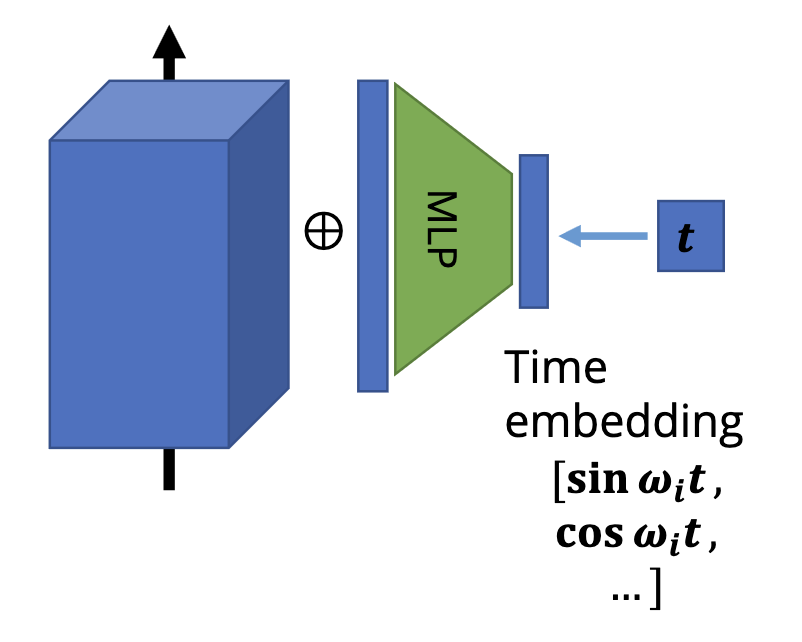
Bite-sized
GANs (Generative Adversarial Networks) appear in the lecture’s generative-model taxonomy as an implicit, direct-sampling model. They were introduced by Goodfellow et al., NeurIPS 2014 and consist of a generator $G$ that maps latent noise $z$ to samples, trained adversarially against a discriminator $D$ that tries to tell real from generated.
@Describe the difference between a standard VAE and a VQ-VAE, focusing on the form of the latent.
- VAE (Kingma et al., ICLR 2014): the encoder $E$ outputs $(\mu, \sigma)$ for a continuous Gaussian posterior $q(z \mid x) = \mathcal N(\mu, \sigma^2)$. A sample $z \sim q(z \mid x)$ is decoded by $D$. Trained on the ELBO: reconstruction loss minus KL divergence to a prior.
- VQ-VAE (van den Oord et al., 2017): the encoder produces a continuous feature map $z _ e(x)$, but the bottleneck quantises each activation vector to its nearest entry in a learned codebook $\{e _ 1, \ldots, e _ K\}$. The decoder operates on the quantised $z _ q(x)$. Gradients flow through the quantiser via the straight-through estimator.
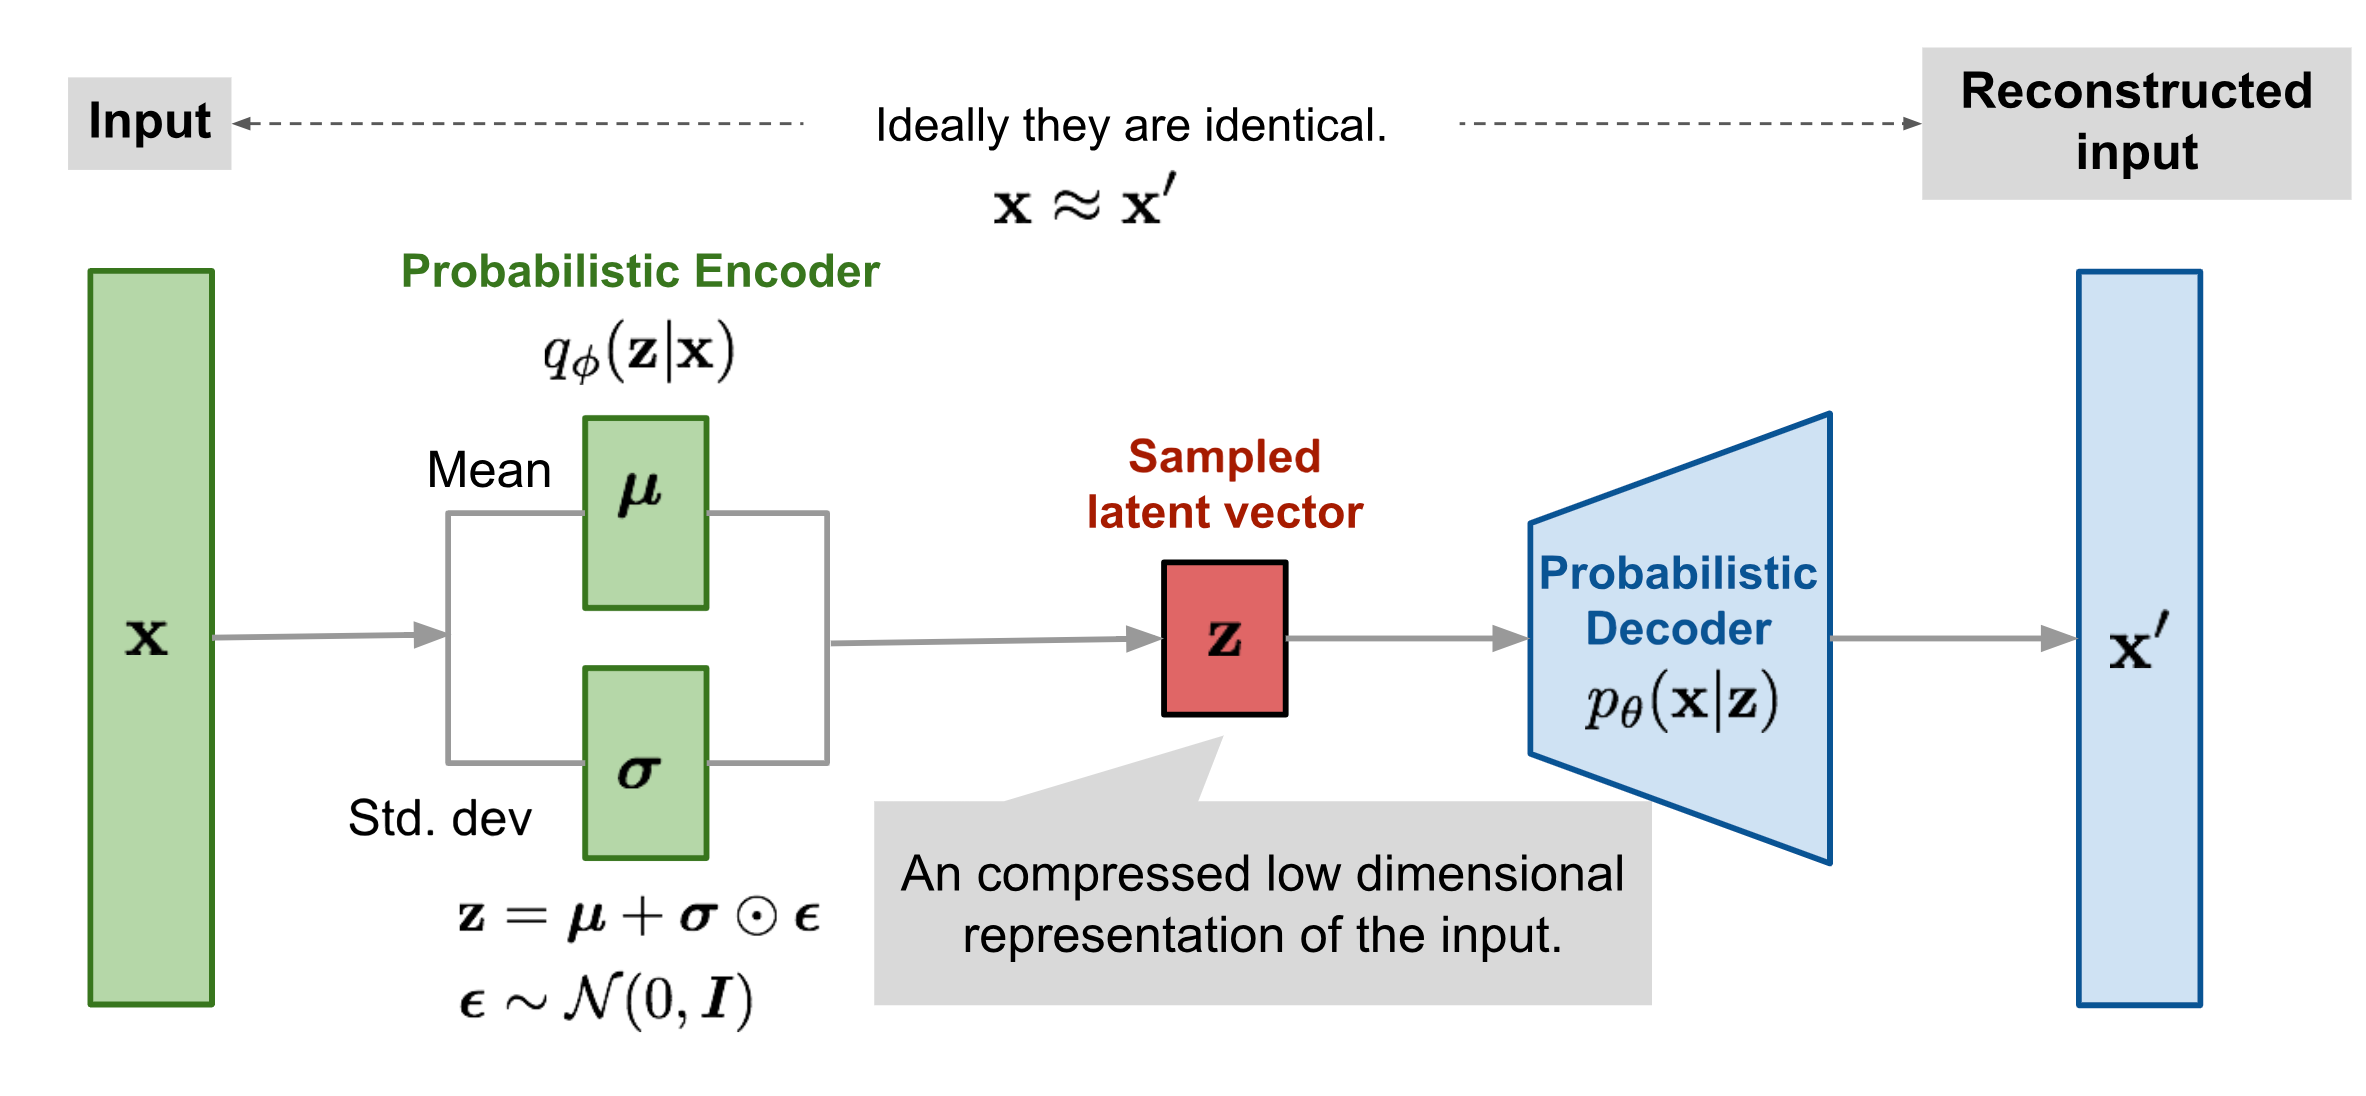
VQ-VAE’s discrete latent is what makes it pair naturally with autoregressive models on tokens (DALL-E) and with diffusion in latent space (Stable Diffusion’s VAE-like compressor).
The SiLU (Sigmoid Linear Unit) activation, defined as $\mathrm{silu}(x) = x \cdot \sigma(x)$, is used inside the Stable Diffusion U-Net. Its gradient is non-zero everywhere (unlike ReLU), giving smoother optimisation at the cost of slightly higher compute.
A typical DDPM uses $T \approx <span class="cloze" tabindex="0">1000</span>$ diffusion steps. Inference therefore requires that many forward passes through the denoising network — which is the practical bottleneck and the motivation for latent diffusion (run the $T$ steps on a smaller spatial representation).
@Describe the Frechet distance intuition that underlies FID, in the dog-and-owner metaphor.
Consider two paths in space — one walked by a dog, one walked by its owner, each parameterised by time $t \in [0, 1]$ and constrained to move only forward. The Frechet distance is the shortest possible leash that allows both to traverse their respective paths, where the leash length at time $t$ is the distance between the two positions.
Equivalently in measure-theoretic terms (Wasserstein-2 / earth-mover’s): treat each distribution as a pile of dirt and consider the minimum total transport cost to reshape one into the other under squared distance.
FID applies this idea in Inception-v3 feature space: it fits Gaussians $\mathcal N(\mu _ r, \Sigma _ r)$ and $\mathcal N(\mu _ g, \Sigma _ g)$ to real and generated features, and computes the closed-form Wasserstein-2 distance between those Gaussians.
FID computes its distance in the feature space of Inception v3 (not in pixel space) — fitting a Gaussian to each set of feature vectors and taking the Wasserstein-2 / Frechet distance between them.
In diffusion models, the forward (noising) process $q(x _ t \mid x _ {t-1})$ is fixed (a hand-chosen Gaussian schedule with no learnable parameters), while the reverse (denoising) process $p _ \theta(x _ {t-1} \mid x _ t)$ is the only thing that gets learned. This asymmetry is what makes diffusion training so simple: just generate noisy samples via the fixed forward process, then teach the network to denoise.
Large-scale diffusion models like Stable Diffusion are trained on text-image pairs at internet scale — the LAION dataset has > 1 billion image-text pairs.
DALL-E (Ramesh et al., ICML 2021) was trained on 400M image-text pairs and generates images autoregressively in token space using a VQ-VAE codebook, not directly in pixel space. The autoregressive transformer predicts one image-token at a time conditional on the text prompt + tokens generated so far.
@Justify why evaluating implicit generative models is much harder than evaluating explicit generative models.
- Explicit models (autoregressive, VAEs) directly compute $\log p _ \text{model}(\pmb x)$ for any input $\pmb x$. You can take a held-out test set and average $\log p$ across it: the model with higher average held-out log-likelihood wins. Single number, comparable across models.
- Implicit models (GANs, diffusion, GSNs) only let you sample from $p _ \text{model}$. We cannot evaluate the density at a particular point, so there is no test-set log-likelihood. Instead we resort to indirect proxies:
- Human evaluation: ask people which images they prefer. Subjective, vague (realism? prompt fidelity? aesthetics?), expensive, hard to scale.
- FID: compute a Wasserstein-2 distance between Gaussian fits to Inception features of real vs generated images. Aligns somewhat with human judgement but is gameable and not a true likelihood.
- Inception Score, Precision/Recall for generative models, CMMD, etc.: each has known failure modes.
So while explicit models have a single principled comparison metric (held-out NLL), the field has no clean winner for evaluating implicit models — FID is the de-facto standard despite its weaknesses.
In latent diffusion (Stable Diffusion), the typical compression factor of the VAE-style encoder is roughly $\times 8$ in each spatial dimension (e.g. a $512 \times 512$ image becomes a $4 \times 64 \times 64$ latent), giving $\sim 64\times$ less compute per denoising step compared to pixel-space diffusion.
The closed-form expression for $\bar\alpha _ t$ in the diffusion noise schedule is $\bar\alpha _ t = <span class="cloze" tabindex="0">\prod _ {i=1}^{t} \alpha _ i</span>$ (a product, not a sum — a common transcription error). It enters the closed-form sampling identity $x _ t = \sqrt{\bar\alpha _ t}\, x _ 0 + \sqrt{1 - \bar\alpha _ t}\,\varepsilon$ which lets us draw $x _ t$ from $x _ 0$ in a single step.
Visualising the masks
A masked convolution keeps an autoregressive CNN honest: the prediction for a pixel must depend only on earlier pixels (∆autoregressive-mask-need). The two masks (∆autoregressive-cnn-masks) differ only at the centre tap, and the visualisation below shows why that has to be. Trace the receptive field of the starred pixel: with Mask B in the first layer the pixel ends up depending on its own value (a leak, shown red), so the first layer must use Mask A. After that first layer the centre feature holds only earlier pixels, so later layers keep the centre (Mask B) to widen the context.