Computer Vision MT25, Image restoration
Flashcards
Summarise the difference between image enhancement and image restoration.
In image restoration, you model a “true” image which has been degraded.
@State (and @visualise) the general setup of image restoration.
We have:
- A true image $f$
- A degraded image $g$
- Some noise $n$
- A “impulse response” or “point spread” function $d$
- The degraded image comes from a convolution with $d$ and added noise $n$
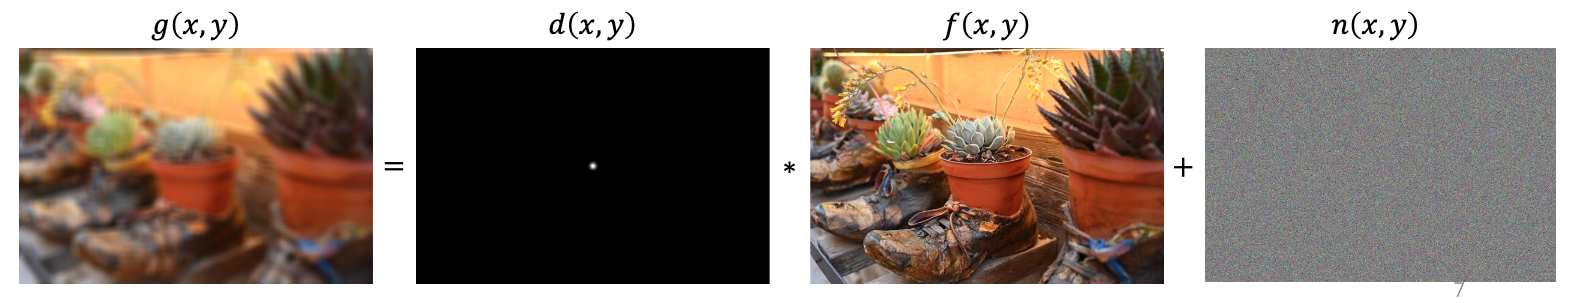
Suppose we have:
- A true image $f$
- A degraded image $g$
- A “impulse response” or “point spread” function $d$
- The degraded image comes from a convolution with $d$ and added noise $n$
\[g(x, y) = \iint d(x - u, y - v) f(u, v) \text du \text dv \quad + \quad n(x, y)\]
How could you naïvely recover an estimate $\hat f$ of the true image?
Suppose we have:
- A true image $f$
- A degraded image $g$
- A “impulse response” or “point spread” function $d$
- The degraded image comes from a convolution with $d$ and added noise $n$
\[g(x, y) = \iint d(x - u, y - v) f(u, v) \text du \text dv\]
One way of naïvely recovering an estimate $\hat f$ of the true image is to compute:
\[\hat f = \mathcal F^{-1} \left( \frac{\mathcal F\{g\}}{\mathcal F\{d\}} \right)\]
What’s the problem with this?
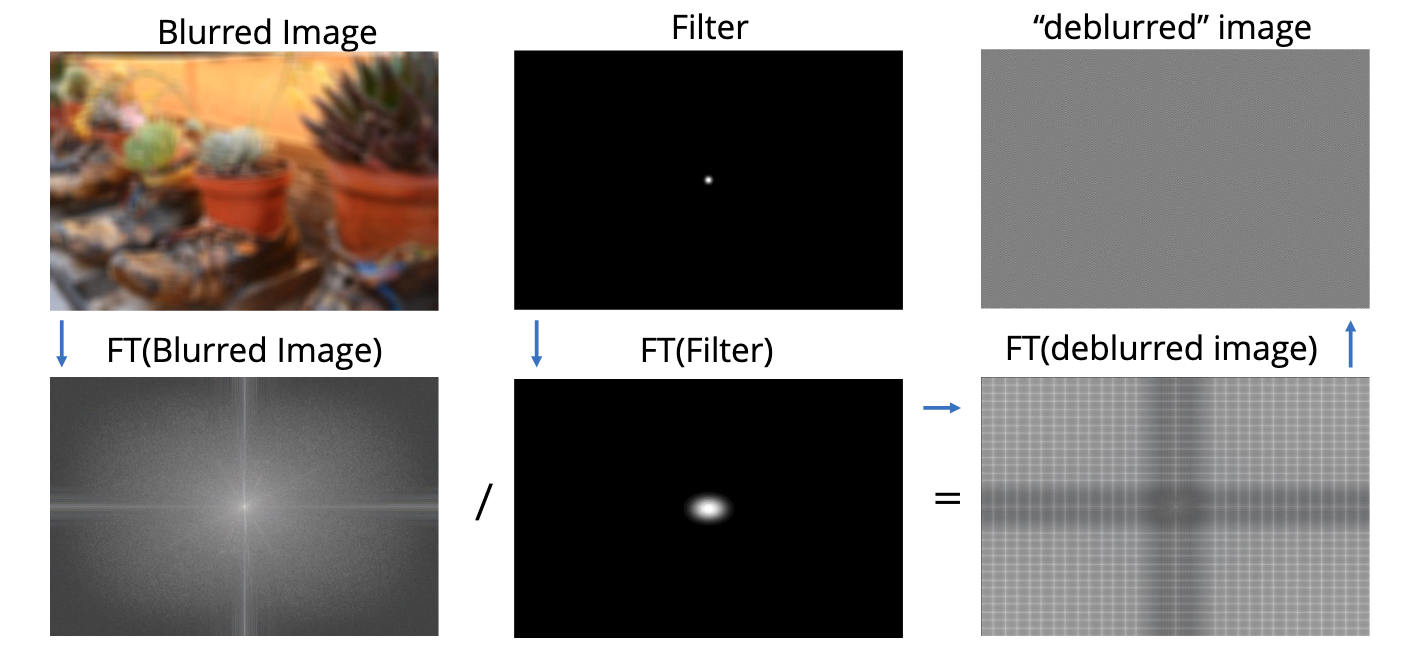
$d$ is often very close to zero in high-frequency regions, so you end up amplifying the noise present in the original image.
Wiener filter
Suppose we have:
- A true image $f$
- A degraded image $g$
- A “impulse response” or “point spread” function $d$
- The degraded image comes from a convolution with $d$ and added noise $n$
\[g(x, y) = \iint d(x - u, y - v) f(u, v) \text du \text dv\]
One way of naïvely recovering an estimate $\hat f$ of the true image is to compute:
\[\hat f = \mathcal F^{-1} \left( \frac{\mathcal F\{g\}}{\mathcal F\{d\}} \right)\]
The problem with this is that $d$ often very close to zero in high-frequency regions, so you end up amplifying the noise present in the original image. @Define the Wiener filter and @state the additional assumption that it is derived from.
We add the constraint that we wish to minimise $\mathbb E( \vert f - \hat f \vert ^2)$. The Wiener filter works in the frequency domain as
\[\hat F(u, v) = W(u, v) G(u, v)\]where
\[W(u, v) = \frac{D^\ast(u, v)}{ \vert D(u, v) \vert ^2 S(u, v) + K(u, v)}\]and:
- $D^\ast (u, v)$ is the complex conjugate of $D(u, v)$
- $S(u, v) = \mathbb E( \vert F(u, v) \vert ^2)$ is the mean power spectral density of the original signal, typically $1$
- $K(u, v) = \mathbb E( \vert N(u, v) \vert ^2)$ is the mean power spectral density of the noise, typically a small constant
The Wiener filter works in the frequency domain as
\[\hat F(u, v) = W(u, v) G(u, v)\]
where
\[W(u, v) = \frac{D^\ast(u, v)}{ \vert D(u, v) \vert ^2 S(u, v) + K(u, v)}\]
and:
- $S(u, v) = \mathbb E( \vert F(u, v) \vert ^2)$ is the mean power spectral density of the original signal, typically $1$
- $K(u, v) = \mathbb E( \vert N(u, v) \vert ^2)$ is the mean power spectral density of the noise, typically a small constant
Can you give an alternative formulation that intuitively explains how the Wiener filter prevents amplifying noise?
where $\text{SNR}$ is the signal to noise ratio.
Hence we invert the filter but scale up inversely with the expected noise.
Suppose:
- We have the linear observation model $g = d \ast f + n$ in the spatial domain, equivalently $G = DF + N$ in the frequency domain.
- $F$ and $N$ are zero-mean and uncorrelated, with known power spectra $S = \mathbb E( \vert F \vert ^2)$ and $K = \mathbb E( \vert N \vert ^2)$. The signal-to-noise ratio is $\text{SNR} = S/K$.
- We restrict to linear estimators $\hat F = W G$.
Derive the Wiener filter from the MMSE objective $\min _ W \mathbb E( \vert F - \hat F \vert ^2)$.
Substituting $G = DF + N$:
\[\mathbb E( \vert F - W(DF + N) \vert ^2) = \mathbb E( \vert (1 - WD)F - WN \vert ^2).\]Expand $ \vert z \vert ^2 = z z^\ast$ inside the expectation. Since $W$ and $D$ are deterministic, $((1-WD)F - WN)^\ast = (1-WD)^\ast F^\ast - W^\ast N^\ast$, and by linearity of expectation:
\[\mathbb E( \vert (1-WD)F - WN \vert ^2) = \vert 1-WD \vert ^2\, \mathbb E( \vert F \vert ^2) - (1-WD)W^\ast\, \mathbb E(F N^\ast) - (1-WD)^\ast W\, \mathbb E(F^\ast N) + \vert W \vert ^2\, \mathbb E( \vert N \vert ^2).\]The two middle (cross) terms vanish under the zero-mean uncorrelated assumption: $\mathbb E(F N^\ast) = \mathbb E(F)\, \mathbb E(N^\ast) = 0$, and similarly $\mathbb E(F^\ast N) = 0$. The remaining terms are exactly $S$ and $K$, leaving:
\[J(W) := \mathbb E( \vert (1-WD)F - WN \vert ^2) = \vert 1 - WD \vert ^2 S + \vert W \vert ^2 K.\]Optimising over $W$ via Wirtinger calculus (∆wirtinger-derivative): $J$ is real-valued in the complex variable $W$, so it is not holomorphic and the ordinary complex derivative $\partial / \partial W$ is undefined. The workaround is to treat $W$ and $W^\ast$ as formally independent variables. A critical point of a real-valued $J$ is then characterised by $\partial J / \partial W^\ast = 0$, computed by differentiating with $W$ held constant.
Writing $J(W) = (1 - WD)(1 - WD)^\ast S + W W^\ast K$ and differentiating with respect to $W^\ast$ (the factor $(1-WD)$ has no $W^\ast$ dependence so stays, and $(1-WD)^\ast$ differentiates to $-D^\ast$):
\[\frac{\partial J}{\partial W^\ast} = -(1 - WD) D^\ast S + W K = 0.\]Solving for $W$:
\[W = \frac{D^\ast S}{ \vert D \vert ^2 S + K} = \frac{D^\ast}{ \vert D \vert ^2 + K/S}.\]Inverse-filter-with-shrinkage form: multiply numerator and denominator by $1/ \vert D \vert ^2$ (assuming $D \ne 0$), use $D^\ast / \vert D \vert ^2 = 1/D$, and substitute $K/S = 1/\text{SNR}$:
\[W = \frac{1}{D} \cdot \frac{1}{1 + \dfrac{1}{ \vert D \vert ^2 \, \text{SNR}}}.\]This matches the form quoted in ∆wiener-filter-snr-form. In high-SNR regions the bracketed factor $\to 1$ and we recover the inverse filter $W = 1/D$. In low-SNR regions the shrinkage factor pulls $W$ toward zero, suppressing the noise that pure inversion would amplify.
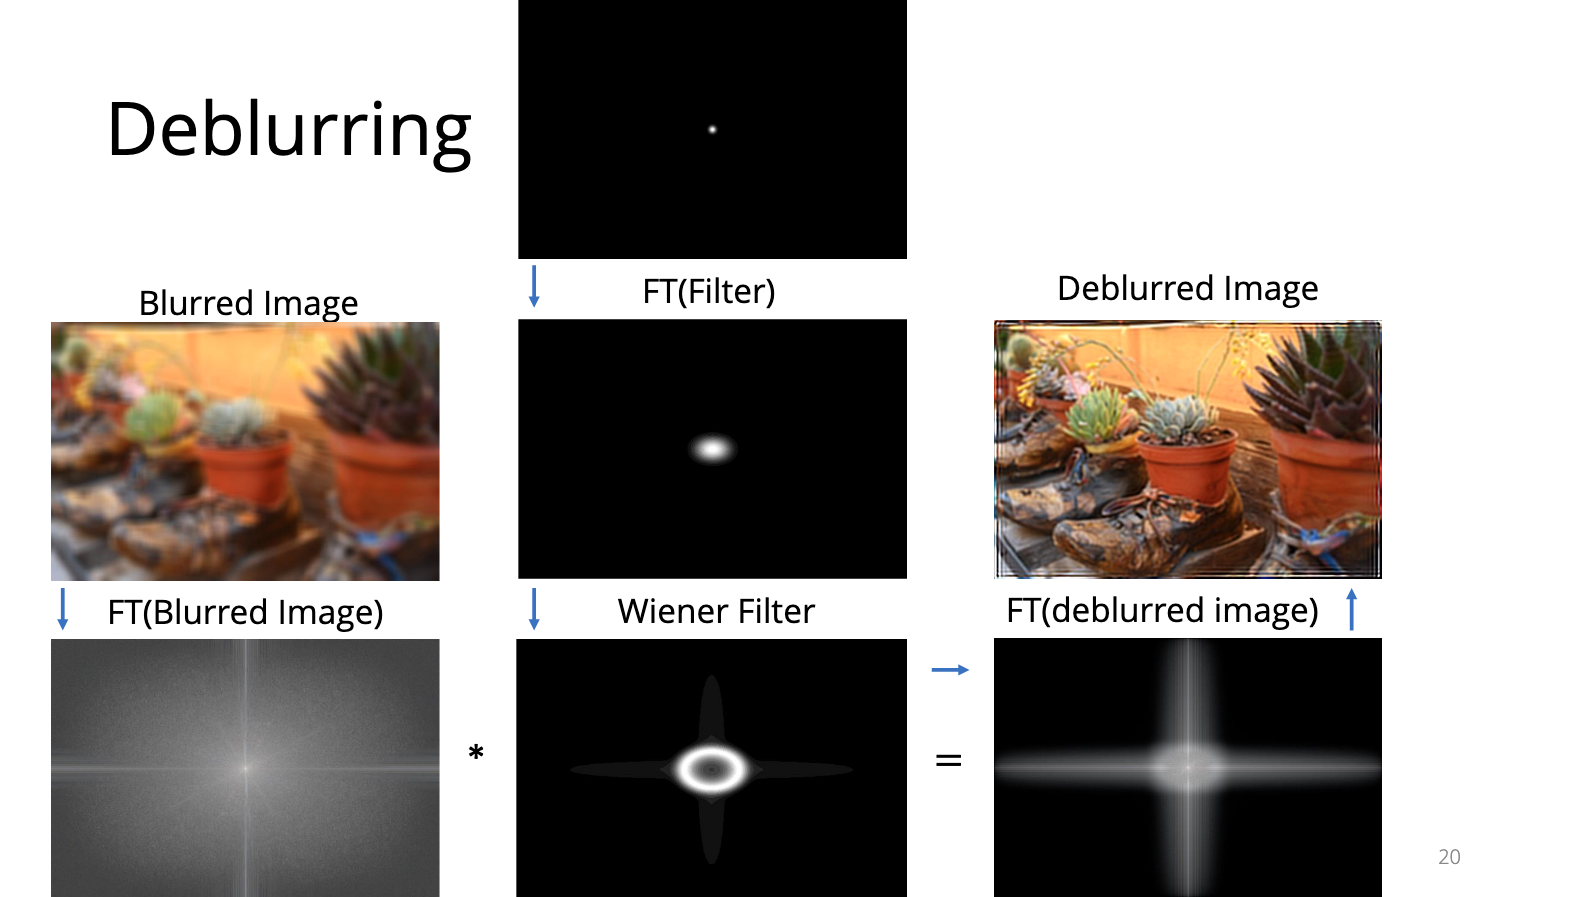
@Visualise how the Wiener filter can be used to deblur an image.
Motion blur
What’s one way of modelling motion blur?
Convolution with a line segment filter.
@Visualise how you can model convolution with a line segment filter can be used to model motion blur.
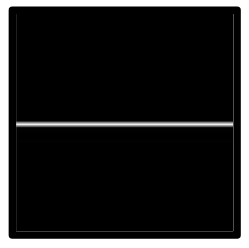
Intuitively, the convolution is averaging the pixels along a particular line.
Give an @algorithm for removing motion blur.
- Rotate the image so that the motion blur is horizontal.
- Estimate the length of the blur.
- Construct a line segment filter.
- Compute and apply Wiener filter.
Generative models of degradation
@State the generative model of image degradation.
We have:
- A true image $f$
- A degraded image $g$
- An $N \times N$ matrix $A$
- Some noise $n \in \mathbb R^{N}$
and model $g$ as
\[g = Af + n\](this is “generative”, as we are modelling $g$ as being constructed from $f$ by some generative process)
In the generative model of image degradation, we have:
- A true image $f$
- A degraded image $g$
- An $N \times N$ matrix $A$
- Some noise $n \in \mathbb R^{N}$
and model $g$ as
\[g = Af + n\]
Given $g$ and $A$, how is an estimate $\hat f$ for the original image found?
where $p(f)$ is a regulariser.
In the generative model of image degradation, we have:
- A true image $f$
- A degraded image $g$
- An $N \times N$ matrix $A$
- Some noise $n \in \mathbb R^{N}$
and model $g$ as
\[g = Af + n\]
Given $g$ and $A$, we find an estimate $\hat f$ for the original image via
\[\hat f = \text{argmin} _ f[(g - Af)^2 + \lambda p (f)]\]
where $p(f)$ is a regulariser. Give an @example choice for the regulariser, and explain why this is a good choice.
where $\Delta _ x$ and $\Delta _ y$ are the horizontal and vertical pixel differences (recall here that $f$ is a “vectorised” version of the image, i.e. a column vector of pixels).
This is a smoothness prior. The estimate is penalised for having drastic changes between adjacent pixels.
In the generative model of image degradation, we have:
- A true image $f$
- A degraded image $g$
- An $N \times N$ matrix $A$
- Some noise $n \in \mathbb R^{N}$
and model $g$ as
\[g = Af + n\]
Given $g$ and $A$, we find an estimate $\hat f$ for the original image via
\[\hat f = \text{argmin} _ f[(g - Af)^2 + \lambda p (f)]\]
where $p(f)$ is a regulariser. @State two ways that you could estimate $A$.
- Super resolution: Given multiple images of the same scene, you can estimate $A$.
- Blind deblurring: Instead consider the optimisation problem $\hat f, \hat h = \text{argmin} _ {f, h} [(g - A(h) f)^2 + \lambda _ f p _ f(f) + \lambda _ h p _ h(h)]$.
Bite-sized
@State the four canonical image degradation types covered in Lecture 4.
- Optical blur: image is uniformly out of focus. Modelled by a (roughly Gaussian) PSF.
- Motion blur: smear along the direction of camera or object motion. Modelled by a line-segment PSF.
- Spatial quantisation: pixelation / undersampling. Reduces effective resolution.
- Additive noise: random per-pixel perturbations, often Gaussian or salt-and-pepper.
All four can be modelled in the linear-degradation framework $g = d \ast f + n$ or the more general $g = Af + n$.
The terminology in image restoration: $d(x, y)$ is called the point spread function (PSF) or impulse response of the imaging system — the response of the imaging system to a single point source.
@Justify why naive Fourier-domain deconvolution $\hat F = G / D$ catastrophically amplifies noise.
In the frequency domain, the observed image is $G(u, v) = D(u, v) F(u, v) + N(u, v)$. Dividing through:
\[\hat F(u, v) = \frac{G(u, v)}{D(u, v)} = F(u, v) + \frac{N(u, v)}{D(u, v)}.\]For most blur kernels (Gaussian, box, motion-line), $D(u, v)$ is small at high frequencies (a low-pass filter). Even small noise $N$ gets divided by tiny $D$, producing huge high-frequency components — the reconstruction is dominated by noise rather than recovering $F$.
The visible failure mode: the “deblurred” image is essentially pure high-frequency noise, often showing a regular grid pattern from the structure of $1/D$.
The Wiener filter has the inverse-filter-with-shrinkage form
\[W(u, v) = <span class="cloze" tabindex="0">\frac{1}{D(u, v)} \cdot \frac{1}{1 + \frac{1}{ \vert D(u, v) \vert ^2 \mathrm{SNR}(f)</span> }}\]where $\mathrm{SNR}(f) = S/K$ is the signal-to-noise ratio. In high-SNR regions the shrinkage factor approaches 1 and we recover the inverse filter; in low-SNR regions the shrinkage approaches 0 and the noise is suppressed.
@Describe two practical limitations of the Wiener filter as a deblurring tool.
- Boundary artefacts: the DFT implicitly assumes the image is periodically tiled, so finite-image boundaries introduce artificial discontinuities. The Wiener-deblurred output shows dark borders and ringing at the edges of the image.
- Unknown PSF: in practice the degradation filter $d$ is not known a priori. We either have to estimate it (e.g. from EXIF data, calibration patterns, or blind deblurring — joint optimisation over $f$ and $h$), or hand-guess key parameters (motion-blur angle, length, noise level).
Practical workarounds in the lecture: Photoshop exposes a “strength” slider so the user tunes parameters interactively; Orieux, Giovannelli & Rodet (2010) describe a Bayesian optimisation approach to setting Wiener-Hunt parameters automatically.
The motion-blur removal recipe is: (1) rotate the image so the blur direction is horizontal, (2) estimate the length of the blur, (3) construct a horizontal line-segment PSF of that length, (4) compute and apply the Wiener filter, (5) rotate back.
@Justify why super-resolution from multiple registered images works, in terms of the Nyquist-Shannon sampling theorem.
A single low-resolution image is a sampled version of the underlying continuous scene at the sensor’s pixel grid, with possibly aliased high-frequency content.
When we register multiple images of the same scene taken from slightly different sub-pixel-offset viewpoints, each image samples the underlying continuous scene at a different set of points. Pooled together, these registered samples form a denser effective sampling grid — equivalent to having sampled the scene at a higher rate than any individual image.
By the Nyquist-Shannon theorem, a sufficiently dense sampling of the scene lets us reconstruct higher-frequency content that any individual image could not resolve. The matrix $A$ encodes the bilinear-interpolation weights of how each high-res pixel contributes to each low-res image; solving the inverse problem $\hat f = \arg\min _ f \|g - Af\|^2 + \lambda p(f)$ recovers the super-resolved image.
The lecture’s worked example: 25 JPEG frames of a rock from the Mars Lander (rotating camera so the same scene is photographed many times) — $2\times$ super-resolution recovers detail invisible in any single frame and also removes JPEG compression artefacts.
The total-variation (TV) regulariser
\[p(f) = \sum _ {x, y} \vert \Delta _ x f(x, y) \vert + \vert \Delta _ y f(x, y) \vert \]sums the $L _ 1$ norm of pixel-wise gradients. It is preferred over a Tikhonov / $L _ 2$ smoothness term because the $L _ 1$ form preserves sharp edges (it penalises gradient magnitude without quadratically over-penalising the rare big jumps that correspond to genuine edges), whereas $L _ 2$ would force all gradients to be small and blur edges away.
For blind deblurring, where the PSF $h$ is unknown, the inverse problem becomes a joint optimisation over both the image $f$ and the filter $h$:
\[\hat f, \hat h = \arg\min _ {f, h} \ \vert g - A(h) f\ \vert ^2 + \lambda _ f p _ f(f) + \lambda _ h p _ h(h)\]This is highly underconstrained, so success depends critically on good priors $p _ f$ and $p _ h$, or on having multiple observations.
@Justify why we should expect a Wiener filter to be more useful in practice than naive deconvolution, in terms of the spectral content of natural images.
For natural images, the power spectrum $S(u, v) = \mathbb E[ \vert F(u, v) \vert ^2]$ roughly follows a $1/f^2$ fall-off — most of the energy lives at low frequencies. Conversely, the noise spectrum $K(u, v)$ tends to be flat (white noise). So the signal-to-noise ratio $S/K$ is high at low frequencies and low at high frequencies.
The Wiener filter is built around this asymmetry: in high-SNR regions (low frequencies, where there’s real signal to recover) it acts like the inverse filter; in low-SNR regions (high frequencies, where the signal is weak and noise dominates) the shrinkage factor pulls toward zero, preventing noise amplification.
So a Wiener filter automatically de-emphasises the high-frequency regions where naive deconvolution would catastrophically amplify noise, while still recovering the low-frequency content that naive deconvolution would also fix.