Computer Vision MT25, Learning curves
Flashcards
How would you diagnose the problem with the red curve?
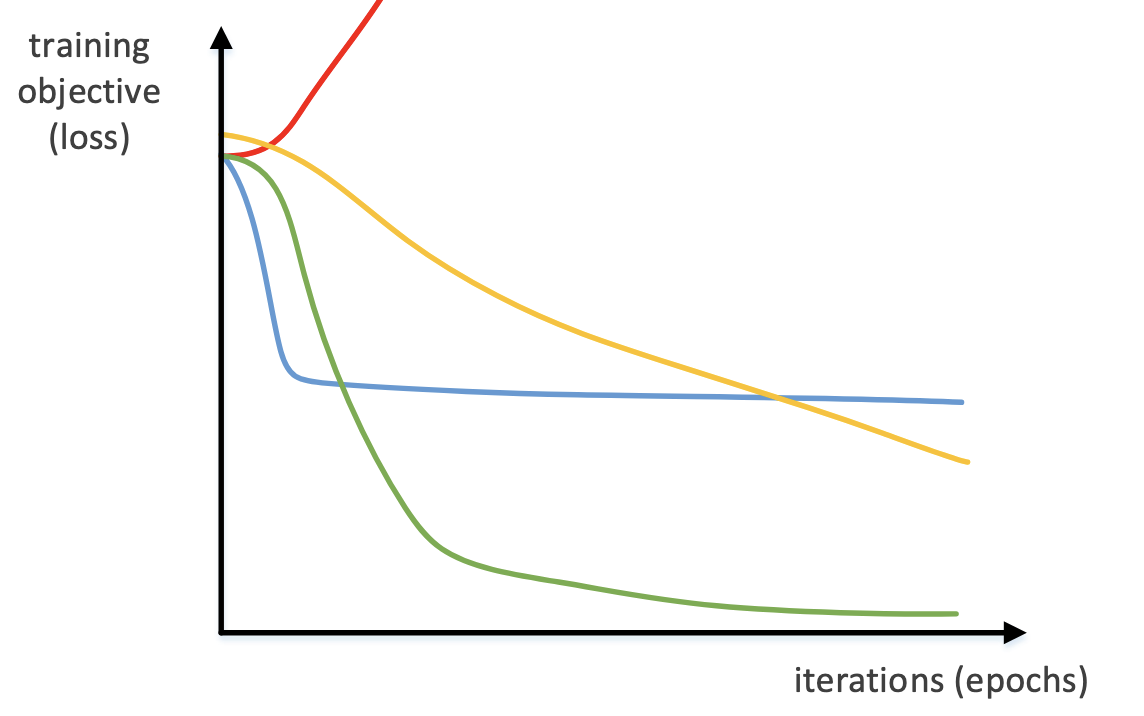
The learning rate is probably too high, you have exploding gradients.
How would you diagnose the problem with the yellow curve?
You have a low learning rate and can’t escape local minima.
How would you diagnose the problem with the blue curve?
The learning rate is probably too high, you have a big step down and then caught on a local minimum.
How would you diagnose the problem with the red dotted curve?
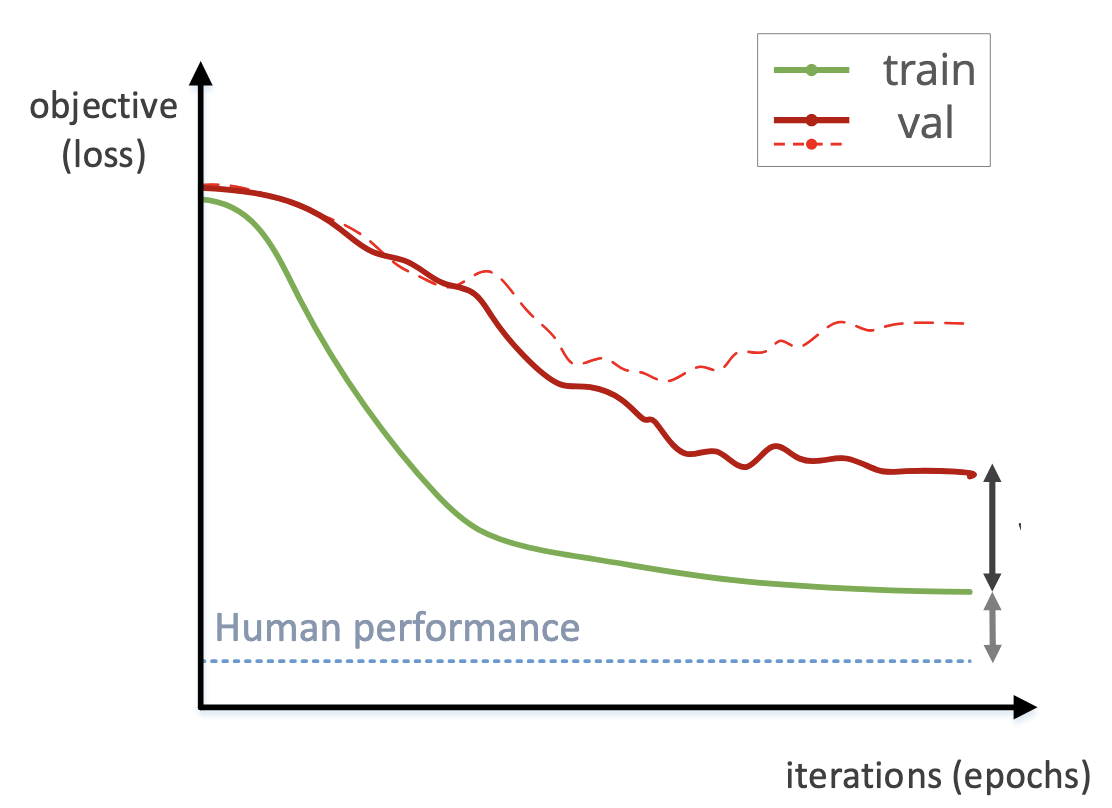
You are likely overfitting the training data.
What is the black gap called here, and how could you reduce it?
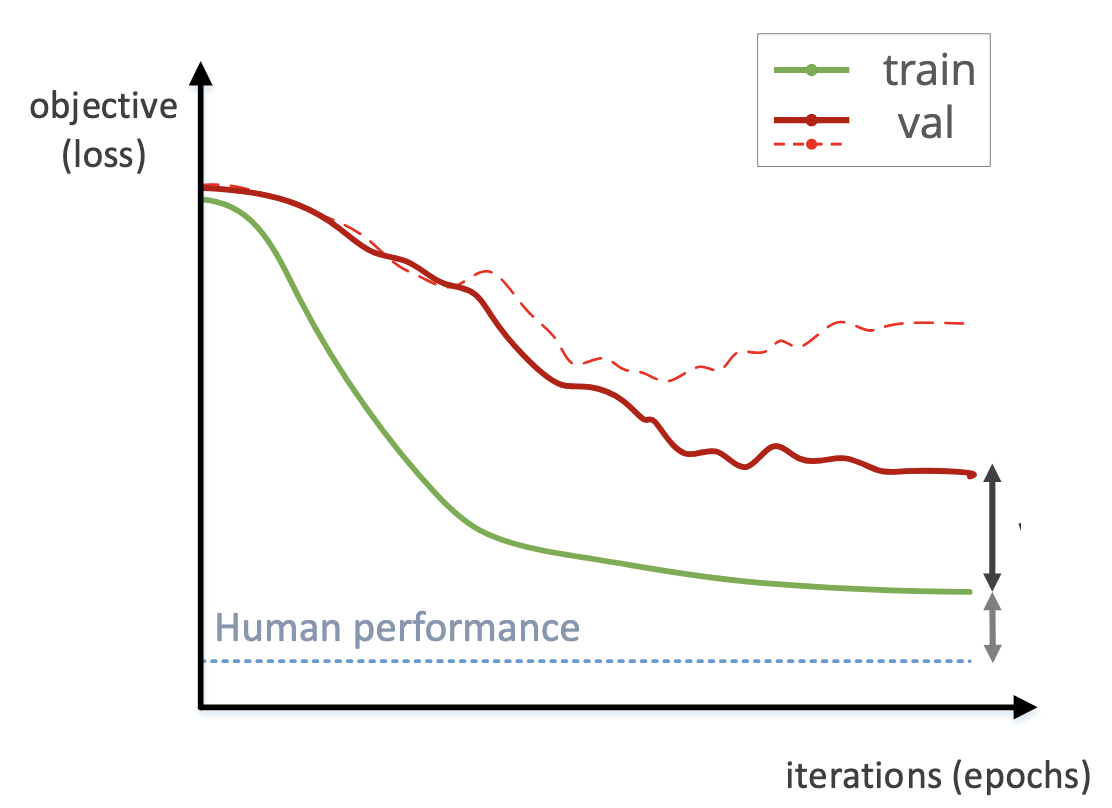
This is variance: try more data, augmentations, regularisation.
What is the grey gap called here, and how could you reduce it?
This is bias: Try a bigger model or train for longer.
Why have a distinction between the trainval set and the val set?
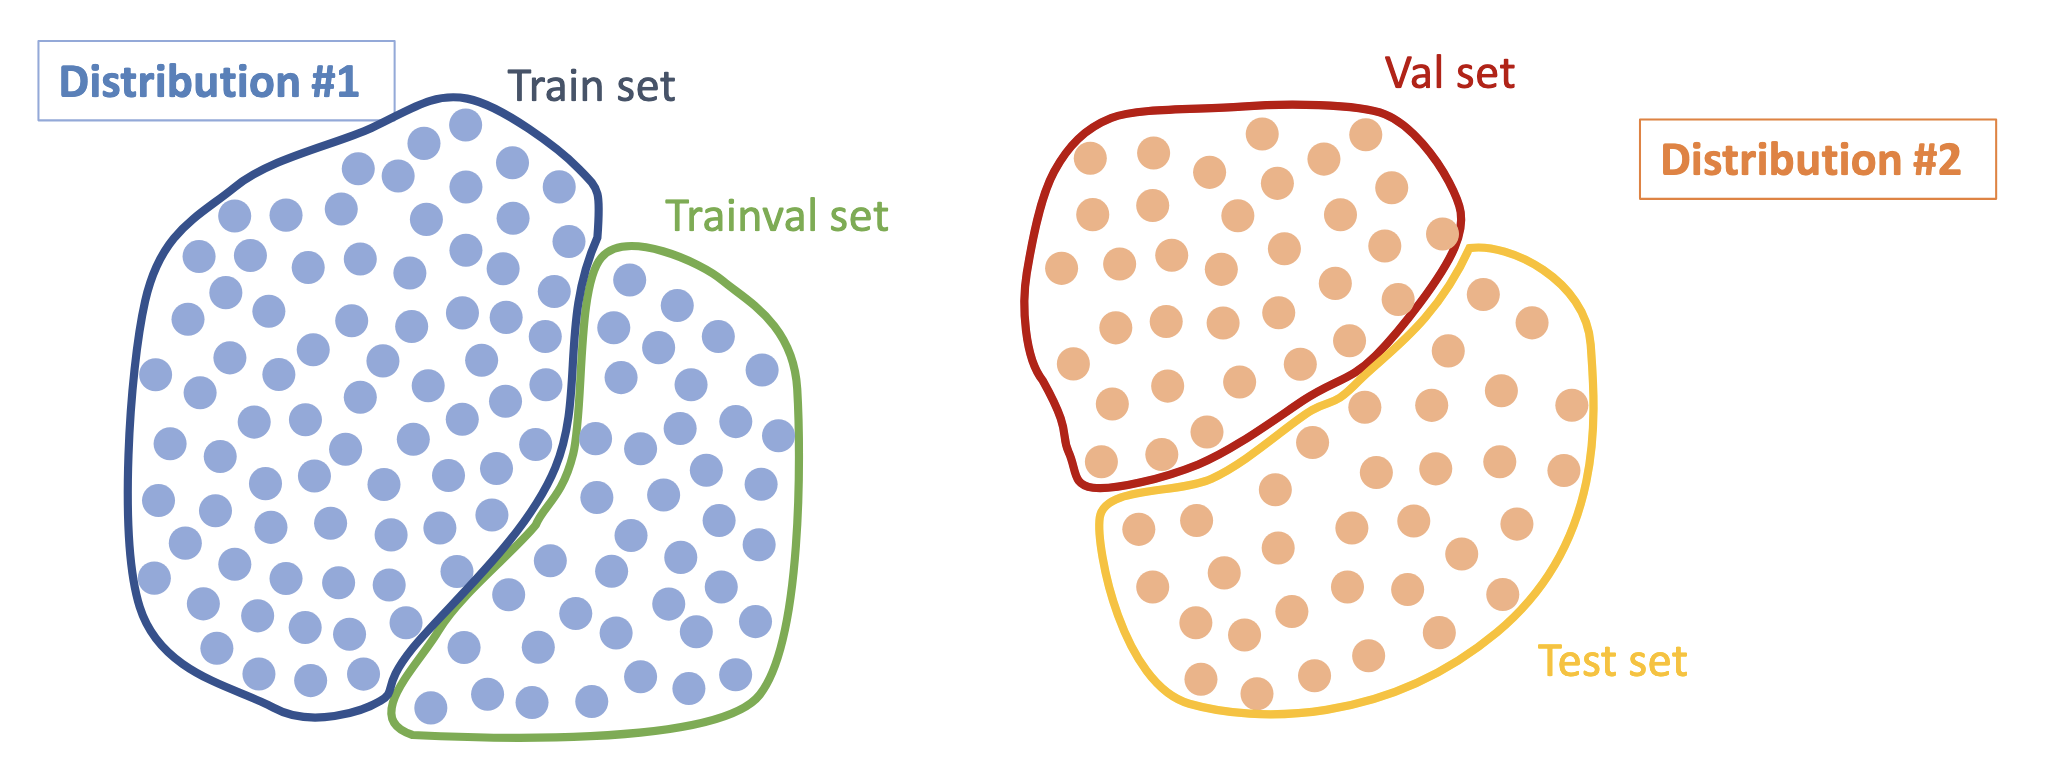
Trainval is used to tune within the training domain, the validation set is used to assess cross-domain transfer.
Bite-sized
@Justify the bias / variance interpretation of the gap between train and validation curves.
- Bias is the gap between human-level (or Bayes-optimal) performance and the training loss. A large bias gap means the model is too weak to fit even the training data — it underfits. Fixes: bigger model, more parameters, train longer, lower-bias architecture.
- Variance is the gap between training loss and validation loss. A large variance gap means the model has fit the training set well but does not generalise — it overfits. Fixes: more data, augmentations, regularisation (L1/L2, dropout, early stopping), simpler model.
In a single train/val loss-vs-epoch plot:
- (human ↔ training) is the bias gap.
- (training ↔ validation) is the variance gap.
This frames each diagnostic move in terms of which gap you’re trying to close.
Manual learning-rate annealing: when the validation loss curve plateaus (stops improving), decrease the learning rate (typically by a factor of $10$). This is a common ingredient of recipes like SGD-with-step-decay.
@Describe early stopping as a regularisation strategy and what training-curve trigger it relies on.
Early stopping monitors the validation loss during training. After every epoch, save a checkpoint if the validation loss improved. When validation loss starts going up (rather than down) — even though training loss is still decreasing — the model is overfitting. Stop training and revert to the best checkpoint.
Conceptually, this implicitly regularises the model by limiting the number of optimisation steps, preventing the weights from drifting into highly overfit configurations. It’s the laziest regulariser available — no architectural change, no extra hyperparameter to tune beyond the patience window.
When training and test data come from different distributions (e.g. the model is trained on web images but deployed on phone photos), the lecture recommends introducing a trainval set drawn from the training distribution as a separate evaluation slice. If validation error is high but trainval error is low, the issue is distribution shift (need more data from distribution #2); if both errors are similar, the issue is variance.
@Describe four standard mitigations for high variance (overfitting) on the validation set.
- More training data: the simplest and usually most effective. Adding samples reduces the model’s ability to memorise individual instances.
- Data augmentation: synthetic data multiplication via random crops, flips, colour jittering, etc. Cheap and surprisingly effective at acting like more data without the labelling cost.
- Regularisation: $L _ 1$/$L _ 2$ weight penalties, dropout, batch norm, weight decay. Constrain the optimiser’s effective hypothesis class.
- Smaller model / fewer parameters: reduces capacity. Counterpart of “make the model bigger” for bias issues.
Combining several of these (e.g. data augmentation + dropout + weight decay) is standard practice for modern CNN training.
The exploding-gradient failure mode in training looks on a loss-vs-epoch curve as the loss shooting upward (typically to infinity or NaN), often after a short period of decreasing. It is most often caused by learning rate set too high, or by numerically unstable layers without normalisation.
@Describe how the learning-rate-vs-loss curve typically looks for very high, very low, mediocre, and good choices of learning rate, and what diagnostic value this gives.
- Very high LR: training loss explodes — the curve shoots upward, gradients diverge.
- High LR (but not catastrophic): loss takes a big step down quickly then gets stuck oscillating around a local minimum or plateau, never reaching the lowest achievable value.
- Very low LR: loss decreases extremely slowly, may never reach the optimum within a reasonable training budget.
- Good LR: steady, monotone-ish decrease to a low final loss.
Diagnostic use: plot training loss vs iterations, and if validation loss plateaus during training, anneal the learning rate (manual annealing — e.g. step decay).