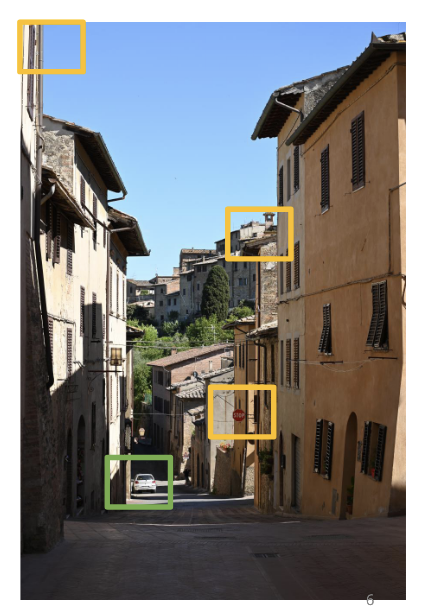
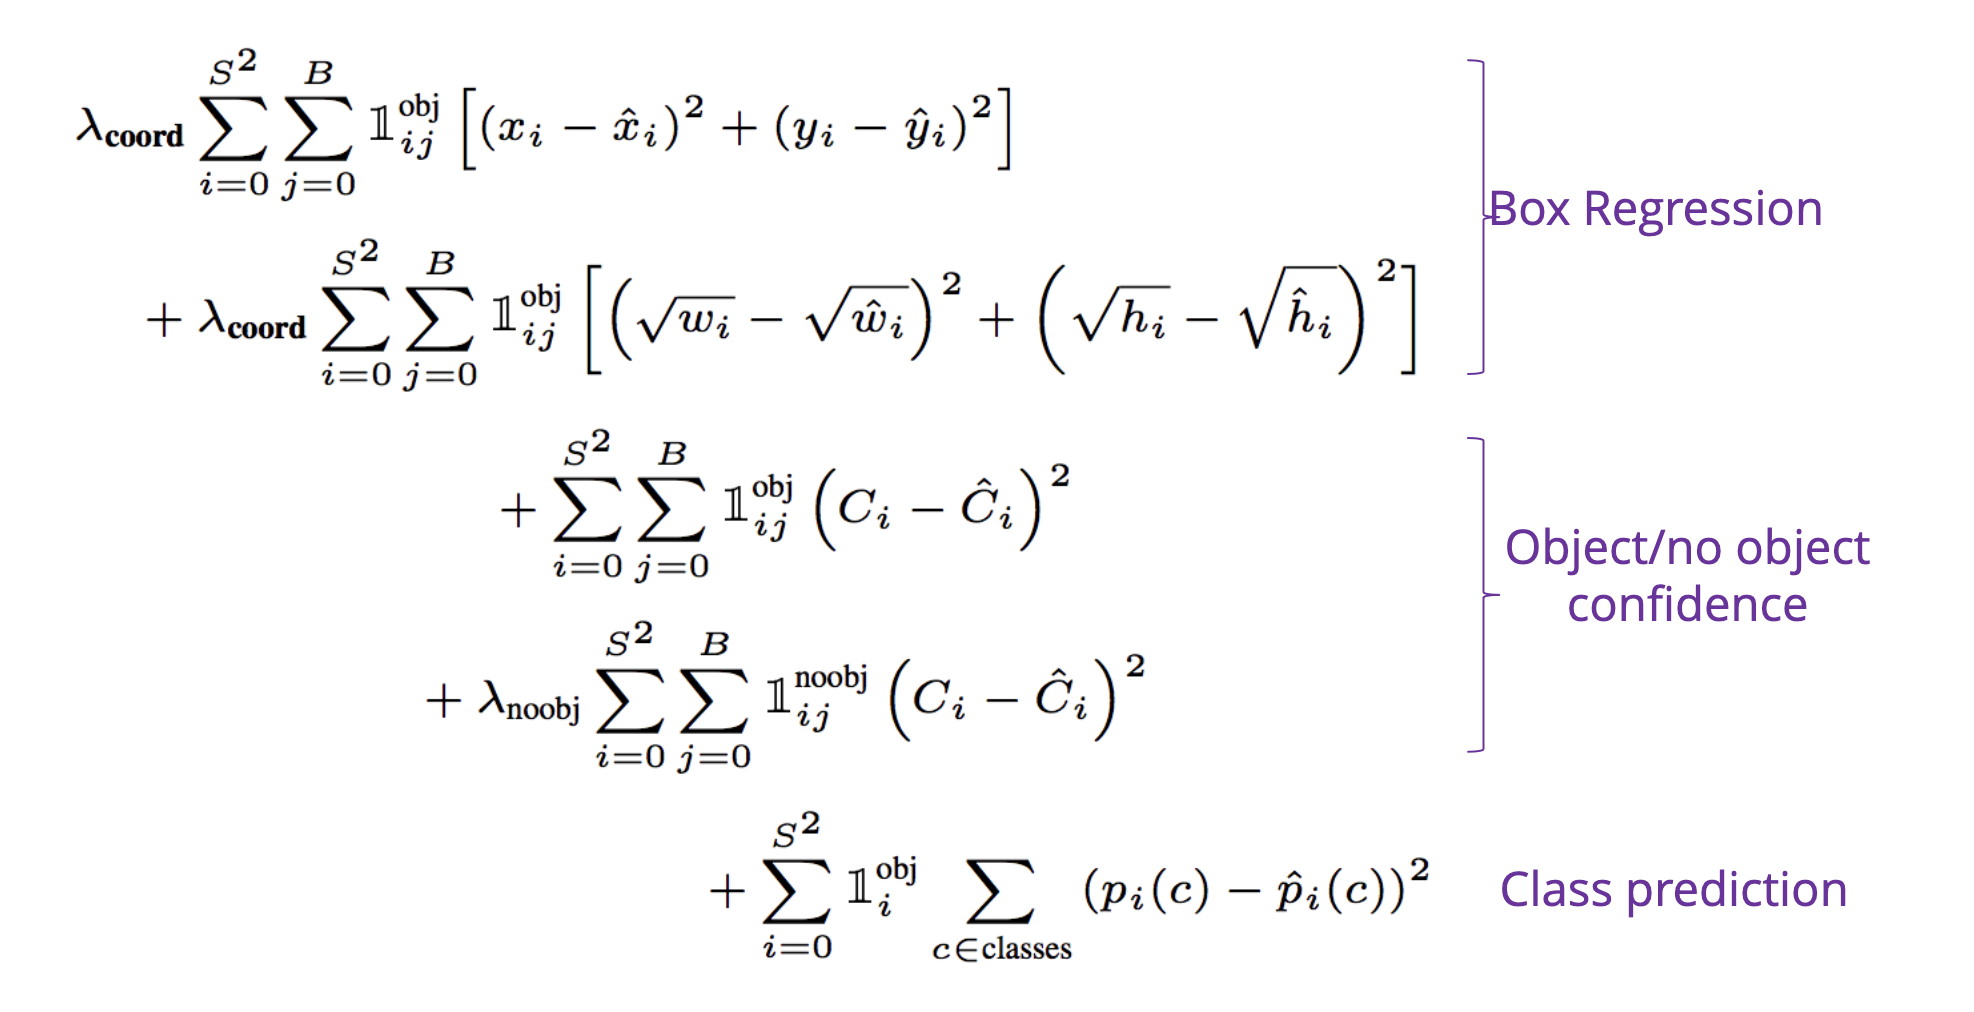Rather than classify the subject of one image, we instead want to find the location of an object in the image, typically in the form of a labelled bounding box $(x, y, w, h, c)$.
@Describe the sliding window approach to object classification.
Apply edge filters for a discrete approximation of several angles
Use a pooling operation to combine these extracted edges
Use layer norm to normalise histograms
Flatten into a single feature vector
Suppose you have trained an SVM $f(x) = w^\top x + b$ to classify person versus background using HoG features. How could you @visualise what the SVM has learned?
A HoG descriptor $x$ has the structure of one entry per spatial cell and orientation bin. Since $w$ is applied to this description, $w$ has the same structure of one weight per spatial cell and orientation. So you may plot $w$ in the same layout HoG features are usually drawn in: at each spatial cell, sketch the orientation bins as small oriented line segments whose brightness/length scales with the weight magnitude.
Splitting into positive and negative weights gives two complementary maps:
$w _ i > 0$, which tends to look like a person silhouette (heads, shoulders, torso and legs)
$w _ i < 0$, which tends to look for orientations and locations that suggest there is no person
A linear SVM is doing template matching in feature space, since it checking how well the HoG of a window aligns with $w$. Visualising $w$ this way shows that the “template” the SVM has learned is a personal silhouette.
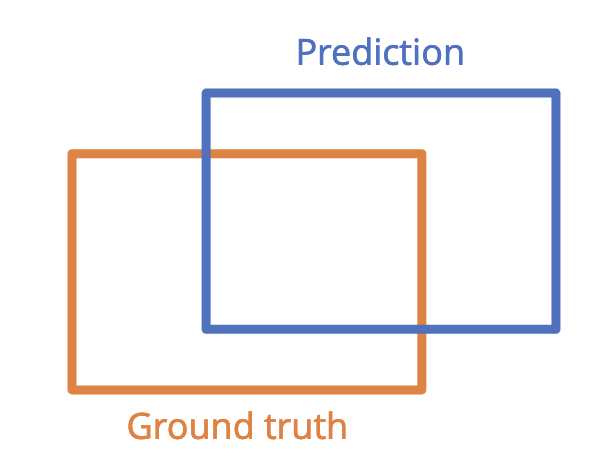
How would IoU calculate the score for the predicted bounding box versus the ground truth bounding box?
The ground truth annotation is already covered by a better-fitting prediction.
State the @algorithm which evaluates an object detection model which gives predictions $(\hat x, \hat y, \hat w, \hat h, \hat c)$ of bounding boxes in an image.
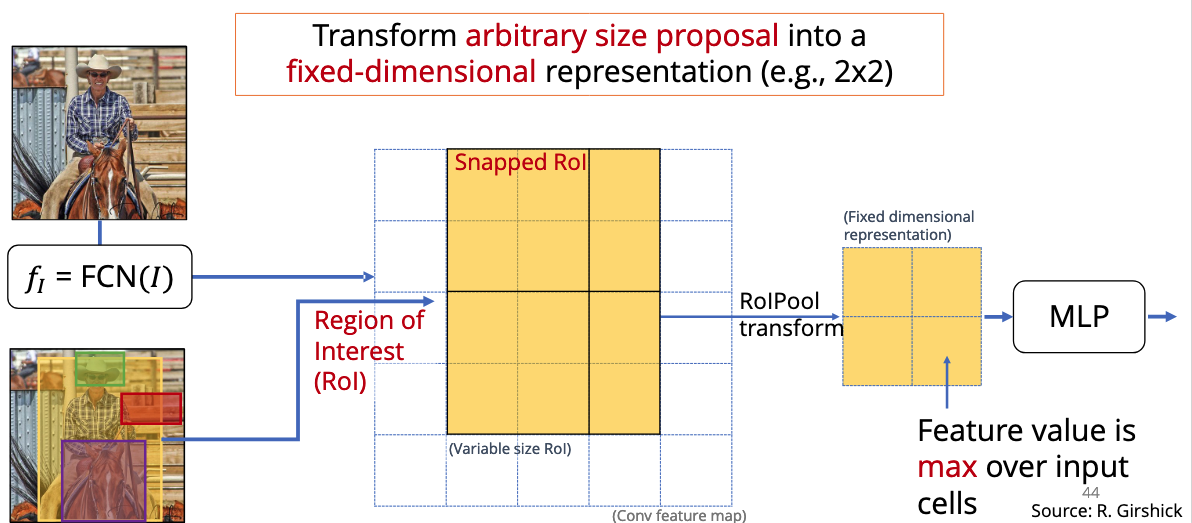
A model using an object proposal algorithm (e.g. selective search) modifies the proposed region during the prediction in order to improve localisation.
It says it in the slide: the feature value is the max over input cells. The input cells are obtained by splitting the snapped RoI into (maybe uneven) bins using integer division.
@Define what is meant by a region proposal network (RPN) in the context of object detection?
A network which takes a fixed size anchor box over an image and predicts whether it is likely to contain an object.
@Describe the structure of a Region Proposal Network (RPN) and what it predicts at each spatial location, and show how it is used in the Faster R-CNN model.
Setup: A sliding window passes over a convolutional feature map. At each spatial location, $k$ anchor boxes of different scales and aspect ratios are placed over the image.
Output per location:
Classification: object / not object per anchor box
Regression: Predicted offsets $(\Delta x, \Delta y, \Delta w, \Delta h)$ per anchor
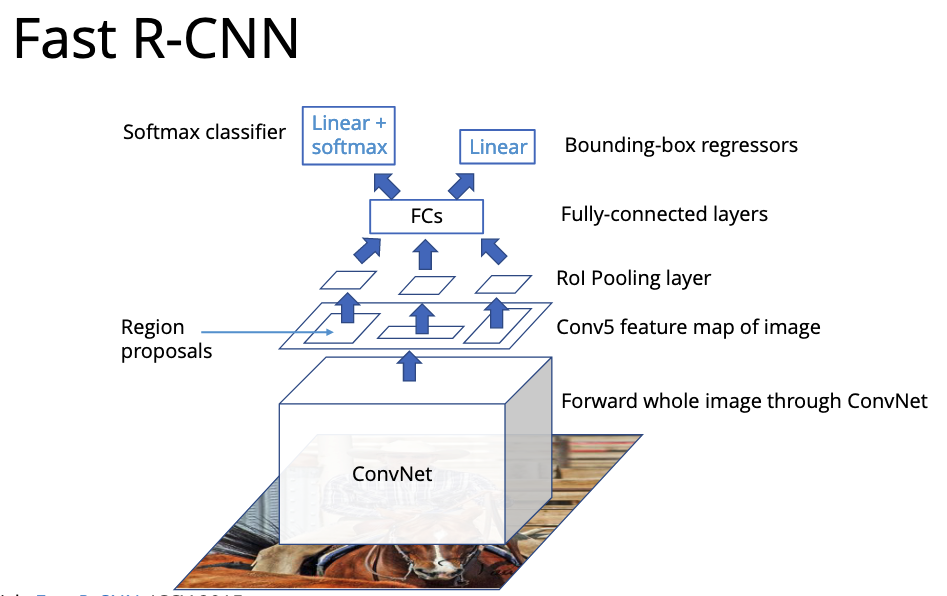
Selective Search proposes ~2000 regions, each is warped and passed through a CNN, then classified with an SVM with bounding-box regression.
One CNN pass per proposal, hence slow.
Fast R-CNN:
One CNN pass over the whole image, RolPool extracts fixed-size features for each proposal from the shared feature map, which are fed to a FC head for softmax classification and box regression.
Selective Search is still used for the region proposals.
Faster R-CNN:
Replaces Selective Search with a learned Region Proposal Network (RPN) sharing the same backbone.
@Define offset prediction (bounding box regression) in the context of object detection.
The detector does not predict absolute box coordinates. Given a default box (i.e. e.g. a proposal from selective search in R-CNN, or an anchor in an RPN), it predicts an offset $(\Delta x, \Delta y, \Delta y, \Delta h)$, the correction needed to transform the default box into the predicted box.
What is meant by a “two-stage detector” in the context of object detection, and what is the name of the technique for a “one-stage detector”?
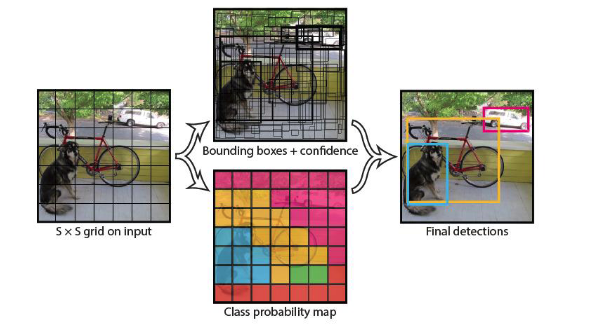
Predict class label and a few candidate bounding boxes for each grid cell
The YOLO architecture divides an image into a coarse grid, predicts a class label and a few candidate boxes for each grid cell.
Since we are doing lots of things in a single forward pass (“You Only Look Once”), the model needs to be trained to do lots of things simultaneously:
Correctly perform box regression to correctly predict the location
Determine whether a box contains or does not contain an object
Correctly classify the class of the object in each box
This gives a training loss like:
where:
The image has been divided into an $S \times S$ grid of cells
Each cell predicts $B$ candidate bounding boxes
Each box prediction is $(\hat x, \hat y, \hat w, \hat h, \hat C)$, a centre, size, and a confidence that a box contains the object
Each cell predicts a single class distribution $\hat p(c)$ shared across its $B$ boxes
and
$1^\text{obj} _ {ij}$ equals $1$ iff cell $i$ and contains a ground-truth object and predictor $j$ is “responsible” for it, where amongst the $B$ predictors in a cell, only one is responsible per object, typically the one whose predicted box has the highest IoU with the ground truth.
$1^\text{noobj} _ {ij}$ equals $1$ iff predictor $j$ in cell $i$ is not responsible for any object
\[\lambda _ \text{coord} \sum _ {i,j} 1^\text{obj} _ {ij} \left[ (x _ i - \hat x _ i)^2 + (y _ i - \hat y _ i)^2 \right]\]
This is the squared error on the centre coordinates, but only for the predictor responsible for the object. This is upweighted by a large $\lambda _ \text{coord}$, to prevent the loss from being dominated by the no object term which is much more frequent.
This is the squared error on the size of the box, but we use $\sqrt{\cdot}$ to shrink the gradient for large boxes, so that small-box errors gets more weight, for which accurate sizes are more important.
Object confidence:
\[\sum _ {i,j} 1^\text{obj} _ {ij} (C _ i - \hat C _ i)^2\]
The predictors confidence should match the ground-truth confidence (typically the IoU between the predicted and GT box, so the predictor is trained to predict its own quality).
No-object confidence
\[\lambda _ \text{noobj} \sum _ {i,j} 1^\text{nobj} _ {ij} (C _ i - \hat C _ i)^2\]
The same, but for the predictors that aren’t responsible for any object. This teaches the model that it should output low confidence of such boxes. The $\lambda _ \text{noobj}$ term is important since there are many more no-object terms than there are object ones.
Class prediction:
\[\sum _ i 1^\text{obj} _ i \sum _ {c \in \text{classes}}(p _ i(c) - \hat p _ i(c))^2\]
Squared error between the predicted class distribution and the one-hot ground truth.
@Describe the Detection Transformer (DETR) and its innovations over previous approaches.
Innovations: reframes object detection as set predictions, so that the model outputs a fixed-size, unordered set of $N$ detections with no fixed identity per output. This contrasts with the R-CNN family (one prediction per region proposal) and anchor-based detectors (one prediction per anchor position), where each output’s identity is tied to a specific spatial location. DETR uses bipartite matching, which means that the whole pipeline is end-to-end differentiable.
Architecture:
Backbone: a CNN extracts image features.
Transformer encoder: takes flattened features + positional encodings, and produces a contextualised feature sequence.
Transformer decoder: $N$ learned object queries attend over the encoder output, and each query becomes a candidate detection.
Prediction heads: an FFN per query predicts either (class, bounding box), or the “no object” class $\emptyset$.
Training:
Predictions and ground-truth boxes are matched 1-to-1 via bipartite matching, using a per-pair cost combining class probability and box similarity.
Because each prediction is committed to a unique ground-truth box at training time, duplicate detection of the same object are penalised, which makes determining which boxes to keep unnecessary.
Bite-sized
HOG-based pedestrian detection was introduced by Dalal & Triggs, CVPR 2005. The pipeline is: sliding window over the image → HOG descriptor per window → binary SVM classifier predicting person vs background.
Selective Search for object proposals was introduced by Uijlings, van de Sande, Gevers, Smeulders, IJCV 2013. It produces ~2000 region proposals per image with >95% recall on relevant objects, by performing hierarchical segmentation based on colour uniformity and image edges.
R-CNN was introduced by Girshick, Donahue, Darrell, Malik, 2013 as “Regions with CNN features”. Pipeline: ~2000 Selective Search proposals → warp each to fixed size → pass through AlexNet pre-trained on ImageNet, fine-tuned on PASCAL → SVM classification of fc7 features.
Multi-scale + multi-aspect-ratio defaults: at each spatial location of the conv feature map, place $k$ anchor boxes (typically $k = 9$): 3 scales × 3 aspect ratios. Together they tile the image with a dense set of candidate boxes that cover a wide range of object sizes and shapes.
IoU-based assignment to GT: at training time, each anchor is matched to ground-truth boxes by IoU. An anchor is positive if its best-matching GT has IoU above a threshold (e.g. 0.7), or if it is the highest-IoU anchor for some GT (so every GT is matched). It is negative if its best-IoU GT is below 0.3. Anchors in between are ignored.
Offset encoding $(t _ x, t _ y, t _ w, t _ h)$: the RPN does not predict absolute box coordinates. Instead it predicts the offset/correction needed to transform the default anchor into the predicted box, typically in transformed/normalised coordinates: $t _ x = (x - x _ a)/w _ a$, $t _ w = \log(w/w _ a)$, etc. This decoupling lets the same set of anchors handle widely varying object sizes.
Source Lecture 10, RPN with Multiple Anchors and Bounding Box Regression slides.
An anchor-box detector outputs a fixed grid of $W'H'$ predictions (each a box plus an $(N+1)$-dimensional class distribution), but a training image has a variable number $M _ j$ of ground-truth boxes. How is this count mismatch reconciled during training, how is the loss computed, and why must the per-anchor classification be set up this way?
Reconcile the counts (IoU assignment): there is no fixed pairing between the $W'H'$ anchors and the $M _ j$ GT boxes, so each anchor is given a target by IoU (∆bite-anchor-box-detail) — positive if it overlaps a GT well (or is that GT’s best anchor, so every GT is covered), negative / background if its best IoU is below a low threshold, ignored in between. A positive inherits that GT’s class and box; a negative’s target is the background class.
Loss (multi-task, over the assigned anchors):
Classification: softmax cross-entropy over the $N+1$ classes, on all matched anchors (positives → GT class, negatives → background).
Localisation: smooth-$L _ 1$ on the predicted offset vs the matched GT, on positive anchors only (background has no box).
$\mathcal L = \mathcal L _ \text{cls} + \lambda\,\mathcal L _ \text{loc}$, with hard-negative mining / a fixed positive:negative ratio to tame the imbalance.
Why it must be done this way:
Fixed output, variable targets: the grid is fixed-size with no natural ordering while the object count varies per image, so every prediction needs an explicitly assigned target before any per-anchor loss can be defined.
The background class is essential: most anchors match nothing and must be trained to predict “background”, otherwise the detector fires a box at every location — a flood of false positives (∆imagenet-no-background-class-problem).
Positives-only localisation + imbalance: background has no box to regress to, and negatives vastly outnumber positives, so the foreground signal is drowned without rebalancing.
(DETR avoids the hand-tuned IoU thresholds via a one-to-one bipartite Hungarian matching between predictions and ground truth, ∆bite-detr-citation.)
Source CV 2025 Q2(d); Lecture 10, RPN with Multiple Anchors and Multi-task Loss slides.
DETR was introduced by Carion et al., ECCV 2020 as “End-to-end object detection with transformers”. Its three innovations are: (i) reformulates detection as set prediction with a fixed-size unordered output, (ii) uses a transformer encoder-decoder with learned object queries, (iii) trains with a bipartite matching loss between predictions and ground truth.
The Viola-Jones face detection algorithm (2001) is a cascaded classifier: a sequence of progressively more complex classifiers, each with low precision but high recall, designed to throw out easy negatives early and reserve expensive computation for hard cases. It runs in real time on 2001 hardware.
A bounding box in object detection is typically parameterised as $(x, y, w, h, c)$, where $(x, y)$ is the box centre, $w$ and $h$ are the width and height, and $c$ is the predicted class (or class confidence vector).
A centre-distance metric ignores box size and shape: a tiny predicted box that happens to be centred on the ground truth has zero centre distance but covers almost none of the object. A large box wildly bigger than the GT can also score zero centre distance but is barely correct.
IoU $= \tfrac{ \vert GT \cap \mathrm{Pred} \vert }{ \vert GT \cup \mathrm{Pred} \vert }$ jointly evaluates centre, size, and aspect ratio in a single number bounded in $[0, 1]$:
Both boxes must overlap at all (intersection $> 0$) to score $> 0$.
A tightly-fitting prediction has intersection $\approx$ union, hence $\mathrm{IoU} \approx 1$.
Excessive size disagreement inflates the union and shrinks the IoU.
It also has a natural thresholding interpretation — “match if IoU > 0.5” — which feeds into the AP / mAP evaluation directly.
Source Lecture 10, Intersection over Union slide.
@Justify the use of $\sqrt{w}$ and $\sqrt{h}$ rather than $w, h$ in YOLO’s box-size regression term.
If $w$ and $h$ were used directly, a fixed absolute error of (say) 10 pixels on a $20$-pixel-wide box would have the same loss as 10 pixels on a $400$-pixel-wide box. But the relative error is very different: 50% vs 2.5%. Squared-error of raw $w$ is therefore biased toward optimising large boxes and ignoring small-box errors.
The $\sqrt{\cdot}$ transform compresses large values more than small ones. So a 10-pixel error on a small box now contributes proportionally more to the loss than a 10-pixel error on a large box, restoring some balance between detecting small and large objects.
This is partial compensation — modern losses like GIoU/CIoU treat scale-invariance more principally — but it’s the simple trick that made YOLO work.
Source Lecture 10, YOLO – Training Loss slide.
Faster R-CNN replaces R-CNN/Fast R-CNN’s Selective Search proposals with a Region Proposal Network (RPN) that shares the same backbone as the detector. This is the structural change that made detection end-to-end trainable and substantially faster.
Source: Lecture 10, Region Proposal Network (RPN) slide; Ren, He, Girshick, Sun 2015.
The HOG descriptor (∆hog-as-cnn-implementation) is a small fixed CNN: oriented edge filters give the gradient responses (a conv layer), pooling sums them into a per-cell orientation histogram, L2-normalisation rescales each cell, and flattening concatenates the cells into one feature vector. It is also the template a linear SVM matches against (∆svm-weight-visualisation-hog). Click a cell to step through its pipeline.
The Histogram of Oriented Gradients descriptor is exactly a small fixed convolutional network. Each stage of HOG is a standard CNN layer:
convoriented edge filters at \(K\) angles
poolsum responses over each cell into an orientation histogram
layer-normL2-normalise each cell's histogram
flattenconcatenate all cells into one descriptor
Input image
Image
Parameters
orientations \(K\)cells / side
Visualising Average Precision
The evaluation algorithm (∆ap-evaluation-algorithm) matches predicted boxes to ground-truth boxes by IoU (∆iou-formula), then sweeps the confidence threshold to trace a precision-recall curve whose area is the Average Precision. The visualisation makes the bookkeeping concrete: lower the confidence threshold to pull in more boxes and watch recall climb, raise the IoU threshold to demand tighter boxes, and see why duplicate detections and boxes on nothing count as false positives while a missed object caps recall.
To score an object detector its predicted boxes are matched to the ground-truth boxes. A prediction is a true positive if it overlaps an unmatched ground-truth box by at least the threshold \(t_{\mathrm{IoU}}\), where \(\mathrm{IoU}=\frac{\lvert\mathrm{GT}\cap\mathrm{Pred}\rvert}{\lvert\mathrm{GT}\cup\mathrm{Pred}\rvert}\); otherwise it is a false positive, and a ground-truth box with no match is a miss. Sweeping the confidence threshold \(t_{\mathrm{conf}}\) from high to low traces a precision–recall curve, and Average Precision is the area under it.