Computer Vision MT25, Representation learning
- Course - Computer Vision MT25U
- Notes - Computer Vision MT25, Image representationU
- Notes - Computer Vision MT25, Image classificationU
- Notes - Computer Vision MT25, Scale-invariant feature transformU
- Notes - Computer Vision MT25, Loss function designU
- See also:
- Learning to Compare Image Patches via Convolutional Neural Networks (2015)
Flashcards
How does representational learning differ from more general machine learning setups?
Generally you learn a function from the input to task output, in representational learning you learn a general-purpose representation which can then be used for downstream tasks.
How does representation learning differ in a supervised vs unsupervised context?
- Supervised: Given a specific task, learn a domain-specific representation which is often constrained to this particular task.
- Unsupervised: Given only the data, find a representation for it which often does not align exactly with the task.
What are some of the issues with hand-crafted representations?
- It’s hard to find the “discriminative signature” for a problem
- Even if you find the discriminative signature, it can be hard to implement programmatically
- Many different signals need to be combined, which itself is a difficult problem
Give an @example of a handcrafted image representation.
The SIFT descriptor.
@Describe and @visualise the approach you might use to learn a keypoint descriptor (i.e. a representation of an image patch such that different images of the same keypoint have similar descriptors).
- Use a dataset with known point correspondences
- Extract patches around keypoints
- Use positive examples of matching keypoints and negative examples using random keypoints
- Train a model to predict the similarity between two patches
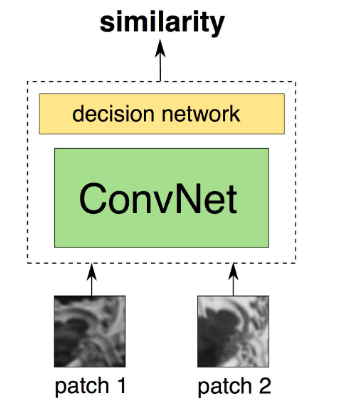
@Visualise and @describe the three different architectures considered in “Learning to Compare Image Patches via Convolutional Neural Networks (2015)” for determining if two image patches correspond to the same keypoint.
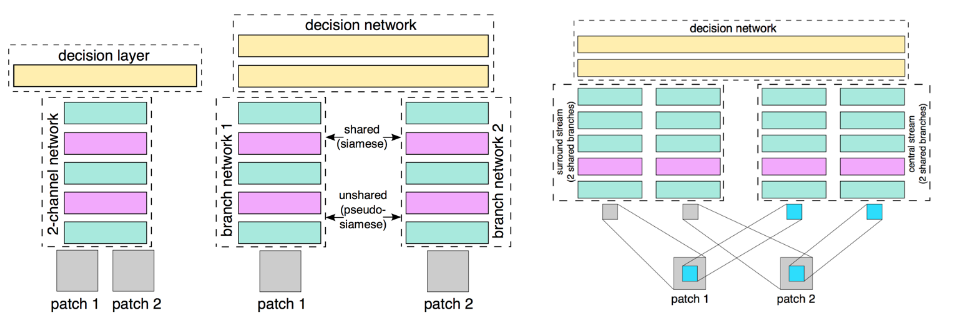
All three map a pair of patches to a similarity score. They differ in how early the two patches interact, and whether a reusable per-patch descriptor falls out.
2-channel (left): stack the two patches into a single 2-channel image and feed it through one network topped by a decision layer. The patches interact from the first layer, making it the most expressive. The drawback is that there is no separable descriptor, so the whole network must be re-run for every pair.
Siamese / pseudo-siamese (middle): one branch network per patch, whose outputs are concatenated and passed to a decision network. Siamese ties the two branches’ weights (shared), pseudo-siamese leaves them unshared. Each branch output is a reusable descriptor, so one patch can be compared against many cheaply.
Central-surround two-stream (right): a multi-resolution design. Each patch is split into a downsampled surround crop and a high-resolution central crop. A surround stream and a central stream, each a siamese pair of branches, process these separately, and both streams feed a shared decision network.
SIFT is an algorithm which determines a set of keypoints in an image and then calculates keypoint descriptors for each of these. What does LIFT stand for, and how does it differ?
- LIFT: Learned Invariant Feature Transform
- In SIFT, the keypoints to choose and their corresponding descriptors are determined by a hand-crafted algorithm.
- In LIFT, the keypoints to choose and their corresponding descriptors are determined using a trained model.
What are the typical problems with learned image descriptors versus hand-crafted ones?
- Might not generalise to unseen domains
- Typically slower than hand-crafted
- Less interpretable
In supervised image representation learning, what does the training data generally look like?
A set of samples $\{ x _ i \}$, subdivided into positive $\{ x _ {i, j}^+ \}$ and negative $\{ x _ {i, k}^- \}$ examples.
Suppose we have a set of samples $\{ x _ i \}$ and corresponding positive $\{ x _ {i, j}^+ \}$ and negative $\{ x _ {i, k}^- \}$ examples, and a function $f : \mathcal D \to \Phi$.
@Define the cosine similarity loss in this context, and how it is typically approximated.
Let $J _ i$ be the number of positive examples and $K _ i$ be the number of negative examples. Then:
\[\mathcal L _ {\cos}(\phi _ i) = -\frac{1}{J _ i} \sum^{J _ i} _ {j = 1} \mathcal S _ {\cos}(\phi _ i, \phi _ {i, j}^+) + \frac{1}{K _ i} \sum^{K _ i} _ {k = 1} \mathcal S _ {\cos} (\phi _ i, \phi _ {i, k}^-)\]where $\mathcal S _ {\cos}$ denotes cosine similarity. Since these sums might be large, it’s typically approximated by choosing randomly one positive and negative example:
\[\mathcal L _ {\cos}(\phi _ i) = -\mathcal S _ {\cos}(\phi _ i, \phi _ i^+) + \mathcal S _ {\cos}(\phi _ i, \phi _ i^-)\]Suppose:
- We have a set of samples $\{ x _ i \}$ and corresponding positive $\{ x _ {i, j}^+ \}$ and negative $\{ x _ {i, k}^- \}$ examples
- An embedding function $f : \mathcal D \to \Phi$
- $J _ i$ and $K _ i$ are the number of positive and negative examples respectively
In this context, the cosine similarity loss is given by:
\[\mathcal L _ {\cos}(\phi _ i) = -\frac{1}{J _ i} \sum^{J _ i} _ {j = 1} \mathcal S _ {\cos}(\phi _ i, \phi _ {i, j}^+) + \frac{1}{K _ i} \sum^{K _ i} _ {k = 1} \mathcal S _ {\cos} (\phi _ i, \phi _ {i, k}^-)\]
What’s the problem with this approach?
It forces positive pairs to be almost identical and negative examples to be fully dissimilar.
Suppose:
- We have a set of samples $\{ x _ i \}$ and corresponding positive $\{ x _ {i, j}^+ \}$ and negative $\{ x _ {i, k}^- \}$ examples
- An embedding function $f : \mathcal D \to \Phi$
@Define the triplet loss $\mathcal L _ \text{triplet}(\phi, \phi^+, \phi^-)$ in this context given an arbitrary similarity function $\mathcal S$, perhaps (negative) $L _ 2$ distance or cosine similarity. What’s the intuitive interpretation of this loss?
where $\epsilon$ is some constant.
Intuitively, this is enforcing a relative order on the similarities of positive and negative examples.
Suppose:
- We have a set of samples $\{ x _ i \}$ and corresponding positive $\{ x _ {i, j}^+ \}$ and negative $\{ x _ {i, k}^- \}$ examples
- An embedding function $f : \mathcal D \to \Phi$
In this context, the triplet loss $\mathcal L _ \text{triplet}(\phi, \phi^+, \phi^-)$ is given by:
\[\mathcal L _ \text{triplet}(\phi, \phi^+, \phi^-) = \max(0, \mathcal S(\phi, \phi^-) - S(\phi, \phi^+) + \epsilon)\]
where $\epsilon$ is some constant. Why might this be slow, and how can you speed this up using batch-based training?
This requires three evaluations of $f$ per loss calculation, which might be slow if $f$ is a complicated neural network.
If training over a batch, then you can save calculating the embeddings for lots of negative samples by using the embeddings of the other batch elements as negative examples.
Suppose:
- We have a set of samples $\{ x _ i \}$ and corresponding positive $\{ x _ {i}^+ \}$ examples.
- An embedding function $f : \mathcal D \to \Phi$
- We are training over a batch of $B$ elements
@Define the contrastive loss in this context.
where:
- $\phi _ i = f(x _ i)$ and $\phi _ i^+ = f(x _ i^+)$ are the embeddings of the anchor and its positive
- $\mathcal S$ is a similarity function, typically cosine similarity $\mathcal S(u, v) = u^\top v / (\|u\| \, \|v\|)$, or just a dot product
- the sum in denominator runs over all $B$ batch elements (the other $B-1$ elements act as negatives)
Suppose:
- We have a set of samples $\{ x _ i \}$ and corresponding positive $\{ x _ {i}^+ \}$ examples.
- An embedding function $f : \mathcal D \to \Phi$
- We are training over a batch of $B$ elements
In this context, the contrastive loss is defined by
\[\mathcal L _ \text{cont}(\phi _ i, \phi _ i^+) = -\log \frac{\exp(\mathcal S(\phi _ i, \phi _ i^+))}{\sum^B _ {k=1} \exp(\mathcal S(\phi _ i, \phi _ k))}\]
How can you interpret this in terms of cross-entropy loss?
Imagine you had a classifier that computed the embeddings $\phi _ i$ of the input, and then at the final layer computed the similarities across all the classes. Assuming the similarity function $\mathcal S$ were fixed, contrastive loss is the cross-entropy loss you would use to tune the embedding model.
@Visualise how the loss is computed in the CLIP model.
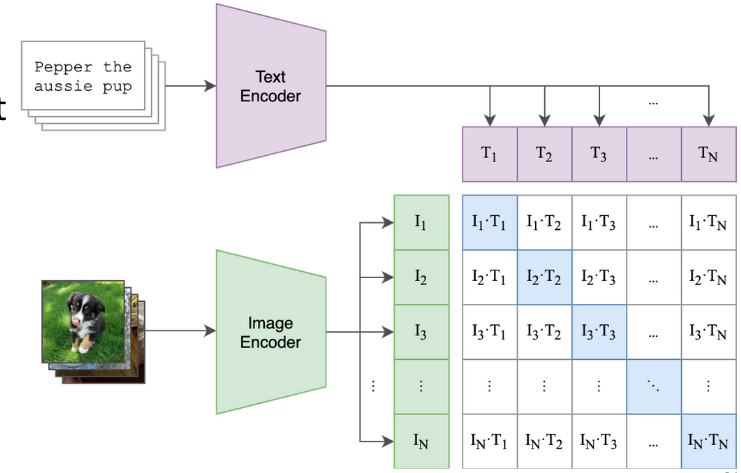
Then we use cross-entropy loss to make the diagonal entries close to $1$ and the off-diagonal entries $0$.
Give the @algorithm used for calculating the loss of the CLIP image encoder and text encoder in this context.
# image_encoder - ResNet or Vision Transformer
# text_encoder  - CBOW or Text Transformer
# I[n, h, w, c] - minibatch of aligned images
# T[n, l]       - minibatch of aligned texts
# t             - learned temperature parameter

# extract feature representations of each modality
I_f = image_encoder(I)   # [n, d_e]
T_f = text_encoder(T)    # [n, d_e]

# scaled pairwise cosine similarities [n, n]
logits = dot(I_f, T_f.T) * exp(t)

# symmetric loss function
labels = arange(n)
loss_i = cross_entropy_loss(logits, labels, axis=0)
loss_t = cross_entropy_loss(logits, labels, axis=1)
loss = (loss_i + loss_t) / 2
Give the @algorithm used for calculating the loss of the SigLIP image encoder and text encoder.
:
# img_emb : image model embedding [n, dim]
# txt_emb : text model embedding [n, dim]
# t_prime, b : learnable temperature and bias
# n : mini-batch size

t = exp(t_prime)
zimg = l2_normalize(img_emb)
ztxt = l2_normalize(txt_emb)
logits = dot(zimg, ztxt.T) * t + b
labels = 2 * eye(n) - ones(n)   # -1 with diagonal 1
l = -sum(log_sigmoid(labels * logits)) / n
What is “ranking loss” in the context of representation learning?
Ranking loss generalises the triplet loss (∆triplet-loss-definition) from one positive and one negative per anchor to many positives and many negatives.
- Goal: every positive should be more similar to the anchor than every negative, so all positives outrank all negatives in similarity.
- Ranked positives: sometimes the positives themselves carry an ordering (some are more relevant than others), and the loss should reproduce that ranking, not merely push every positive above every negative.
- Construction: a ranking loss is typically assembled from pairwise terms (e.g. a triplet or hinge term for each positive-negative pair) summed over all pairs.
Why it matters: this is the natural loss for retrieval, where the output is an ordered list and getting the order right, not just which items are returned, is what counts.
Why is representation learning useful for retrieval problems?
In retrieval problems, there is either not a predefined set of classes or the set of classes is too large to train a classifier. For representation learning we don’t require a list of classes, and can just instead return similar examples.
Bite-sized
@Justify why negative examples are essential for representation learning, with reference to degenerate solutions.
Without negatives, a representation-learning objective that only enforces “matching pairs should be close” can be minimised trivially by collapsing the embedding to a constant: $f(\pmb x) = \pmb c$ for all $\pmb x$. Then any pair has cosine similarity 1, the positive-pair loss is zero, and the model has learned nothing useful.
Negatives prevent collapse by adding the opposing pressure that non-matching pairs should be dissimilar. This forces the model to use the embedding space’s full geometry — and explains why contrastive losses (InfoNCE, NT-Xent, triplet) all involve a negative term.
DINO avoids explicit negatives but only by using centring + sharpening of the teacher distribution — a different anti-collapse trick. The principle is the same: something has to push apart non-matching content.
CLIP was introduced by Radford et al., 2021 (“Learning transferable visual models from natural language supervision”) and trained on 400M image-text pairs scraped from the web. Architecture: separate image and text encoders + contrastive InfoNCE-style loss over a similarity matrix of in-batch pairs.
Cosine similarity between two non-zero vectors $\pmb u, \pmb v$ is defined as $\mathcal S _ {\cos}(\pmb u, \pmb v) = <span class="cloze" tabindex="0">\dfrac{\pmb u^\top \pmb v}{\ \vert \pmb u\ \vert \, \ \vert \pmb v\ \vert }</span>$. It is $1$ for collinear same-direction vectors, $0$ for orthogonal, $-1$ for opposite. Scale-invariant, so it depends only on the direction of the embedding, not its magnitude.
The “contrastive loss” used in CLIP and SimCLR has many names — the lecture explicitly notes the proper name is InfoNCE (Information Noise-Contrastive Estimation), introduced by van den Oord et al. 2018 (originally called CPC). The earlier Noise-Contrastive Estimation (NCE) is due to Gutmann & Hyvärinen 2010 and aims to distinguish data from noise via logistic regression.
@Describe the “Apple/iPod” adversarial example that demonstrates CLIP-like models learn to read text in images.
A photo of an apple with a sticky note saying “iPod” stuck to it. CLIP’s classification:
- Prompt “an apple”: 42% confidence on iPod image, 78% on real apple. Without the text being relevant, CLIP still leans correctly toward “apple” — but only weakly.
- Prompt “a picture of an apple”: 56% / 91%.
- Prompt “an ipod”: 60% confidence on iPod-labelled apple, 0% on plain apple.
- Prompt “an apple with a note saying ‘ipod’”: 99% / 0% — i.e. CLIP can correctly identify the whole adversarial configuration if you describe it explicitly.
The key takeaway: CLIP’s training data has many images that contain text, so CLIP has implicitly learned that the text in an image is a strong cue for the image’s class. A sticky note saying “iPod” overrides the visual content. This is an adversarial attack by text and works against many production VLMs.
@Describe the multi-modal representation learning recipe.
Goal: learn a common embedding space for two modalities (e.g. image + text, image + audio, vision + 3D), where matching cross-modal pairs land close together.
Recipe:
- One encoder per modality: $f _ A : \mathcal D _ A \to \mathbb R^d$, $f _ B : \mathcal D _ B \to \mathbb R^d$. Architectures differ (CNN for images, transformer for text, etc.) but the output dimension $d$ is shared.
- Training pairs: data is naturally paired across modalities (image with caption, video with soundtrack, photo with text description).
- Contrastive loss across modalities: pull matching cross-modal pairs together (high similarity), push non-matching pairs apart. CLIP-style symmetric InfoNCE is the standard form.
- Optional projection heads: small MLPs after each encoder to project into a shared “contrastive space” without disturbing the deeper features (SimCLR-style).
Resulting embedding space lets you do zero-shot classification (compare image embedding to text embeddings of class names) and cross-modal retrieval (find images matching a text query, or vice versa).
SeLaVi (Asano et al., 2020) is a multi-modal representation learning method that trains audio-visual embeddings from videos with sound. It uses Sinkhorn clustering (an optimal-transport variant of clustering) to alternate between learning representations and assigning pseudo-labels, similar to Self-Labelling.
@Justify why the triplet loss gives a more flexible learning signal than the cosine-similarity loss.
- Cosine similarity loss enforces an absolute target: positive pairs should approach similarity 1, negative pairs should approach similarity −1 (or 0, depending on normalisation). This is a strong constraint that may not be satisfiable — e.g. two views of the same object will never have identical feature vectors after data augmentation, so the loss can never reach 0.
- Triplet loss $\max(0, \mathcal S(\phi, \phi^-) - \mathcal S(\phi, \phi^+) + \varepsilon)$ enforces a relative target: positive should just be more similar than negative by some margin $\varepsilon$. This is a much weaker constraint that always has feasible solutions.
- The triplet loss is also zero once the margin is satisfied, so easy-correctly-classified triplets do not pull on training, and the loss focuses on hard examples (those still violating the margin).
This makes triplet loss numerically more stable and converges better in practice, especially when paired with hard-negative mining to find difficult-but-informative triplets.
The contrastive loss formulated as a softmax cross-entropy is
\[\mathcal L _ \text{cont}(\phi _ i, \phi _ i^+) = -\log \dfrac{\exp(\mathcal S(\phi _ i, \phi _ i^+))}{\sum _ {k=1}^B \exp(\mathcal S(\phi _ i, \phi _ k))}\]The denominator sums over all $B$ batch elements, so the other $B-1$ elements implicitly act as negatives.
SigLIP differs from CLIP by using a pairwise sigmoid (binary) loss on each entry of the similarity matrix, rather than a softmax cross-entropy over rows/columns. The sigmoid form makes each entry an independent binary classifier (match vs no-match), which scales much better with batch size and across GPUs because no normalisation across the whole batch is required.
The lecture notes a strong practical advantage of representation learning for retrieval: in retrieval, the set of classes is either undefined a priori (e.g. open-vocabulary fine-grained species recognition like iNaturalist with 463k species) or so large that training a classifier with one output per class is infeasible. Representation learning bypasses this entirely by learning an embedding space and using nearest-neighbour lookup at query time.
Visualising the SigLIP loss
SigLIP (∆siglip-pseudocode) turns the image-text similarity matrix into $n^2$ independent sigmoid classifications, each pair pushed up or down on its own, in contrast to CLIP’s (∆clip-pseudocode) per-row softmax. Drag the temperature, bias and training sliders to watch each pair move along its loss curve, and hover the pseudocode lines to map them onto the figure.