Computer Vision MT25, Subsampling and upsampling
Flashcards
Suppose you want to reduce the resolution of an image by a factor of $2^n$. What goes wrong with the simple approach of deleting every pixel with coordinates that are not a multiple of $2^n$?
You get aliasing problems in high-frequency regions.
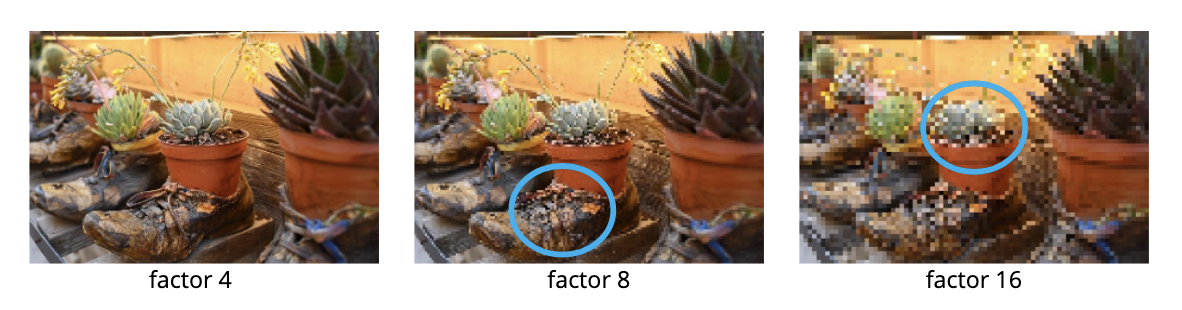
Suppose you want to reduce the resolution of an image by a factor of $2^n$. One approach to do this is deleting every pixel with coordinates that are not a multiple of $2^n$, but this has aliasing problems in high-frequency regions.
What’s one way you can get around this?
Remove high-frequency details by blurring first, and then subsampling.
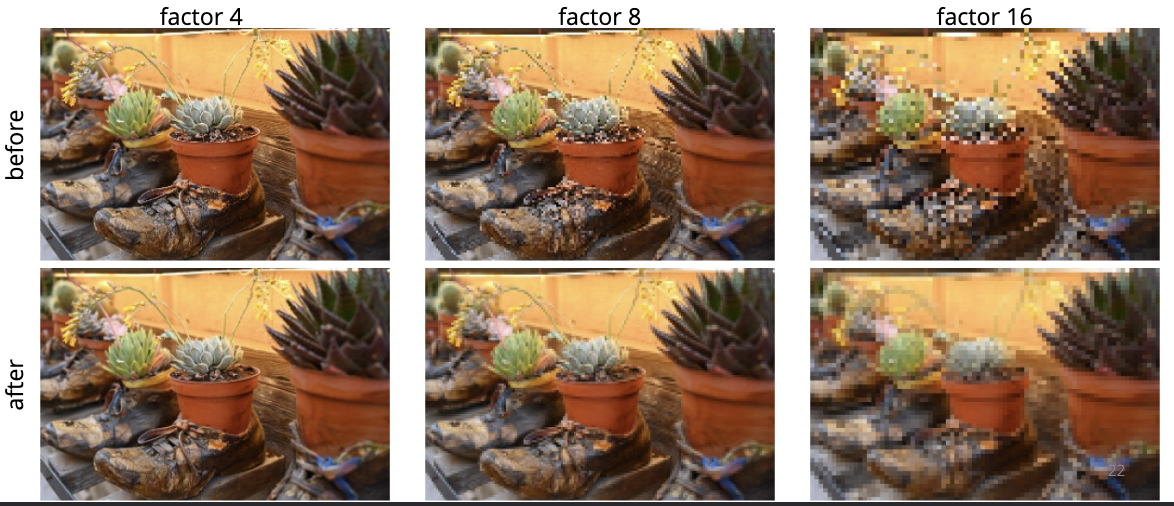
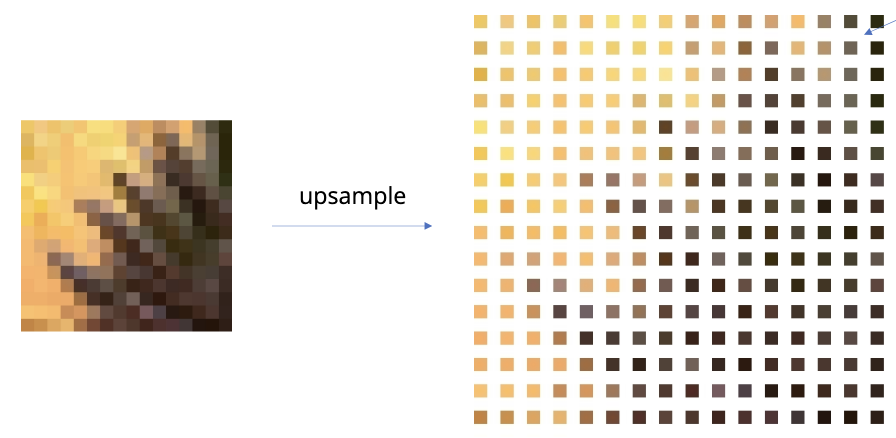
Suppose you want to increase the resolution of an image by a factor of $2$. One way to do this is to double the pixel coordinates, but this introduces gaps between the pixels.
If $A$, $B$, $C$, $D$ are the four corners of one “square” in the image, @state how bilinear interpolation would fill in the remaining values of the $5$ empty squares forming a cross inside the square.
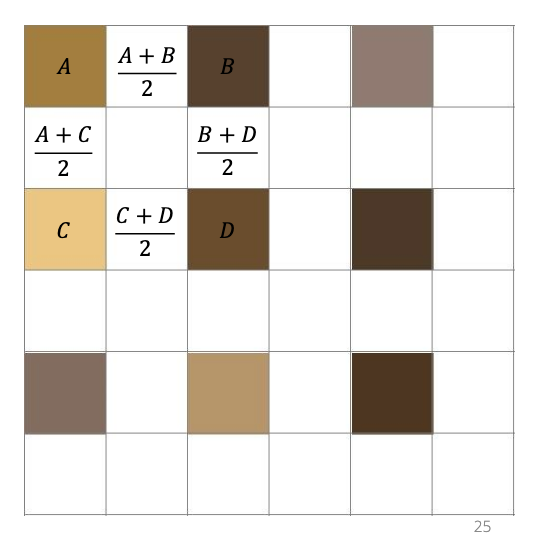
and the middle has
\[\frac{A + B + C + D}{4}\]In general, this process can be seen as first averaging the values of the horizontal and vertical pixels, and then using these new values to find the value of the middle pixel.
Suppose you have four pixels arranged in a square with values $A, B, C, D$ and located at $(x _ 1, y _ 1), (x _ 2, y _ 1), (x _ 1, y _ 2), (x _ 2, y _ 2)$. Given some coordinate $(x, y)$ inside the square, @state the formula used by generalised bilinear interpolation to give a value to $(x, y)$.
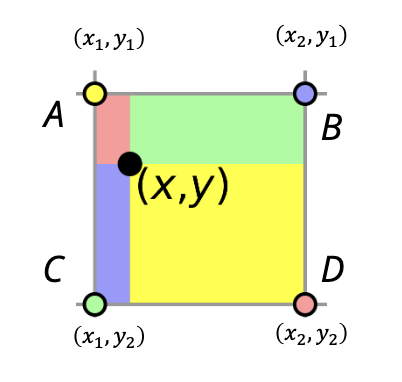
where
\[\begin{aligned} w _ {11} &= \frac{(x _ 2 - x)(y _ 2 - y)}{(x _ 2 - x _ 1)(y _ 2 - y _ 1)} \\ w _ {21} &= \frac{(x - x _ 1)(y _ 2 - y)}{(x _ 2 - x _ 1)(y _ 2 - y _ 1)} \\ w _ {12} &= \frac{(x _ 2 - x)(y - y _ 1)}{(x _ 2 - x _ 1)(y _ 2 - y _ 1)} \\ w _ {22} &= \frac{(x - x _ 1)(y - y _ 1)}{(x _ 2 - x _ 1)(y _ 2 - y _ 1)} \end{aligned}\]This looks complicated, but there is quite an easy way to remember it: the weight at a point is the ratio of the area of the opposite sub-cell (identified by colours in the picture above) to the area of the overall cell.
@Define nearest-neighbour interpolation.
Interpolated values are taken from the closest point.
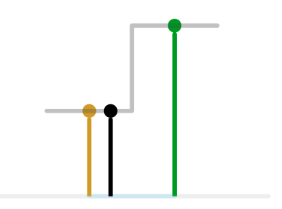
@State a useful property of nearest neighbour interpolation.
It only uses values already in the data.
@State a useful property of linear interpolation, compared to quadratic or cubic interpolation.
It does not create samples outside the range of interpolants.
@State a useful property of cubic interpolation.
It is differentiable everywhere.
Bite-sized
Bilinear interpolation at the midpoint of a single edge AB is just the average: $f(\tfrac{1}{2}, 0) = (A + B)/2$. The middle of a $2 \times 2$ block of corners $(A, B, C, D)$ is the average of all four: $f(\tfrac{1}{2}, \tfrac{1}{2}) = <span class="cloze" tabindex="0">(A + B + C + D)/4</span>$. This is well-defined regardless of whether you average horizontally-first then vertically or vice versa — both give the same answer.
@Justify why bicubic interpolation is preferred over bilinear when image quality matters, despite being more expensive.
- Bilinear is C0-continuous (the function value is continuous across pixel boundaries) but its first derivative is not — there’s a kink at every pixel. This produces visible banding artefacts in smooth areas and a slightly “soft” appearance.
- Bicubic uses a cubic spline that is C1-continuous (the first derivative is also continuous), so smooth gradients in the original image remain smooth in the interpolated output.
Trade-offs:
- Cubic samples can fall outside the range of interpolants (overshoot near edges), which can produce ringing artefacts. Bilinear cannot do this.
- Bicubic is ~4x more expensive than bilinear (uses 16 input pixels vs 4 per output pixel) but still cheap enough for real-time use.
The lecture lists three named methods (nearest-neighbour, bilinear, bicubic). For most practical CV tasks bilinear is the default; bicubic shows up when you specifically need smoothness (e.g. photo upscaling).
Naive subsampling (just deleting non-multiple-of-$2^n$ pixels) produces aliasing artefacts especially in high-frequency regions of the image — fine textures, edges, regular patterns. The fix is to blur first (low-pass filter) before subsampling, removing the high frequencies that would otherwise alias.
@Justify the choice between nearest-neighbour, bilinear, and bicubic interpolation for the three CV use cases: integer pixel labels, smooth photo upscaling, image rotation by arbitrary angle.
- Integer pixel labels (e.g. semantic-segmentation maps where each pixel has a discrete class index): use nearest-neighbour. Bilinear/bicubic would produce fractional class indices that have no meaning. NN preserves the discrete-label structure.
- Smooth photo upscaling (e.g. enlarging a photo for printing): use bicubic. Smoothness matters for visual quality; mild ringing near edges is acceptable.
- Image rotation by arbitrary angle (e.g. data augmentation in training): use bilinear. Cheap, no kinks in smooth areas, no ringing — and we’re going to feed the result into a CNN that handles minor artefacts gracefully anyway.
The general principle: more-smoothness methods (bicubic > bilinear > NN) are visually nicer but more expensive and can create out-of-range values. NN is exact-preserving but rough. Match the method to the constraints of the downstream task.