Computer Vision MT25, Video
Flashcards
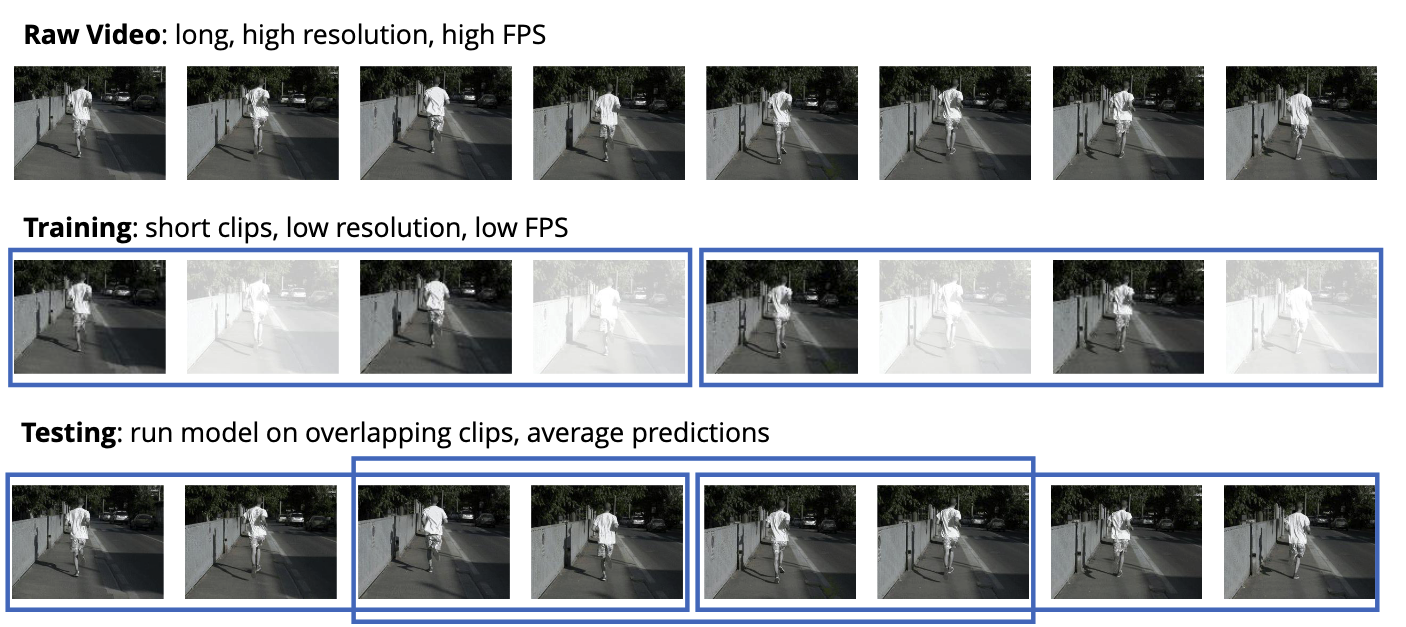
One problem with video processing models is that videos are too big. @Visualise and @describe one way that this is avoided at training time versus test time.
You can train on short clips with low resolution and low FPS, and then at test time run the model on overlapping clips and average the predictions.
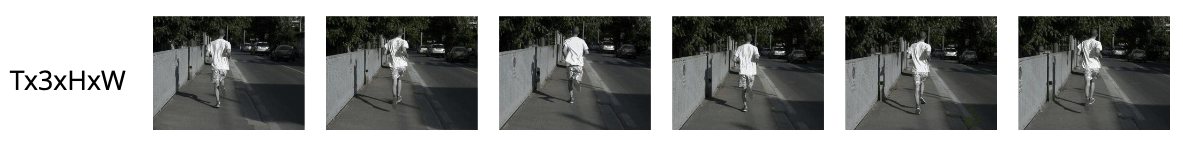
How might a per-frame model classify the activity contained in a video?
- Predict for each frame independently with an image model
- Average the probabilities for each frame together
@Define the object-bias of action recognition.
The observation that for many actions, only one frame of a video of that activity is needed to classify that activity.
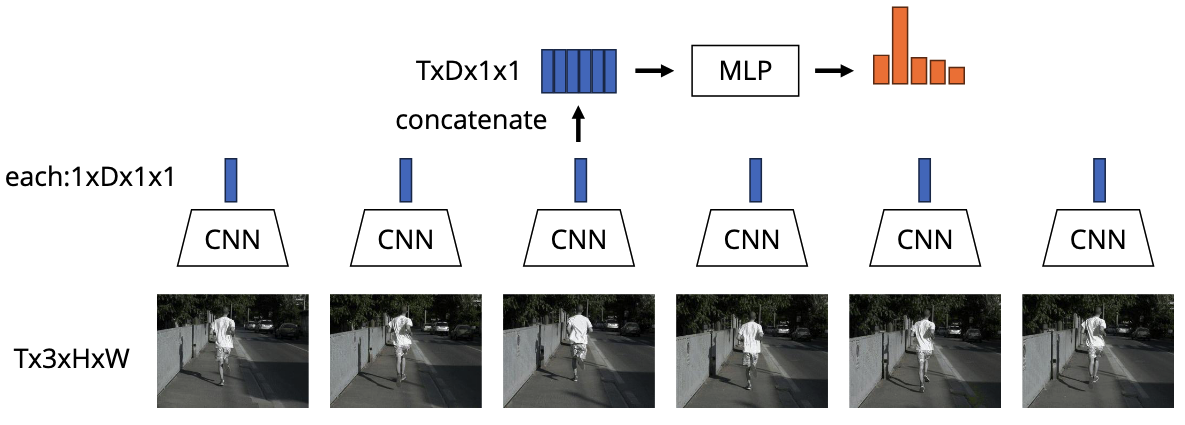
What is the primary problem with late fusion?
Low-level motion is often lost after compressing a frame into a feature vector.
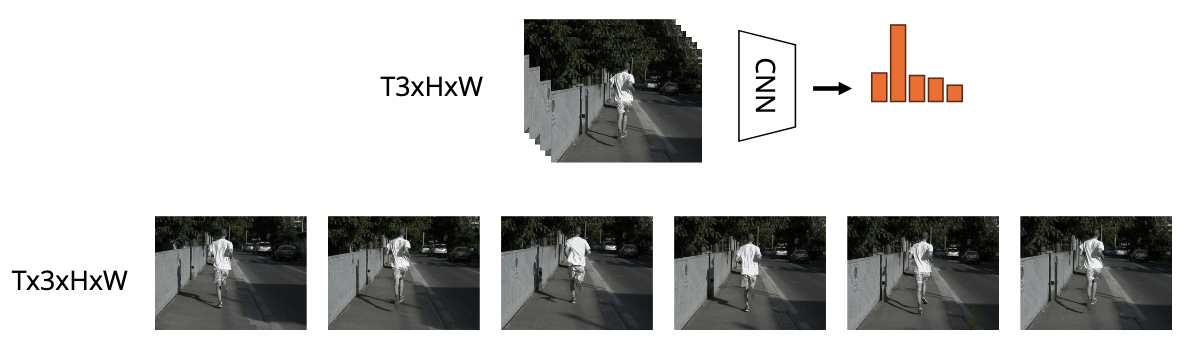
How could you implement “slow fusion” in a CNN?
Use 3D convolutions to slowly compress the temporal information.
@Visualise the architecture used for action recognition with optical flow.
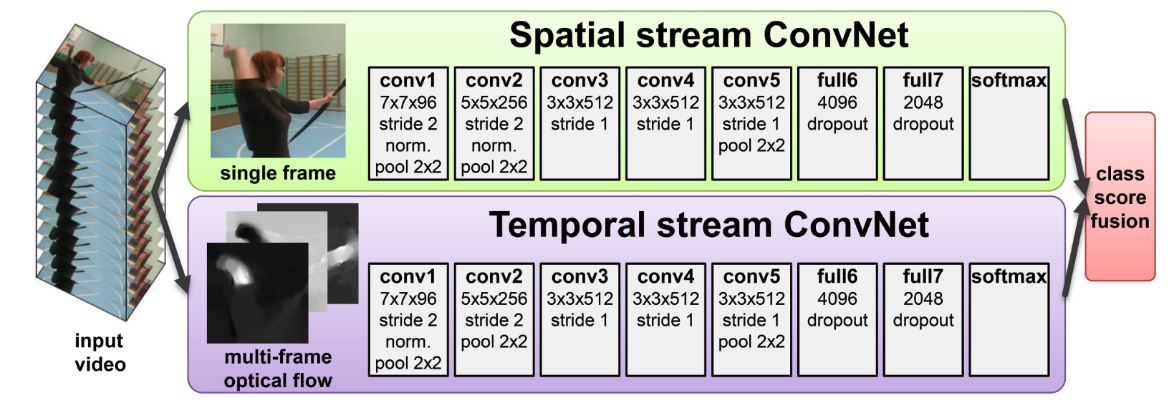
In “Two-stream convolutional networks for action recognition in videos”, we classify actions in videos using an architecture like the following:
Can you remember what the inputs to both of the two streams are?
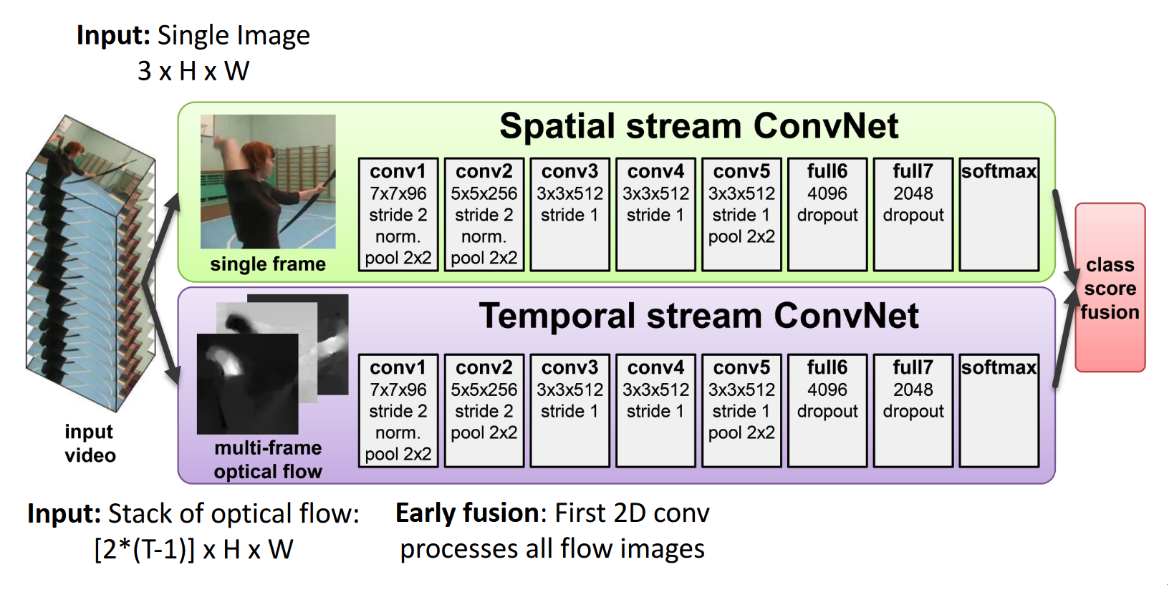
- Single input image in the first stream: $3 \times H \times W$
- Stack of optical flow in the $x$ and $y$ directions across all the whole $T$ frames in the video: $[2 \times (T - 1)] \times H \times W$.
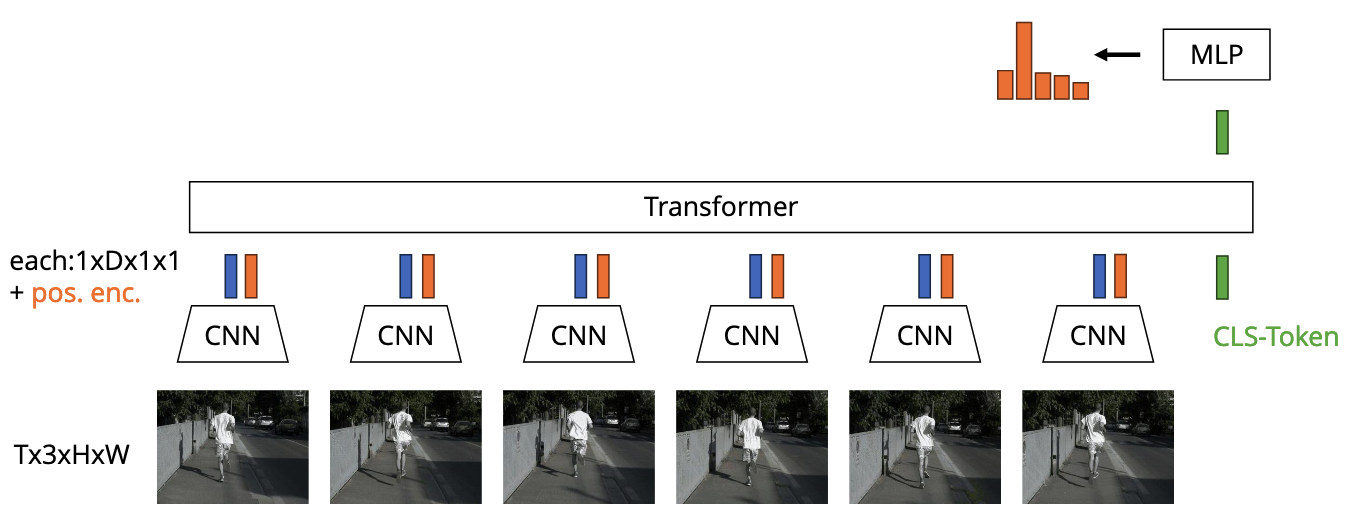
@Visualise how a transformer and a CNN together could be used for action recognition in a video over a long temporal context.
@Visualise how a pure transformer architecture could be used for video understanding over a long temporal context. What are the names given to the tokens in this context? What do they represent intuitively?
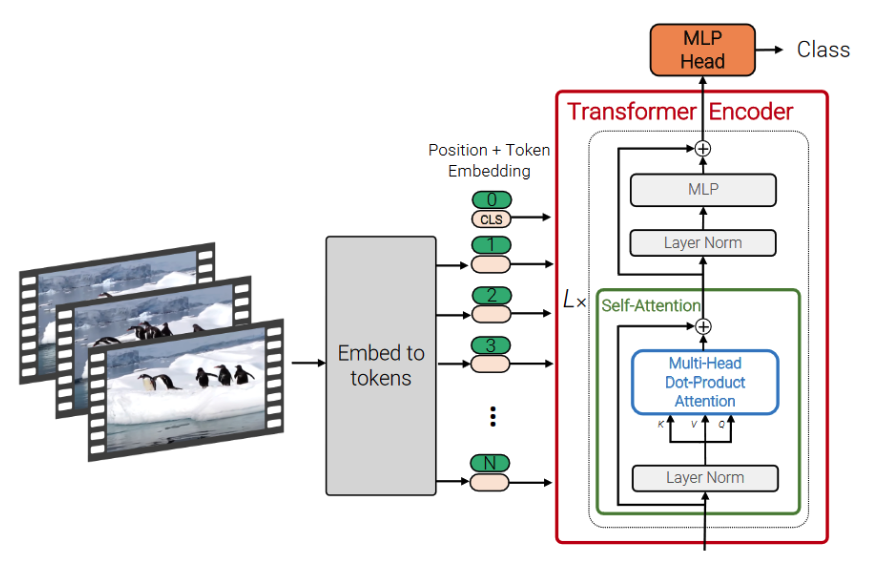
The tokens are spatio-temporal tokens: each token comes from a patch in space and time.
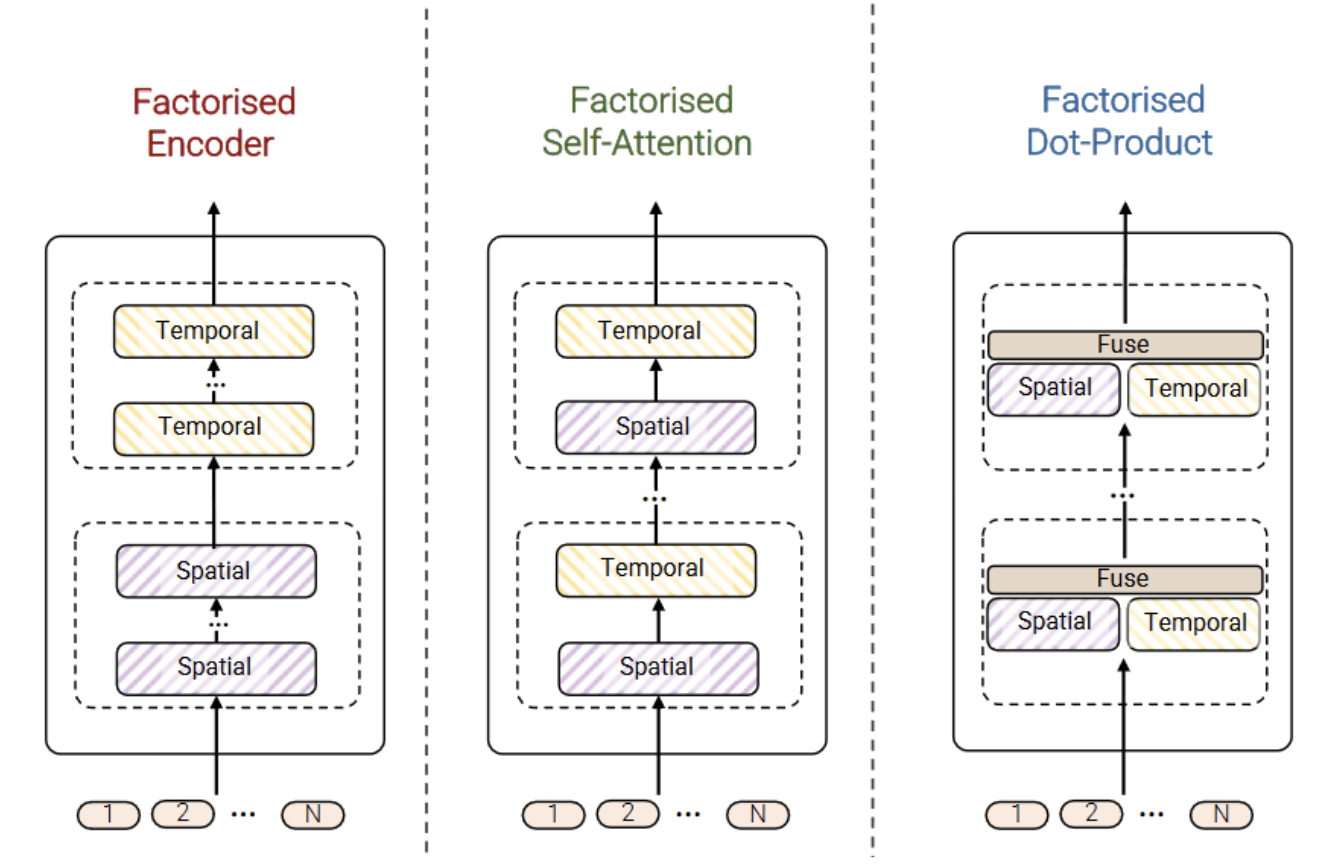
The Video Vision Transformer (ViViT) extends ViT (∆vision-transformer-architecture) to video by tokenising spatio-temporal patches, so that each token corresponds to a small patch in space and time. Naïve self-attention over all $THW$ tokens has $O((THW)^2)$ complexity, which is prohibitive for typical video sizes. ViViT introduces three factorised attention strategies that reduce the cost by separating attention over space and time.
@Describe the three factorised attention strategies introduced in ViViT.
We use two new primitives:
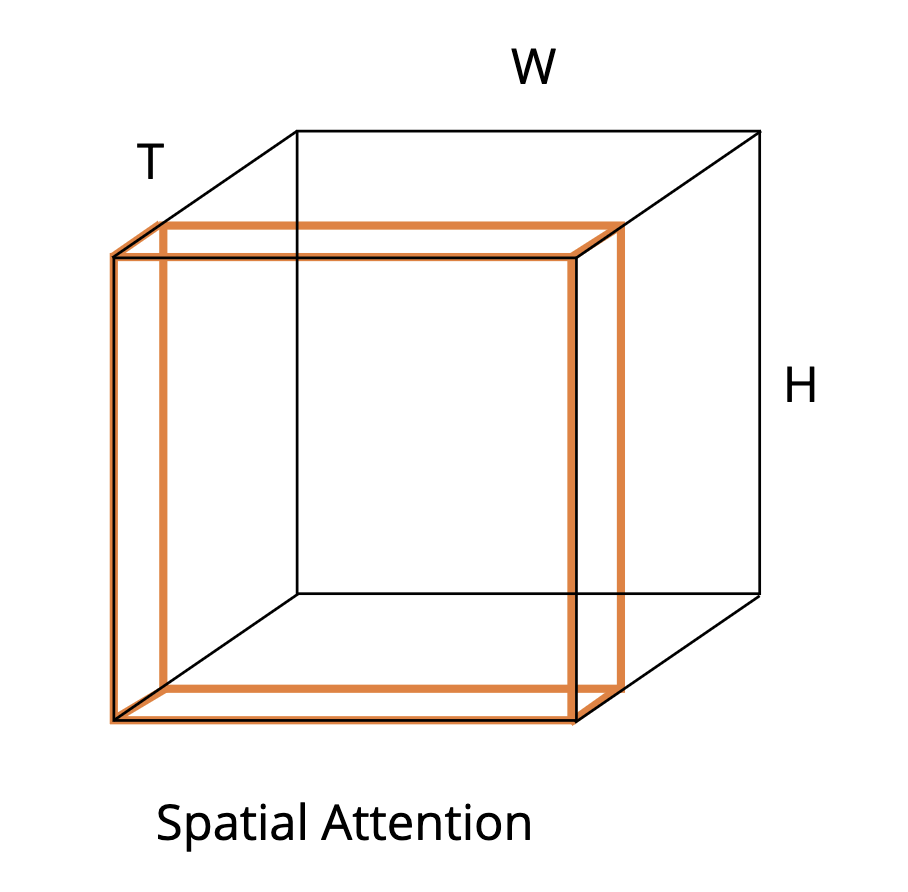
- ∆spatial-attention: attention performed spatially across the image, independently for each time step
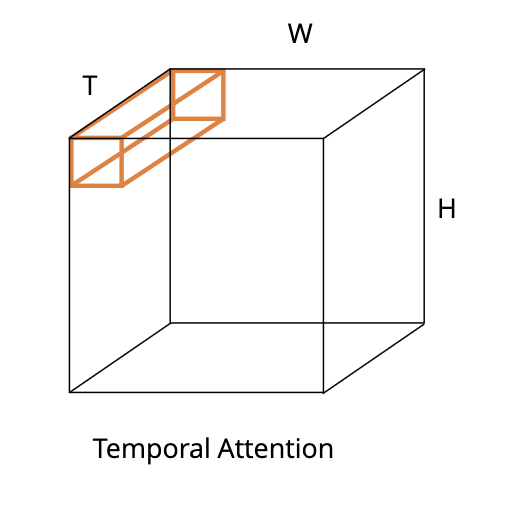
- ∆temporal-attention: attention performed temporally across the video, independently for each spatial location
Then we have:
- Factorised encoder:
- Two separate transformer encoders: one spatial (per frame), one temporal (across frames).
- Apply the spatial encoder to each frame independently to produce a per-frame summary, then apply the temporal encoder to the sequence of summaries.
- Factorised self-attention:
- Within each transformer block, alternate a spatial-attention layer and a temporal attention layer.
- Each block does both, but at different sub-layers.
- Factorised dot-product:
- Spatial and temporal attention computed in parallel (not alternating), then fused.
- Each attention head is dedicated to either spatial or temporal attention, and the results are concatenated.
Suppose we have a
\[B \times T \times D \times H \times W\]
input. @State the steps of a temporal attention block.
- Permute: $B \times H \times W \times T \times D$
- Flatten: $BHW \times T \times D$
- Attention: $BHW \times T \times D \to BHW \times T \times D$ (so here the height and width basically become part of the batch, and are processed independently for each spatial location)
- Unflatten: $B \times H \times W \times T \times D$
- Permute: $B \times T \times D \times H \times W$
Suppose we have a
\[B \times T \times D \times H \times W\]
input. @State the steps of a spatial attention block.
- Permute: $B \times T \times H \times W \times D$
- Flatten: $BT \times HW \times D$
- Attention: $BT \times HW \times D \to BT \times HW \times D$ (so here the time effectively becomes part of the batch, and each time step gets processed independently)
- Unflatten: $B \times T \times H \times W \times D$
- Permute: $B \times T \times D \times H \times W$
ViViT (∆vivit-factorised-attention-strategies) extends ViT (∆vision-transformer-architecture) to video using spatio-temporal tokens. Naïve self-attention over all tokens so factorising attention separately over space (∆spatial-attention) and time (∆temporal-attention) is much cheaper.
@State and compare the complexity of full vs factorised attention (i.e. combining both spatial and temporal attention) for video, given $T$ frames each with $H \times W$ spatial tokens.
Full attention (every token attends to every other token across space and time):
- Total tokens: $THW$
- Complexity: $O((THW)^2)$
Factorised attention (alternating temporal and spatial tokens):
- Temporal attention: There is one $T \times T$ attention per $HW$ locations. Complexity $O(T^2 \times HW)$
- Spatial attention: Process each frame separately, attending across $HW$ spatial tokens. One $HW \times HW$ attention for each $T$ frames. Complexity $O(T \cdot (HW)^2)$.
- Total: $O(T^2 HW + T(HW)^2)$
The factorisation replaces a single $(THW)^2$ term with the sum of two smaller terms.
Bite-sized
ViViT (Video Vision Transformer) was introduced by Arnab et al., ICCV 2021. It extends ViT to video by tokenising the input into spatio-temporal patches and applying transformer encoders.
A raw HD video at 30fps for 1 minute occupies $60 \times 30 \times 3 \times 1080 \times 1920 \approx <span class="cloze" tabindex="0">11</span>$ GB of pixel data. This is why video CV pipelines almost always subsample in space (lower resolution) and time (lower FPS), and process short clips rather than full videos.
@Describe the windowed video processing recipe: how full-length videos are handled at training vs test time despite their size.
- Training: extract many short clips from each video (e.g. 16 frames at low FPS and low spatial resolution — e.g. $112 \times 112$). Each clip is one training sample. This makes individual forward/backward passes affordable and lets the GPU process whole batches.
- Testing: process overlapping clips across the test video and average the per-clip predictions. The overlap ensures no portion of the video is missed; the averaging smooths over per-clip noise.
This mirrors the patch-then-aggregate pattern used elsewhere in CV (e.g. sliding-window classification, dense prediction). The principle: don’t try to process the whole signal at once — break it into manageable pieces and aggregate.
The lecture compares per-frame, late, early, and slow fusion. The Karpathy et al. (2014) ablation shows that single-frame baselines are surprisingly strong, and slow fusion beats early/late fusion — but no fusion approach is dramatically better than a strong per-frame classifier, because most CV action labels are dominated by object-bias (a single frame is often enough to identify the action).
@Describe the 3D convolution operation as a generalisation of 2D convolution, and what changes about input/output tensor shapes.
A 2D convolution takes an input of shape $(C, H, W)$, convolves with $N$ filters of shape $(C, h, w)$, and produces an output of shape $(N, H, W)$ (with appropriate padding). The convolution slides spatially in 2D but operates over all channels.
A 3D convolution generalises this to a third dimension (depth or time):
- Input: $(C, D, H, W)$ where $D$ is the depth/time dimension.
- Filters: $N$ filters of shape $(C, d, h, w)$.
- Output: $(N, D, H, W)$ (with appropriate padding).
The convolution now slides in three directions: depth, height, and width. The channel dimension is still consumed by the dot product, just as in 2D.
Naming convention: “3D conv” refers to spatial-and-time, not 4D. The channel dimension is “ignored” in the naming. So a 3D conv has 5D weight tensors and 4D feature tensors.
3D conv pooling, fully connected layers, and activations all work analogously.
The two-stream architecture for action recognition (Simonyan & Zisserman, NeurIPS 2014) combines a spatial stream taking a single RGB frame and a temporal stream taking a stack of optical-flow frames. Two-stream fusion (by SVM) gives 88% on UCF-101 vs 73% spatial-only vs 84% temporal-only.
@Justify why the factorised attention strategies in ViViT save compute compared to full $O((THW)^2)$ attention.
A full attention layer over a $T \times H \times W$ spatial-temporal token grid has $THW$ tokens, so naive self-attention is $O((THW)^2)$ in operations. For a modest $T = 16, H = W = 14$ this is $(16 \cdot 196)^2 \approx 10^7$ operations per layer, which is barely affordable; doubling any dimension makes it infeasible.
Factorised attention separates the costs:
- Spatial attention: at each timestep, attend across $HW$ spatial tokens. Cost per timestep is $(HW)^2$; total $T \cdot (HW)^2$.
- Temporal attention: at each spatial location, attend across $T$ temporal tokens. Cost per location is $T^2$; total $T^2 \cdot HW$.
Sum: $O(T^2 HW + T (HW)^2)$. Compare with $(THW)^2 = T^2 H^2 W^2$:
- The full cost is proportional to $T^2 H^2 W^2$.
- The factorised cost is proportional to $T(HW)^2 + T^2(HW) = (T + HW) \cdot THW$ (ish).
So we go from quadratic in $THW$ to roughly linear in $THW$ multiplied by the smaller factor. For typical video sizes where $HW \gg T$, factorised attention is ~$\frac{1}{T}$ as expensive.
Trade-off: each block can no longer model arbitrary spatio-temporal interactions in a single attention pass. But by stacking spatial + temporal attentions, the model can still represent all such interactions across depth — just at much lower cost per block.
The Karpathy et al. (2014) “Large-Scale Video Classification with Convolutional Neural Networks” paper introduced four fusion strategies for video CNNs: single-frame, late fusion, early fusion, slow fusion. These are not named architectures (like ViViT) but a categorisation of how temporal information enters the network: late = at the top (after per-frame features), early = at the input, slow = gradually through the network via 3D convs.

Tubelets are bounding boxes that change over time, i.e. a 3D box (or “tube”) in spatio-temporal space rather than a static 2D rectangle. They are the natural primitive for spatio-temporal action detection.
The lecture flags lip-reading and audio description as examples of multi-modal video tasks. AutoAD (Han, Bain, Nagrani, Varol, Xie, Zisserman) addresses movie audio description as joint audio-visual-text prediction with long-range context dependencies.