Computer Vision MT25, Visual tracking
Flashcards
Suppose we have the following template and image:
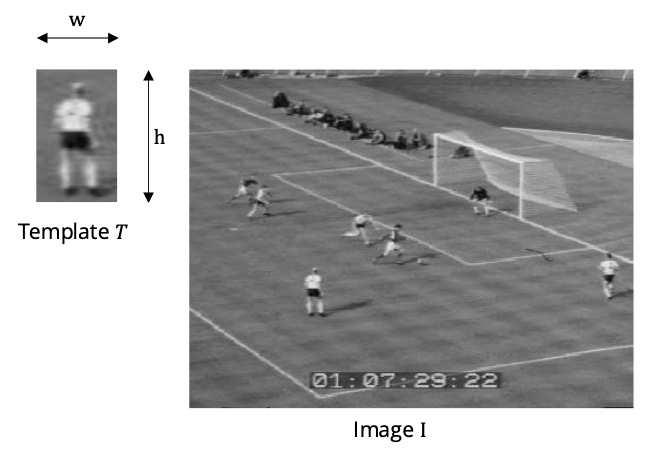
@State the energy function we would want to minimise in a template tracking context, and @visuallise what the energy might look like after it has been calculated.
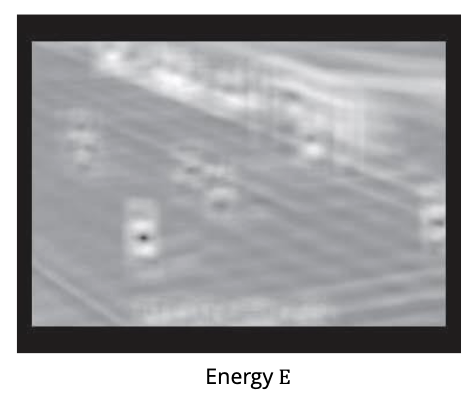
One approach to template tracking is to take a template $T$ and an image $I$, and calculate an energy function
\[E(u,v)
= \sum _ {(x,y)\in\left[-\frac{w}{2},\,\frac{w}{2}\right]\times\left[-\frac{h}{2},\,\frac{h}{2}\right]}
\left( I(u+x,\,v+y) - T\!\left(x+\frac{w}{2},\,y+\frac{h}{2}\right) \right)^{2}\]
What is the main problem with this approach?
It is very slow as you have to do many comparisons over many points in the image.
In template tracking, we have an image $I$ and a template $T$ and wish to minimise the energy
\[E(u, v) = \sum _ {x, y} \left( I(u+x, v+y) - T(x, y) \right)^2\]
Minimising this exactly is typically very expensive since you have to iterate over all the pixels in the image. Assuming we have some point $(t _ x, t _ y)$, how does Lucas-Kanade template tracking reformulate this energy function relative to an update $(\delta _ x, \delta _ y)$?
What is the primary problem with visual trackers relying too heavily on the spatial relationships between pixels? What’s one way of partially addressing this problem, and what’s the issue with this fix?
- They are prone to break due to partial occlusion and orientation changes in the scene.
- One fix is to update the template from frame to frame, but this can lead to drift.
A lot of approaches to visual tracking of many points are based on updating points using some estimate of local optical flow, but this has issues with occlusions. What’s one general approach for improving our estimates?
Predict the global changes for groups of points, rather than independently. This way e.g. positions of occluded points can be inferred from the others.
Bite-sized
@Describe the distinction between 2D tracking and 3D (pose) tracking in computer vision.
- 2D tracking: follow the image-plane position of an entity across frames. Output is a 2D bounding box, contour, point, or set thereof, updated frame-by-frame. Used for: object tracking in video, surveillance, gesture interfaces.
- 3D (or pose) tracking: use 2D image measurements (possibly via 2D tracking) to update the 6 degrees of freedom — 3 translation + 3 rotation — that define the entity’s 3D pose. Output is a $6 \times 1$ pose vector or $4 \times 4$ transformation matrix. Used for: AR/VR head tracking, robotic manipulation, autonomous driving.
3D tracking is strictly harder than 2D: you need a 3D model of the entity (or visual-SLAM-style scene mapping) and you have to reason about the pose-to-pixel projection. 2D tracking can be done from RGB pixel content alone.
The lecture’s primary focus is 2D tracking via Lucas-Kanade and its modern successors (PIPs, RAFT, CoTracker).
Modern point trackers covered in the lecture: PIPs, TAP-Net, RAFT, CoTracker, CoTracker3.
@Describe the CoTracker family’s main architectural idea, and what CoTracker3 adds over CoTracker.
CoTracker (Karaev et al., ECCV 2024): a transformer-based point tracker that tracks groups of points jointly rather than each point independently. Three factorised attention dimensions: space (across spatial locations within a frame), time (across frames for each point), group (across the tracked points themselves at a given time). This shared-context tracking gives:
- Global consistency: points move coherently rather than each drifting independently.
- Occlusion robustness: an occluded point’s location can be inferred from its visible companions.
Trained on synthetic data only.
CoTracker3 (Karaev et al., 2024) adds:
- Simpler architecture with 50% fewer parameters (0.2 ms/frame/point).
- Confidence prediction for each track.
- Two training flavours: an offline tracker that sees the whole video, and an online tracker for streaming.
- Pseudo-labelling on 15M real videos: train on synthetic, predict on real, retrain on those pseudo-labels.
SiamFC (Bertinetto, Valmadre, Henriques, Vedaldi, Torr, ECCV 2016) was the first deep-learning approach to tracking-by-detection. A shared CNN encoder $\phi$ produces features for the template patch ($127 \times 127 \times 3$ → $6 \times 6 \times 128$) and the search image ($255 \times 255 \times 3$ → $22 \times 22 \times 128$); cross-correlation produces a $17 \times 17 \times 1$ score map whose peak gives the new template location.
@Describe the Tracking-Learning-Detection (TLD) framework for robust 2D tracking.
TLD (Kalal, Mikolajczyk, Matas, 2010) integrates three components that compensate for each other’s failure modes:
- Tracker: a patch-based tracker (e.g. Lucas-Kanade or template matching) that follows the object frame-to-frame. Cheap but prone to drift over long sequences.
- Detector: a random-forest object detector localises the target object in each frame and corrects the tracker when it drifts. Robust to occlusion-then-reappearance.
- Learning: continuously improves the detector by using high-confidence tracker outputs as new training labels.
The principle: a tracker is fast but drifts, a detector is robust but cold-started; combine them so each helps the other. This is the same idea that re-emerges in CoTracker’s pseudo-labelling and in modern self-training pipelines.
The target is initialised by the user selecting a bounding box in a single frame.
@Describe the template appearance options for 2D tracking, in order of complexity.
What you can match across frames, simplest to most complex:
- Single point (e.g. a bright spot detector): tracks one pixel. Cheapest but extremely fragile — any noise or perspective change loses the point.
- Small patch (rigid): tracks a fixed-shape template via SSD or NCC. Robust to small noise but breaks under rotation, scale change, deformation.
- Small patch (deformable): tracks the patch under a parametric warp (translation+rotation+scale, or affine). Lucas-Kanade computes the warp update efficiently. Robust to small geometric changes.
- Contour (possibly deformable): tracks an outline rather than a region. Useful when the interior content varies but the silhouette is stable.
- Line element: tracks a 1D structure. Useful for engineering applications, road tracking, etc.
For 2D tracking, patches with deformable warps (LK-style) are the practical workhorse before deep learning. Modern methods (SiamFC, CoTracker) replace pixel-level matching with feature-level matching while keeping the patch-template framing.